
What is LongCat-2.0
LongCat-2.0 is a large-scale MoE language model open-sourced by Meituan, with 1.6 trillion total parameters and approximately 48 billion activated per token, with training and deployment completed on an AI ASIC supercomputing cluster. The model supports a 1M ultra-long context and introduces the LongCat Sparse Attention mechanism and N-gram Embedding architecture, delivering strong performance in scenarios such as code generation, Agent task execution, and complex reasoning, and is deeply integrated with mainstream tools such as Claude Code、OpenClaw、Hermes .
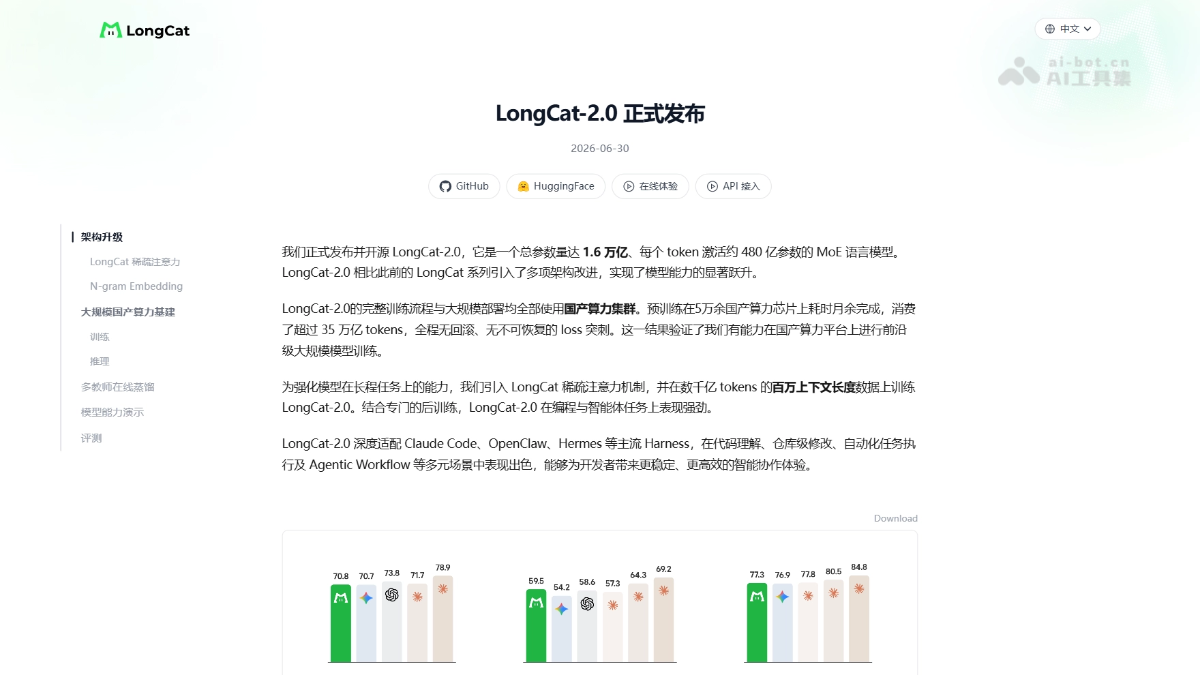
Main Features of LongCat-2.0
-
Ultra-Long Context Understanding: Native support for a 1M token context window, capable of reading an entire codebase or long documents in one pass for precise localization and deep understanding, avoiding the "lost in the middle" problem of traditional models.
-
Code Generation and Refactoring: Based on Agentic Coding capabilities, it supports repository-level code analysis, cross-file logic organization, architecture migration, and feature refactoring, passing compilation on the first try.
-
Autonomous Agent Execution: Deeply integrated with mainstream harnesses such as Claude Code, OpenClaw, and Hermes, it can autonomously complete multi-step task planning, tool invocation, API interaction, and error self-correction.
-
Multilingual Code Support: Possesses cross-language code understanding and generation capabilities, supporting code migration and review in multilingual programming scenarios such as Chinese and English.
-
Intelligent Search and Retrieval: Built-in search and browsing capabilities, supporting complex information retrieval, multi-hop reasoning, and cross-webpage content integration to meet research-oriented task needs.
-
Natural Language Data Querying: Business personnel can directly query databases in natural language, and the model automatically completes intent parsing, SQL generation, execution, and output of result insights.
- Multi-Precision Versions, Full-Platform Adaptation: Provides multiple precision versions such as BF16, FP8, and INT8, fully covering deployment needs across different computing power platforms.

Follow WeChat and reply "open source" to join theAI Open-Source Project Exchange Group
Technical Principles of LongCat-2.0
-
MoE Sparse Architecture: Adopts a mixture-of-experts architecture with 1.6 trillion total parameters and approximately 48 billion activated per token, balancing parameter scale and computational efficiency through sparse activation.
-
LongCat Sparse Attention (LSA): Introduces three major components—Streaming-aware Index (SI), Cross-Layer Index (CLI), and Hierarchical Index (HI)—reducing long-context attention computation from quadratic to linear and solving the bottleneck of processing million-token contexts.
-
N-gram Embedding: Configures a 5-gram embedding module, expanding the embedding space by approximately 100 times through token combinations, capturing richer local context and enhancing representational capability.
-
Zero-Compute Experts + ScMoE: Dynamically allocates computational resources according to token complexity; simple tokens are routed to zero experts to avoid ineffective computation, while complex tokens automatically receive more expert resources.
-
MOPD Multi-Expert Fusion Post-Training: Fuses three expert groups—Agent Experts, Reasoning Experts, and Interaction Experts—through the Multi-Teacher On-Policy Distill architecture, with a gating network dynamically scheduling the optimal expert combination according to task type.
-
6D Parallel Training: Adds EMBP on top of standard TP/CP/EP/DP/PP, combined with the Superpod physical cluster architecture to achieve ultra-large-scale efficient training.
How to Use LongCat-2.0
-
Online Experience: Visit the LongCat official website to chat and try the model's capabilities directly.
-
API Access: Log in to https://longcat.chat/platform/product to get an API Key and integrate it into your own application or Agent framework.
-
Tool Integration: Directly integrate with Claude Code、OpenClaw、Hermes and other mainstream AI development toolchains as the underlying model driver.
Core Advantages of LongCat-2.0
-
Full-Stack Domestic Compute: The industry's first model to complete full-process training and inference of a trillion-parameter model on a 50,000-GPU domestic cluster, validating the feasibility of non-NVIDIA platforms.
-
Million-Level Context: A 1M native context window, combined with LSA sparse attention, enables precise localization and understanding of long texts, saying goodbye to "lost in the middle."
-
Purpose-Built for Agentic Coding: Deeply optimized around code understanding, generation, and execution, surpassing Gemini 3.1 Pro and GPT-5.5 in benchmarks such as SWE-bench and Terminal-Bench.
-
Dynamic Compute Allocation: Zero-compute experts + ScMoE enable token-level dynamic activation (33B~56B); simple tokens consume no compute, while complex tasks automatically receive more resources.
-
Three-Expert Fusion: The MOPD architecture fuses the Agent, Reasoning, and Interaction expert groups, with a gating network dynamically scheduling them to balance execution, reasoning, and interactive experience.
-
Recognized by Developers Worldwide: The preview version is openly available via OpenRouter, with monthly call volume ranking among the global top three, ranking first, second, and third on Hermes, Claude Code, and OpenClaw respectively.
LongCat-2.0 Project Addresses
- Project Official Website:https://longcat.chat/blog/longcat-2.0/
- GitHub Repository:https://github.com/meituan-longcat/LongCat-2.0
- HuggingFace Model Library:https://huggingface.co/meituan-longcat/LongCat-2.0
LongCat-2.0 Comparison with Similar Competitors
| Comparison Dimension | LongCat-2.0 | DeepSeek-V3 |
|---|---|---|
| Publisher | Meituan | DeepSeek |
| Total Parameters | 1.6 trillion (MoE) | 671 billion (MoE) |
| Activated Parameters | ~48 billion / token | ~37 billion / token |
| Context Length | 1M (1 million) tokens | 64K-128K tokens |
| Training Hardware | 50,000-GPU domestic compute cluster | NVIDIA GPU cluster |
| Attention Mechanism | LongCat Sparse Attention (LSA) | Multi-head Latent Attention (MLA) |
| Embedding Optimization | N-gram Embedding (5-gram, 135B) | Standard embedding layer |
| Post-Training Architecture | MOPD multi-expert fusion (Agent/Reasoning/Interaction) | Standard SFT + RL |
| Code Capability (SWE-bench Pro) | 59.5 | ~50+ |
LongCat-2.0 Application Scenarios
-
Large-Scale Code Migration: Reads the complete codebase and migration documentation, automatically maps the architecture and refactors plugins to the new SDK, preserving functionality and fixing potential bugs.
-
Repository-Level Code Review: Understands the entire project structure based on the 1M context, performing cross-file bug detection, performance optimization, and architectural recommendations.
-
AI Agent Development: Serves as the underlying model to drive frameworks such as Claude Code and OpenClaw, executing complex multi-step tasks and autonomous tool calls.
-
Long Document Analysis and Generation: Processes million-word-level technical documents, papers, and reports for in-depth summarization, question answering, and content rewriting.
-
Data query and insights: Business users query the database in natural language, and the model automatically handles SQL generation, execution, and result interpretation.