
What is DeepSeek V3
DeepSeek V3 is the latest open-source AI model from DeepSeek (DeepSeek), an artificial intelligence company under the well-known private equity giant High-Flyer Quant. It has made significant progress in multilingual programming capabilities. In the aider multilingual programming benchmark, its performance surpassed competitors such as Claude 3.5 Sonnet V2. The latest version, DeepSeek-V3-0324, has 685 billion parameters, adopts a mixture-of-experts architecture, integrates multi-head latent attention and multi-token prediction technologies, and achieves an inference speed of 20 tokens per second. In programming assistance, DeepSeek-V3-0324 performs excellently, can easily generate complete front-end pages, and can replace junior programmers in completing most daily coding work. It has powerful long-text processing capabilities, can sort out complex logic chains, and is suitable for academic research and document analysis. Its conversational interaction capabilities have also improved, making conversations more natural and fluent. DeepSeek V3 has been open-sourced and can be viewed on Hugging Face.
Main features of DeepSeek V3
- Code generation: Can quickly generate high-quality code based on natural language descriptions entered by users, supporting multiple programming languages such as Python, JavaScript, Java, etc.
- Code optimization: Analyzes and optimizes existing code to improve code performance, readability, and maintainability.
- Debugging assistance: Helps users find errors and vulnerabilities in code and provides detailed error information and repair suggestions. When users encounter errors while running code, it can quickly locate the problem like an experienced programmer and provide possible solutions.
- Text generation: Can generate long, coherent texts such as novels, papers, reports, etc., based on topics or outlines provided by users.
- Text analysis: Conducts in-depth analysis of long texts, extracts key information, summarizes main content, sorts out logical structure, etc.
- Text polishing: Adjusts and polishes the language style of user-provided text, making it more smooth, natural, and in line with a specific writing style.
- Natural conversation: Can engage in smooth and natural conversations with users, understand their questions, and provide accurate answers.
- Multi-turn conversation: Supports multi-turn conversations, can understand and answer follow-up questions based on contextual information, and maintains the coherence and consistency of the conversation.
- Personalized conversation: Provides personalized conversational experiences based on user preferences and historical records.
- Training efficiency: Supports FP8 mixed-precision training, improving training speed and reducing GPU memory usage. Designs the DualPipe algorithm to achieve efficient pipeline parallel processing. Optimizes cross-node All-to-All communication, fully utilizing InfiniBand and NVLink bandwidth.
- Pre-training and post-training: Pre-trained on 14.8T tokens, and through two-stage context extension, expanded the context window from 4K to 128K. Conducts supervised fine-tuning and reinforcement learning to align with human preferences and further unlock potential.
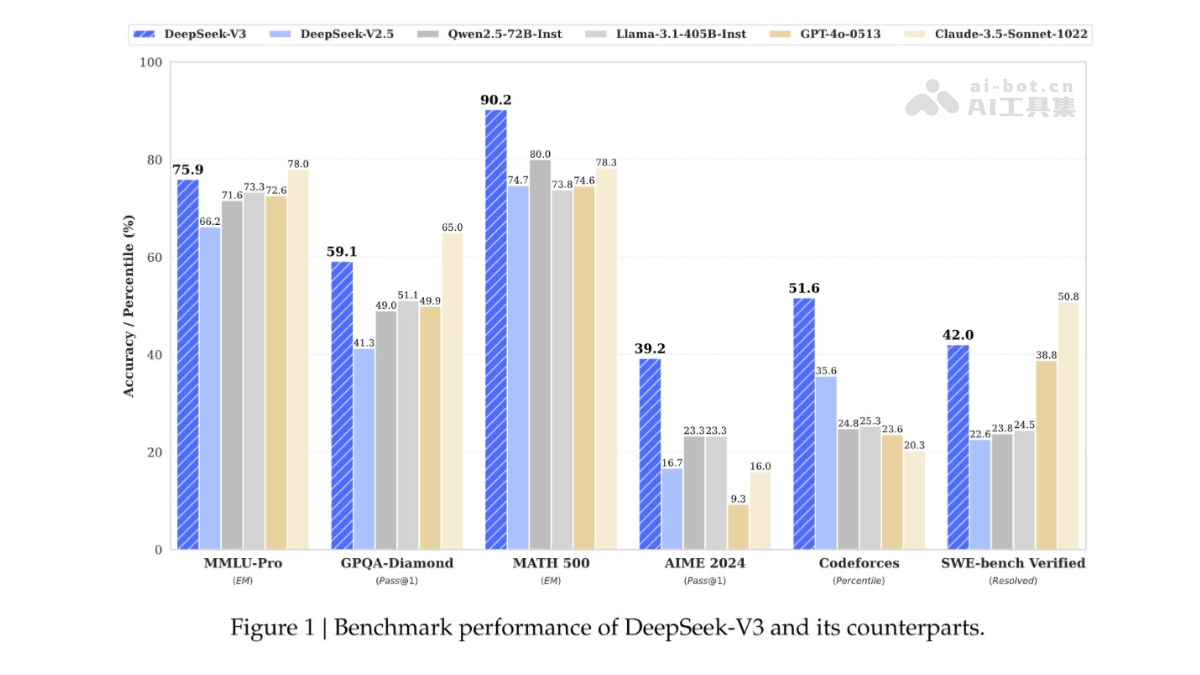
- Performance evaluation: In multiple standard and open-ended benchmark tests, DeepSeek-V3's base model performs excellently, especially in the code and mathematics domains. The chat version of DeepSeek-V3 also surpasses other open-source models and is comparable in performance to leading closed-source models.
- Cost-effectiveness: Training cost is only 2.788M H800 GPU hours, with a total cost of $5.576M.
- API and Web services: DeepSeek provides API and Web services, making it convenient for users to integrate and use in different scenarios.
- Multilingual processing capability: DeepSeek V3 has made a major breakthrough in multilingual programming capability, and its performance in the aider multilingual programming benchmark surpassed competitors such as Claude3.5 Sonnet V2.
Technical principles of DeepSeek V3
- Architecture design: DeepSeek V3 adopts a Mixture-of-Experts (MoE) architecture. The architecture contains as many as 256 experts, and each expert is an independent neural network that can handle specific tasks or data types. In the MoE architecture, not all experts participate in every computation; instead, a routing mechanism (such as sigmoid routing) dynamically selects a subset of experts for computation. In DeepSeek V3, each computation selects the top 8 most relevant experts (topk=8) to participate.
- Working mechanism: It is divided into the following key stages:
- Plan: Based on the user query, plan the form of the final result, and define the entity types to be extracted and the related columns.
- Search: Combine keyword search and neural search, and with the support of Exa, precisely locate content.
- Extract: Use a large language model (LLM) to efficiently identify and extract specific information from the content.
- Enrich: Further fill in the extracted data to ensure that each entry is as detailed as possible.
- Multimodal capability: DeepSeek V3 uses OCRvl2 technology, which can better preserve the text, formatting layout, and formulas in images, with results surpassing traditional OCR.
- Streaming rendering optimization: The web front end uses streaming output, but because each rendering requires re-parsing Markdown, the current 60tps rendering speed may cause some delay.
Project address of DeepSeek V3
- HuggingFace model library:
- Paper link:https://github.com/deepseek-ai/DeepSeek-V3/blob/main/DeepSeek_V3.pdf
- Product experience:DeepSeek
Performance and efficiency improvements of DeepSeek V3
- Parameter scale: DeepSeek V3 adopts an MoE architecture with as many as 685 billion parameters. This large-scale parameterization enables the model to capture more complex patterns and relationships.
- Computing resource management: Through the MoE architecture, DeepSeek V3 can dynamically select the most suitable experts for computation, thereby reducing unnecessary computation and memory consumption.
- Data parallelism and model parallelism: During training, DeepSeek V3 uses parallel strategies such as data parallelism, tensor parallelism, sequence parallelism, and 1F1B pipeline parallelism. These strategies improve hardware utilization and accelerate model training.
- Optimized learning rate scheduler: DeepSeek V3 uses a multi-stage learning rate scheduler, which helps the model maintain the optimal learning rate at different training stages.
- Scaling Laws research: The DeepSeek V3 development team conducted in-depth research on Scaling Laws to find the optimal allocation ratio of model/data scale and to predict the training results of large-scale models.
- Safety evaluation: DeepSeek V3 conducts strict data safety screening throughout the entire training process to ensure that the trained model conforms to human values.
Multiple evaluation results of DeepSeek V3
- In the authoritative test set HumanEval: DeepSeek-V3-0324 surpassed Claude 3.7's score of 322.3 with a score of 328.3.
- In the LiveBench test: DeepSeek V3's score is very high, indicating that it can quickly respond to user queries and provide feedback.
- Global average score: 60.4 points
- Reasoning ability: 50 points
- Programming skills: 63.4 points
- Mathematical analysis: 60 points
- Data analysis: 57.7 points
- Language understanding: 50.2 points
- Instant feedback (IF): 80.9 points
- Educational benchmarks:
- In the MMLU (multi-subject multiple-choice) benchmark, DeepSeek-V3 achieved an accuracy of 88.5%, surpassing all other open-source models and comparable to leading closed-source models such as GPT-4o and Claude-Sonnet-3.5.
- In MMLU-Pro (a more rigorous multi-subject multiple-choice benchmark), DeepSeek-V3 achieved an accuracy of 75.9%, also leading other open-source models and performing comparably to top closed-source models.
- Factuality benchmarks:
- In SimpleQA and Chinese SimpleQA, DeepSeek-V3 surpassed GPT-4o and Claude-Sonnet-3.5 in Chinese factual knowledge, demonstrating its advantage in Chinese factual knowledge.
- Code, mathematics, and reasoning benchmarks:
- Among all non-long-CoT open-source and closed-source models, DeepSeek-V3 performs best on mathematics-related benchmarks, even surpassing o1-preview on some benchmarks such as MATH-500, demonstrating its strong mathematical reasoning ability.
- In programming-related tasks, DeepSeek-V3 became the best-performing model in LiveCodeBench (Live Code Benchmark), consolidating its leading position in this field.
- Open-ended evaluation:
- In open-ended dialogue evaluation, DeepSeek-V3 achieved excellent results on the AlpacaEval 2.0 and Arena-Hard benchmarks, demonstrating its strong ability to handle complex prompts and tasks.
- Evaluation as a generative reward model:
- In the RewardBench evaluation, DeepSeek-V3 showed performance comparable to GPT-4o and Claude-3.5, further proving its judgment ability as a reward model.
DeepSeek V3 API service pricing
- Pricing:Per million input tokens 0.5 yuan (cache hit) / 2 yuan (cache miss), per million output tokens 8 yuan.
- Promotional discount trial period: From now until 2025 year 2 month 8 day, a 45-day discounted price trial period is set.
- Promotional price: per million input tokens 0.1 yuan (cache hit) / 1 yuan (cache miss), per million output tokens 2 yuan.
- Benefits: Existing users and new users who register during this period can enjoy the discounted price.
DeepSeek V3 application scenarios
- Education and training: DeepSeek V3 can serve as a personalized learning assistant, providing immediate answers and tutoring based on students' learning progress and situations.
- Content creation: Writers and content creators can use DeepSeek V3 to get inspiration, generate content outlines, or polish text.
- Scientific Research Exploration: Researchers can use DeepSeek V3 for complex scientific research tasks such as data analysis and pattern recognition.
- Product Development: Through the DeepSeek API, developers can seamlessly integrate DeepSeek V3's AI capabilities into various applications and products, enhancing their level of intelligence.
- Information Retrieval: DeepSeek V3 aims to revolutionize the existing concept of search engines, transforming them from a mere "answer engine" into a more powerful "retrieval engine".