
What is DeepSeek V4.1 Flash
DeepSeek V4.1 Flash is the smallest model in DeepSeek's new model architecture series, a 552B MoE using an asymmetric Causal-Encoder-Decoder, with about 8B input activation and 16B output, and native multimodal visual understanding capabilities. At the same time, the model significantly compresses the KV Cache to reduce long-context and Agent costs, and the API is called throughdeepseek-flash, with price reductions and peak/off-peak billing, Tencent (WorkBuddy、CodeBuddy) and OpenCode as official partners, and is now fully integrated with DeepSeek V4.1 Flash and has been open-sourced on Hugging Face.
Main features of DeepSeek V4.1 Flash
-
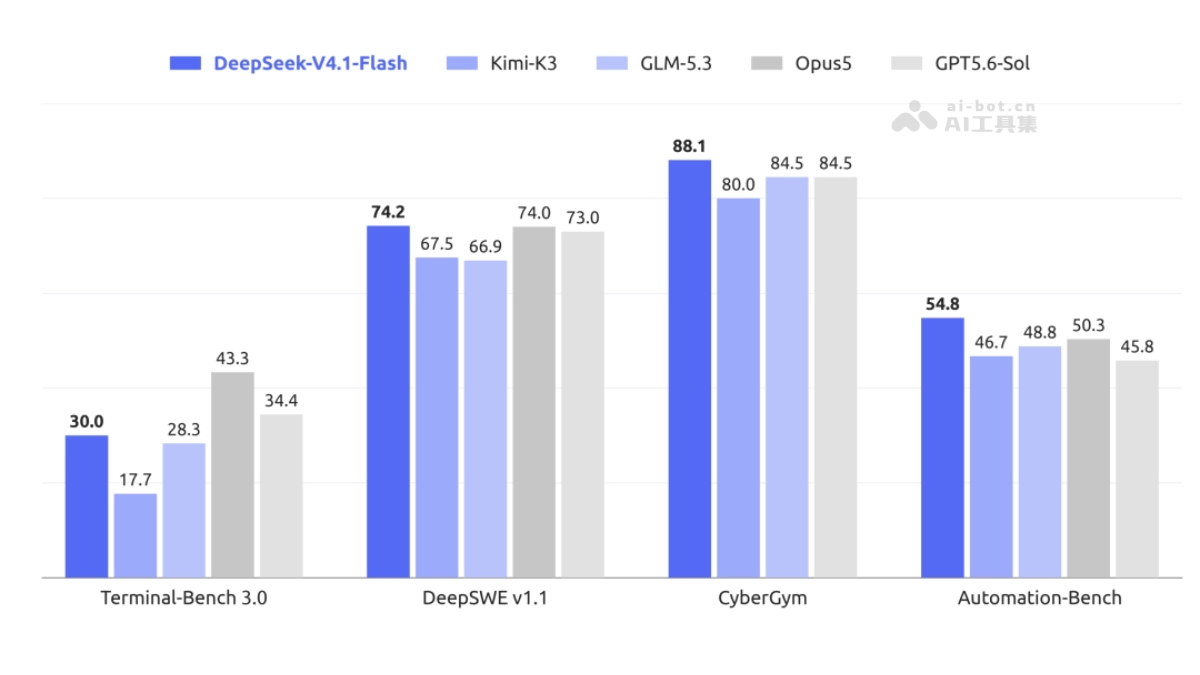
Stronger intelligence: The 552B MoE adopts a new Causal-Encoder-Decoder structure and, after post-training with larger-scale reinforcement learning, surpasses V4 Pro on benchmarks.
-
Faster inference: Only 8B input activation and 16B output activation, balancing speed and capability with higher throughput.
-
Native multimodality: It has visual understanding capabilities and can process image-text input.
-
Significant cache savings: KV Cache is greatly reduced, HBM demand drops to 1/4 and SSD to 1/8, lowering Agent costs.
Technical principles of DeepSeek V4.1 Flash
-
Asymmetric Causal-Encoder-Decoder: The core idea is to use different computational intensities for "reading and understanding" and "generating output," with about 8B activation on the input side and about 16B activation on the output side, reducing inference costs while ensuring generation quality.
-
MoE sparse activation: The total parameter count is 552B, but only a small portion of expert parameters is activated each time, trading higher parameter capacity for stronger expressiveness while avoiding the high latency and high memory usage caused by full activation.
-
Training paradigm upgrade: It adopts a new pretraining approach and performs larger-scale reinforcement learning post-training, enabling it to surpass flagship models including V4 Pro on Agentic benchmarks.
-
KV Cache compression: By reducing context cache usage, HBM demand is compressed to 1/4 of the previous generation and SSD to 1/8; compared with the first generation, it is cumulatively reduced by 437 times, directly lowering the cache hit cost for long context and Agents.
-
Designed for scale: The structural goals balance a higher capability ceiling, faster inference, and greater throughput, and it can be extended to larger-parameter models, so it can still cover multimodal and complex Agent scenarios while reducing API prices.
How to use DeepSeek V4.1 Flash
-
Prepare a key: Obtain a DeepSeek API Key.
-
Access address: Use the OpenAI-compatible method, set
base_url="https://api.deepseek.com"。 -
Specify the model: When calling, set
modeltodeepseek-flash。 -
Multimodal input: For image-text understanding, pass the image URL or base64 in the multimodal message format.
-
Legacy compatibility:
deepseek-v4-flash、deepseek-v4-flash-vision-expwill temporarily be routed to V4.1 Flash. -
Pro switch:
deepseek-v4-prowill be routed to V4.1 Flash and billed accordingly after 2026-09-14 12:00. -
Open-source deployment: For private deployment, Hugging Face weights can be used; large-scale deployment requires about 2k GPU cards, a storage cluster, and contacting the official team.
Core Advantages of DeepSeek V4.1 Flash
-
Extreme Speed: Community tests generally show output of 300~400 tokens/s, with peaks reaching 507 tokens/s, delivering an interactive experience close to "instant replies".
-
Native Multimodality: Visual capabilities are directly integrated into the base architecture, with no need to rely on a separate vision version like V4 Flash.
-
Same Price, Implicit Price Cut: Capabilities are upgraded while billing remains at the V4 Flash level, with cached hit input during idle periods as low as 0.05 yuan per million tokens.
-
Refreshed Architecture: It adopts an entirely new model structure and is a precursor to DeepSeek's new round of technical roadmap, leaving more room for future upgrades.
-
Zero-Cost Integration: The base_url remains unchanged and only the model name needs to be changed to call it, allowing existing users to switch seamlessly.
Project Address of DeepSeek V4.1 Flash
- HuggingFace Model Repository:https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash
- Technical Paper:https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/main/DeepSeek_V41_Tech_Report.pdf
Comparison of DeepSeek V4.1 Flash with Similar Competing Products
| Dimension | DeepSeek V4.1 Flash | Zhipu GLM-5.3 Flash |
|---|---|---|
| Multimodality | Native support (architecture-level fusion) | Supports images, videos, files, and text |
| Output Price | 4.5 yuan/million tokens (idle) | About $0.50/million tokens ($0.25 during promotional period) |
| Input Price | 0.05~1.5 yuan/million tokens (idle) | About $0.15/million tokens ($0.075 during promotional period) |
| Concurrency Limit | 20 concurrent requests per account (rate-limited during internal testing) | Normal commercial quota |
| Availability | Expires on September 10, only a two-day window | Officially released and available long-term |
| Open-Source Status | Not open-sourced | The GLM series has consistently been open-sourced |
Application Scenarios of DeepSeek V4.1 Flash
-
Real-Time Conversational Assistant: Streaming output of 300+ t/s makes chat and customer service scenarios feel almost wait-free.
-
AI Programming Assistance: Code completion and snippet generation are extremely sensitive to latency, and high-speed output can be seamlessly embedded into IDEs.
-
Visual Understanding Applications: Native multimodality is suitable for mixed image-text tasks such as screenshot Q&A, document image parsing, and UI review.
-
Lightweight Agent Execution Layer: Agents require high-frequency serial calls to models, and low cost + high throughput make it suitable for execution and sorting stages.
-
Batch Content Production: For pipeline tasks such as copy rewriting, summarization, and translation, low unit price + cache hits minimize costs.