
What is Qwen3.7-Max
Qwen3.7-Max is a new generation flagship large model for the agent era launched by the Alibaba Tongyi Qianwen team, positioned as an all-purpose agent foundation. The model possesses four core capabilities: frontier coding, office automation, long-horizon autonomous execution, and cross-framework generalization. It has achieved leading results on dozens of coding, agent, and reasoning benchmarks such as SWE-Pro, MCP-Atlas, and GPQA Diamond, and can seamlessly integrate into Claude Code、OpenClaw, Qwen Code, and other mainstream agent frameworks.
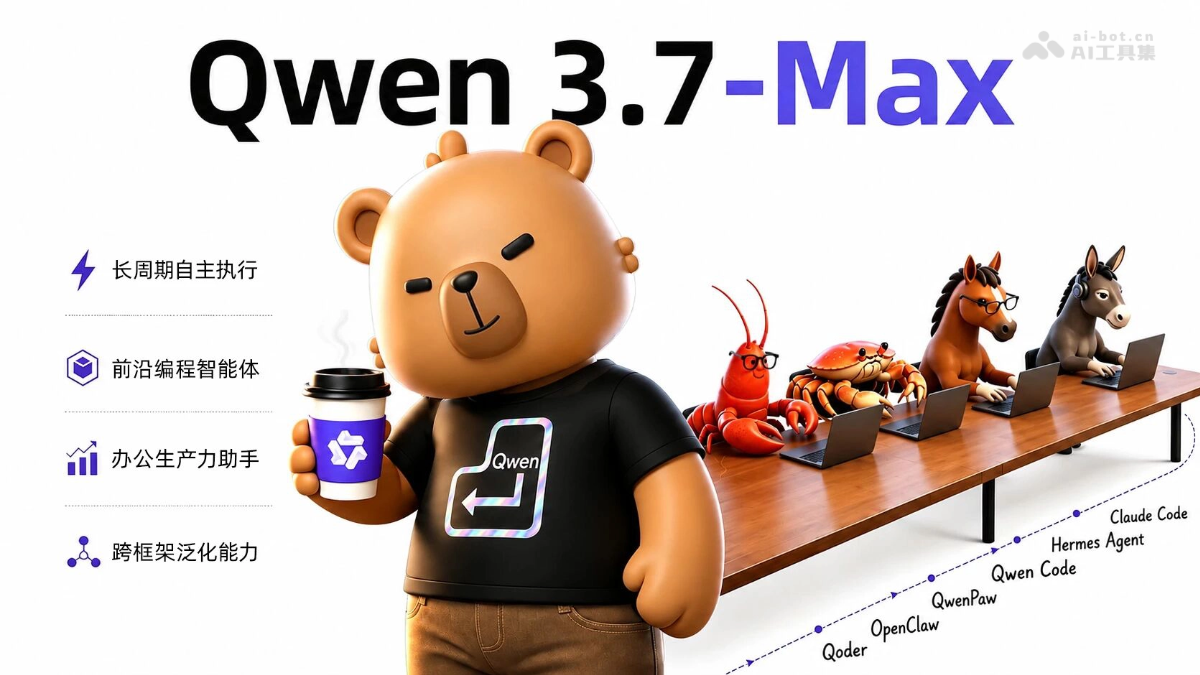
Qwen3.7-Max's Main Features
- Frontier Coding Agent: Supports full-chain code writing and debugging from front-end prototyping to complex multi-file software engineering, with leading performance on coding benchmarks such as SWE-Pro and SWE-Multilingual.
- Office Productivity Assistant: Achieves workflow automation through MCP integration and multi-agent collaboration, scoring 87.0 on the SpreadSheetBench-v1 office automation benchmark, and can undertake complex data analysis and document generation tasks.
- Long-Horizon Autonomous Execution: Possesses sustained and stable ultra-long task execution capability, having maintained coherent reasoning in a fully autonomous kernel optimization experiment lasting up to 35 hours with over 1,000 tool calls.
- Cross-Framework Generalization: Natively adapts to mainstream agent frameworks such as Claude Code, OpenClaw, and Qwen Code, delivering stable performance without the need for framework-specific fine-tuning.
Qwen3.7-Max's Technical Principles
- Environment Scaling Training: Based on the Qwen3.5 environment scaling method, greatly expands the quality and diversity of agent training environments, enabling model capabilities to generalize from diverse environments.
- Decoupled Rollout Infrastructure: Decouples training instances into three orthogonal components: task, runtime framework, and verifier, supporting reinforcement learning training across frameworks and verifiers, forcing the model to learn generalized problem-solving strategies.
- Compositional Scaling: The same task can be freely recombined with different types and versions of frameworks and verifiers at extremely low marginal cost, achieving compositional scalable expansion of training environments.
- Long-Horizon Reinforcement Learning Optimization: Through continuous feedback iteration in long-horizon autonomous execution, the model can still discover substantive improvements after more than 30 hours, validating long-horizon optimization and self-evolution capabilities.
How to Use Qwen3.7-Max
Qwen3.7-Max is planned to provide services throughAlibaba Cloud Bailian.
Qwen3.7-Max's Core Advantages
-
Comprehensive Leadership on Agent Benchmarks: Surpasses or closely follows Claude Opus-4.6 Max on general agent benchmarks such as MCP-Mark, MCP-Atlas, ClawEval, and QwenClawBench.
-
Top-Tier Coding Capability: SWE-Pro 60.6, SWE-Multilingual 78.3, Terminal Bench 2.0 69.7, comprehensively leading comparable models.
-
Deep Reasoning and Knowledge: GPQA Diamond 92.4, HMMT 2026 Feb 97.1, HLE 41.4, placing it in the first tier for high-difficulty STEM reasoning.
-
First-Class Multilingual Capability: WMT24++ 85.8, MAXIFE 89.2, MMLU-Pro 89.6, with top-tier translation and cross-lingual understanding quality.
-
Real Productivity Closed Loop: Can compress complex projects that would require a professional team one to two weeks into end-to-end delivery within hours.
-
Hardware-Agnostic Generalization: On the T-Head Zhenwu M890 hardware platform, which was unseen during training, it can complete deep kernel optimization through autonomous exploration.
Comparison of Qwen3.7-Max with Similar Competitors
| Comparison Dimension | Qwen3.7-Max | Claude Opus-4.6 Max |
|---|---|---|
| Coding Agent | SWE-Pro 60.6 / Terminal Bench 69.7, leading | SWE-Pro 59.0 / SWE-Verified 80.8, slightly leading |
| General Agent | MCP-Atlas 76.4 / ClawEval 65.2, leading | MCP-Atlas 75.8 / ClawEval 70.4, leading |
| Reasoning Ability | GPQA Diamond 92.4 / HLE 41.4, leading | GPQA Diamond 91.3 / HLE 40.0 |
| Office Automation | SpreadSheetBench 87.0 | SpreadSheetBench 89.3, slightly leading |
| Multilingual | WMT24++ 85.8 / MAXIFE 89.2, leading | WMT24++ 82.7 |
| Long-Horizon Execution | 35 hours / 1000+ tool calls of autonomous optimization, still continuously improving after 30 hours | Stable over long context, but there are few public cases of long-horizon autonomous optimization |
| Cross-Framework Generalization | Native adaptation to multiple frameworks such as Claude Code / OpenClaw / Qwen Code | Mainly optimized for Claude Code |
| Service Availability | Alibaba Cloud Model Studio API (coming soon) | Anthropic API / Claude app |
Application Scenarios of Qwen3.7-Max
- Complex Software Development: As an AI software engineer, independently complete full-cycle development tasks including requirements analysis, architecture design, multi-file coding, debugging, and performance optimization.
- Enterprise Workflow Automation: Through MCP, connect enterprise toolchains to automatically execute high-intensity office tasks such as data analysis, report generation, and cross-system information integration.
- Low-Level System Optimization: Autonomously perform GPU kernel writing, compilation, performance analysis, and iterative optimization on unfamiliar hardware platforms to achieve order-of-magnitude acceleration.
- Scientific Research and Mathematical Reasoning: Undertake highly complex mathematical proofs, scientific computing, and literature integration tasks, assisting researchers in handling highly difficult reasoning work.
- Multilingual Content Production: Relying on top-tier multilingual capabilities, complete high-precision translation, cross-language technical documentation writing, and globalized content adaptation.