
What is Grok 4.7
Grok 4.7 is SpaceXAI's latest flagship large model, positioned as the strongestcodingand knowledge work model. The model switches to a larger base model, strengthening long-horizon tasks, self-verification, and long-context management capabilities, greatly surpassing the previous generation on benchmarks such as CursorBench, Terminal-Bench, law, and electrical engineering Grok 4.6, while pricing remains unchanged at $2 per million tokens for input and $6 for output, offering outstanding value for money.
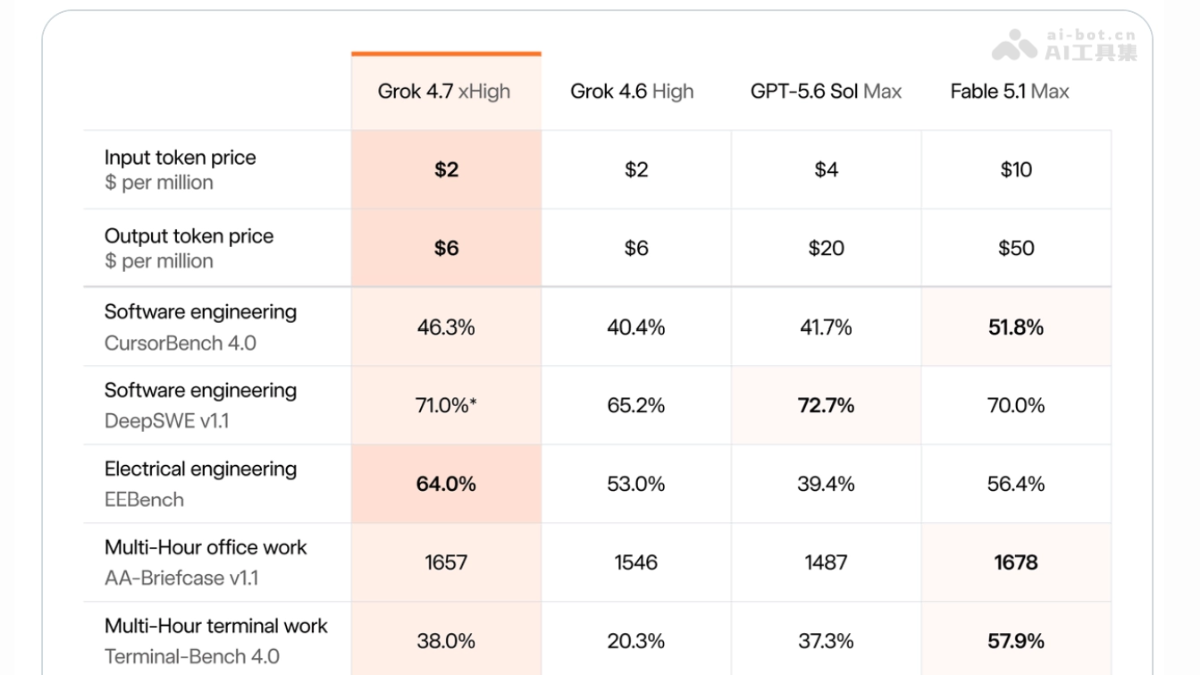
Grok 4.7's main features
-
Long-horizon coding: Excels at complex software tasks lasting several hours, able to read repositories, break down requirements, modify multiple files, and repeatedly correct errors.
-
Self-verification: While executing tasks, it can check its own work and manage long contexts, reducing mid-task drift.
-
Knowledge work: Covers professional scenarios such as documents, presentations, legal analysis, medical reasoning, and engineering tasks.
-
Four reasoning levels: Supports four reasoning effort levels—Low / Medium / High / Extra High—for flexible selection based on task complexity.
-
Fast mode: A fast variant with double the output speed; the price is doubled but still far below competitors.
-
Safety guardrails: Refusal and anti-jailbreak capabilities are the strongest of any generation, with outstanding performance in blocking high-risk biosecurity and cybersecurity issues.
Grok 4.7's technical principles
- Larger base model: Grok 4.7 switches to a larger foundation model than 4.6, providing stronger representation and generation capabilities for long tasks and complex reasoning.
- Harder and longer reinforcement learning: During training, the reinforcement learning cycle was extended, task combinations were made harder, and more samples require several hours to complete, accustoming the model to long-horizon execution chains.
- Self-verification mechanism: Through training, the model actively checks its own work, manages long contexts, and discovers and corrects errors over lengthy tasks.
- Native Harness understanding: The model is trained to natively understand the Grok Bot runtime framework, improving conversational tasks and ongoing collaboration with tools and execution environments.
- New-generation safety protection: A brand-new safety system is enabled, reaching the strongest levels ever officially tested on refusal, jailbreak resistance, and biosecurity benchmarks.
How to use Grok 4.7
-
Grok Build update: Local terminal users run
grok updateto upgrade Grok Build to the latest version and use it. -
Choose reasoning level: In Grok Build, switch among the four reasoning effort levels—Low / Medium / High / Extra High—according to task complexity.
-
Cursor integration: After updating Cursor , select Grok 4.7 as the coding model in the model settings.
-
API calls: Integrate through the Grok API (or third-party frameworks, model routing, cloud platforms).
-
Fast mode: When speed is a priority, select the fast variant in the API for double the output speed and double the price.
Grok 4.7's core advantages
-
Long-Horizon Task Capability: Strengthens the execution and self-correction of complex tasks lasting several hours, greatly reducing mid-task drift.
-
Coding Performance Leap: CursorBench reaches 46.3% (+5.9pt), Terminal-Bench doubles to 38.0%, firmly in the top tier.
-
Vertical Domain Leadership: Legal benchmark 19.6%, electrical engineering 64.0%, greatly surpassing GPT-5.6 Sol and Fable 5.1.
-
Extreme Cost-Effectiveness: Input $2 / output $6 per million tokens, unchanged from the previous generation, priced at only 1/5 to 1/8 of Fable 5.1.
-
Doubled-Speed Option: The fast variant doubles output speed and, even after the price increase, remains far below competitors.
-
Free Generation Upgrade: Users do not need to pay extra over the standard version for stronger performance.
-
Strongest Safety Generation: Refusal and jailbreak resistance set official records, topping LatchBio at 62.4%.
-
Full-Scenario Coverage: Extends from coding to complete knowledge workflows including documents, presentations, legal, medical, and engineering.
Grok 4.7 Project Official Website
- Project Address:https://x.ai/news/grok-4-7
Comparison of Grok 4.7 with Similar Competitors
| Comparison Dimension | Grok 4.7 | Claude Fable 5.1 |
|---|---|---|
| Positioning | Strongest coding and knowledge work model | Frontier flagship general model |
| CursorBench 4.0 | 46.3% | 🥇 51.8% (leading) |
| Terminal-Bench 4.0 | 38.0% | 🥇 57.9% (far ahead) |
| DeepSWE v1.1 | 🥇 71.0% (overtaking) | 70.0% |
| Harvey Legal Benchmark | 🥇 19.6% (nearly 3x lead) | 6.7% |
| EEBench (Electrical Engineering) | 🥇 64.0% (clearly leading) | 56.4% |
| AA Briefcase Office Tasks | 1657 points (close) | 🥇 1678 points |
| HealthBench Professional | 56.7% (weaker) | 🥇 62.1% |
Application Scenarios of Grok 4.7
-
Intelligent Programming Development: Repository-level code understanding, multi-file modifications, test execution, and automatic error correction, suitable for Agent coding scenarios such as Cursor.
-
Legal Professional Work: Contract analysis, legal research, and document drafting, nearly three times ahead of competitors on the Harvey benchmark.
-
Electrical Engineering Design: Circuit analysis, engineering document processing, and calculations, comprehensively surpassing rivals on EEBench.
-
Long-Duration Office Tasks: Multi-step workflows for roles such as lawyers and financial analysts, including creating documents, presentations, and data reports.
-
Multi-Turn Knowledge Dialogue: Natively understands the Grok Bot harness, suitable for customer service assistants, research assistants, and other dialogue scenarios requiring continuous collaboration.