
With the continuous advancement of artificial intelligence technology, in an era of rapid development of digital and multimedia content, we have witnessed revolutionary progress in AI technology in the fields of image and video processing. Among these, AI lip-sync technology is gradually becoming a new favorite in video production and content creation. It can seamlessly map speech in any language onto a person's facial expressions and lip movements. This article introduces 12 free AI lip-sync tools and software that support images and videos. Lip-sync technology can naturally synchronize audio with the lip movements of people in videos, providing a completely new form of expression in entertainment, education, or social media interaction.
1. Jimeng AI
Jimeng AIis an AI creation tool launched by ByteDance's Jianying team. It can generate high-quality images and videos through natural language or image input, and supports video generation, AI lip-sync, camera control, speed control, and many other functions, providing users with a one-stop solution for story creation and visual content production.
🚀 Feature Highlights
- High Realism: Jimeng AI's lip-sync function can accurately capture a person's mouth movements. In the generated video, the person's lip movements are highly synchronized with the dubbing, and the viewing experience is natural.
- Multilingual Support: Supports Chinese and English dubbing, with particularly optimized understanding of Chinese, meeting the needs of creators in different languages.
- Simple Operation: Users only need to upload a person's image or video and input or upload the dubbing content to automatically generate a lip-sync video.
- Free to Use: Jimeng AI's basic functions are open to all users for free. You can enjoy the convenience brought by AI lip-sync without paying.
- Multiple Voice Options: Jimeng AI provides multiple voices for users to choose from, allowing them to select a suitable voice according to the video style and character characteristics.
- Supports Text Reading and Local Dubbing: Users can choose text reading or upload local dubbing, making the digital human more realistic and natural.
- Emotion and Expression Matching: Jimeng AI's lip-sync function can match lip movements and can also match the corresponding tone, emotion, and expressions according to the context, providing lip-sync services with the best Chinese effect.
- Subtle Movement Capture: It can accurately "direct" every subtle movement of a virtual character, such as non-speech actions like sighs, emotion-driven eyebrow and eye movements, and natural head movements.
- Supported Generation Duration: The AI lip-sync function supports generating lip-sync videos up to 9 seconds long, meeting video needs of different lengths.
✨ Applicable Scenarios
- Corporate Marketing: Marketers can use Jimeng AI to create product promotion videos. Through the AI lip-sync function, the videos can be made more attractive and marketing results can be improved.
- Education and Training: Educators can create teaching videos and training materials, using the AI lip-sync function to make teaching content more vivid and interesting and enhance the learning experience.
- Entertainment and Media: The lip-sync function can be used in film, television, and online content production to match lip movements for character dubbing, improving production efficiency and video quality.
2.Seko
Seko is launched by SenseTimeAI videoCreation Agent: After users upload a photo or video, they only need to enter any text or upload audio, and the people in the image can automatically match their lip movements, expressions, and tone, achieving a highly realistic talking effect. Its core advantages lie in millisecond-level precise lip sync, multilingual support, and emotionally rich facial expressions.
🚀Feature Highlights
-
Millisecond-Level Precise Lip Sync: AI analyzes audio waveforms in real time, driving the character's lip movements to closely match pronunciation with extremely low latency.
-
Natural Multilingual Adaptation: Supports input in Chinese, English, Japanese, and many other languages, automatically adjusting lip opening amplitude and pronunciation habits.
-
Emotional Facial Expressions: It not only syncs lips, but also intelligently matches rich expressions such as smiling, surprise, and seriousness according to tone.
-
Dual Photo/Video Drive: It can make static photos "speak" and can also replace or optimize the lip movements of people in existing videos.
-
One-Click Generation with Low Barriers: No professional animation skills are required; upload materials and enter text or audio to quickly output a finished product.
✨Use Cases
-
Virtual Streamers and Livestream E-commerce: Make static images or pre-recorded videos speak in real time to explain products, reducing the cost of appearing on camera in person.
-
Digital Human Customer Service and Narration: Generate standardized voice-over videos for corporate training, government service guides, and other scenarios, improving the efficiency of information delivery.
-
Short Videos and Social Media Content: Quickly create fun "talking photo" content, suitable for distribution on platforms such as Douyin and Xiaohongshu.
-
Multilingual Content Localization: Quickly adapt the same video material to lip movements in different languages, supporting overseas marketing and cross-border communication.
-
Education and Paid Knowledge: Add voiceovers to character images in courseware and micro-lessons, enhancing teaching interactivity and student attention.
3.LibTV
LibTV is a professional AI video creation platform launched by LiblibAI, pioneering a dual-entry system for humans and Agents. The platform integrates top models such as Lib Nano Pro and Kling 3.0. Its core highlight is intelligent lip-sync capability: after uploading audio or entering text, AI automatically drives the character's face to precisely match lip movements and expressions, achieving audio-visual synchronization. The platform also features character three-view images, 360° angle presentation, and multi-camera 9-grid functions, ensuring a high degree of consistency in character appearance and lip movements across multiple shots, completing one-click closed-loop creation from script to final film.
🚀Feature Highlights
-
Intelligent Lip Sync: AI automatically drives the character's face, precisely matching audio lip movements and expressions to achieve audio-visual synchronization.
-
Character Three-View Images: 360° angle presentation ensures highly consistent character appearance across multiple shots.
-
Infinite Canvas Workflow: Freely drag text, images, videos, audio, and script nodes to manage projects spatially.
-
AI Production Assistant: Script parsing, script optimization, one-click shot breakdown, and plot deduction multi-grid preview.
-
Agent Automation: Generate a 5-minute short drama, video replication, music MV, or official website product film with one sentence.
-
20+ Professional Controls: Lighting and camera movement, multi-camera 9-grid, focused close-ups, and precise video editing.
-
Full-Process Closed Loop: One-stop completion from script → storyboard → final film, with no need to switch between multiple tools.
✨Use Cases
-
AI Short Dramas/Comic Dramas: Generate a complete short drama of up to 5 minutes from a single sentence, automatically completing the script, characters, storyboard, lip-syncing, sound effects, and editing.
-
AI TVC Ads: Brands can quickly generate product showcase videos, with support for generating directly from a website link or replicating the same style from a reference video.
-
Music MV Creation: Upload a music file, and AI analyzes the rhythm and emotion, automatically generating a matching visual narrative with precise lip-syncing.
-
Character Consistency Videos: Through features such as character three-view sheets and 360° presentation, the character's appearance and lip movements remain highly consistent across multiple shots.
-
AI Film Production: Professional creators use an infinite canvas to coordinate the script, storyboard, shots, and editing, completing the full production process for feature-length or short films.
4.Hedra
Hedrais an AI-driven digital creation platform that can quickly transform text and images into dynamic video characters that speak and sing. Users do not need professional skills and can create professional-grade videos within minutes. Hedra supports one-click storytelling, multiple voice options, and character customization, making video production simple and fast.
🚀Feature Highlights
- Add Voice Content: Users can upload any voice file or enter text, and the system combines the voice with a person's photo to make the person speak or sing.
- Generate Vivid Videos: Through the Character-1 tool, users can transform static photos and audio files into vivid animated videos, generating expressive human characters.
- Expression Synchronization: Hedra's AI technology ensures that the expressions and lip shapes of the person in the video are precisely synchronized with the input voice content, including basic pronunciation synchronization as well as more subtle expression changes such as smiling, frowning, or surprise.
- Diverse Character Support: Hedra is not limited to generating videos with a single character and supports diverse character creation (humans, anime, animals, stone statues, etc.), and each character can have unique expressions, movements, and voice.
✨Use Cases
- Education: Hedra AI can create engaging educational content, using animated characters to explain complex concepts, making learning more vivid and interesting.
- Marketing: Hedra AI can produce personalized promotional videos showcasing approachable characters.
- Training and Development: Hedra AI can develop interactive training videos with AI-driven presenters, improving the appeal and efficiency of training.
- Social Media Content Creation: Users can use Hedra AI to generate interesting short videos or music videos for social media platforms.
5. Kling AI
Kling AIis a new-generation AI creative productivity platform launched by Kuaishou, based on the Kling large model and Kolors large model, providing video and image generation and editing capabilities. Kling AI's "lip-sync" feature is a newly launched innovative feature that supports users in uploading audio content and precisely synchronizing these audio tracks with the mouth shapes of people in videos. It includes real people, 2D, and 3D characters. As long as there is a face in the video, a high degree of integration between audio and video images can be achieved.
🚀Feature Highlights
- High Synchronization: It can achieve precise synchronization between audio content and the mouth shapes of people in videos. Whether they are real people or 2D or 3D characters, a high degree of integration between audio and video images can be achieved.
- Technical Support: Leveraging deep learning technology, Generative Adversarial Networks (GAN), and Natural Language Processing (NLP), it ensures a high degree of coordination between voice and image.
- Broad Support: Kling AI's lip-sync feature mainly supports real, 3D, and 2D character roles.
- User-Friendly: After users upload audio files, the operation is simple, making it suitable for short video producers, content creators, and applications in the education industry.
✨Use Cases
- Social Media and Short Video Platforms: Users can use the "lip-sync" feature to create vivid virtual avatar narration videos, courseware videos, and various fun video content on social media.
- Content Creation: It can assist animation creation, making the lip movements of animated characters precisely match the dubbing, improving the realism and watchability of video content.
- Education: The lip-sync feature can be used to create educational videos, such as language learning tutorials, helping students better learn and imitate pronunciation.
- Virtual Character Performance: It enables virtual characters to perform more naturally, suitable for scenarios such as virtual streamers and virtual idols, enhancing interactivity and audience immersion.
6.Hallo
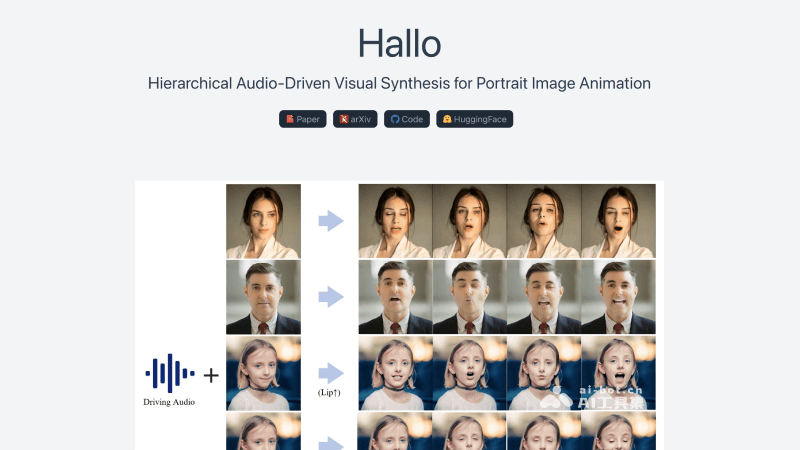
HalloIt is an AI technology jointly launched by Fudan University, Baidu, ETH Zurich, and Nanjing University, focused on generating realistic dynamic portrait image videos through voice audio input. Based on a hierarchical audio-driven visual synthesis module and an end-to-end diffusion model, combined with a UNet denoiser, temporal alignment technology, and a reference network, it achieves high-precision audio-visual synchronization and personalized animation customization.
🚀Feature Highlights
- Audio-Synchronized Animation: Based on advanced audio analysis technology, Hallo combines input voice audio with portrait images to generate dynamic facial animations. Through a precise lip movement synchronization algorithm, it ensures that the lip movements in the video animation are synchronized with the sound in the audio, creating a realistic talking effect.
- Hierarchical Audio-Driven Visual Synthesis: Hallo adopts a hierarchical approach to process audio and visual information, separately handling lip movements, facial expressions, and head poses, and fusing these elements together through adaptive weights, improving the synchronization accuracy between audio and visual output.
- End-to-End Diffusion Model: Hallo uses a diffusion-based generative model, gradually adding noise during the training phase and removing noise during the reverse process to reconstruct clear images, which helps generate clear animation frames synchronized with audio.
- Cross-Attention Mechanism: Through the cross-attention mechanism, Hallo can establish connections between audio features and visual features, allowing the model to focus on the facial regions most relevant to the current audio input, especially the lip region, achieving more precise lip synchronization.
- Face and Audio Encoders: Hallo uses a pretrained face encoder to extract the identity features of the portrait, and also uses an audio feature encoder (such as wav2vec) to convert audio signals into information that can drive animation motion, helping achieve precise lip synchronization.
- Adaptive Weight Adjustment: Hallo supports adjusting the weights of different visual components (such as lips, expressions, and poses) to control the diversity and details of the animation, including the precision of lip movements.
✨Use Cases
- Virtual Streamer: In fields such as news broadcasting, weather forecasting, and online education, Hallo can generate realistic facial animations and lip sync for virtual anchors, improving the appeal and interactivity of programs.
- Video conferencing: In remote work and online meetings, Hallo can add lip sync functionality to participants' avatars, enhancing the realism and immersion of communication.
- Games and entertainment: In game characters, animated films, and virtual reality experiences, Hallo can provide natural lip sync for characters, improving the experience for players and viewers.
- Social media: On social media platforms, Hallo allows users to create dynamic avatars or virtual personas with lip sync, increasing interactivity and entertainment value.
- Language learning: In language learning applications, Hallo can generate lip-synced videos of teachers or virtual assistants, helping learners better imitate pronunciation and intonation.
7.Vozo
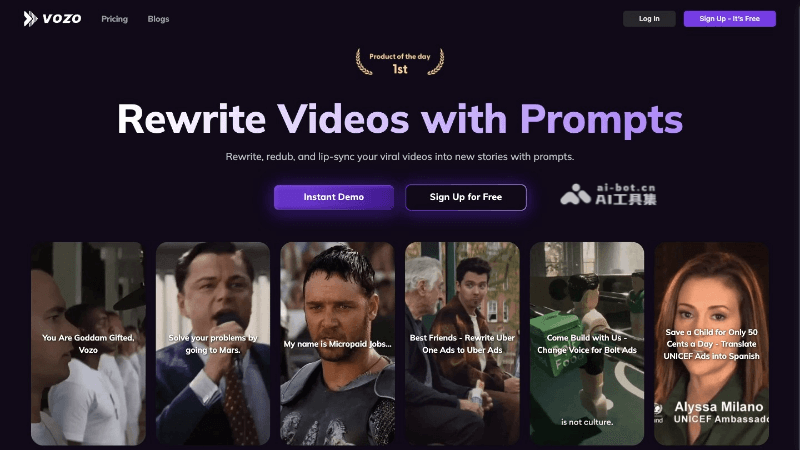
Vozois a versatile AI video editing tool that uses artificial intelligence technology to rewrite, redub, and translate video content. Vozo supports multiple languages, provides lip sync and automatic video repurposing features, and helps creators efficiently produce and optimize video content.
🚀Feature highlights
- Multi-speaker lip sync: Vozo AI can seamlessly synchronize lip movements for videos containing multiple speakers and can accurately capture the facial features of each character in the video.
- Natural and smooth lip sync: Based on advanced technology, Vozo can achieve natural and smooth lip sync for multiple characters in a video. It ensures that dialogues in the video look real and natural, improving the viewing experience.
- Accurate lip movement matching: Vozo's lip sync technology ensures that new audio perfectly matches the speaker's lip movements, presenting a natural and professional appearance.
✨Use cases
- Secondary creation of video content: Vozo supports users in rewriting video scripts through simple prompts and automatically generating dubbing similar to the original voice, while preserving the original video speaker's timbre, tone and emotion, and background sound. The lip movements are also basically synchronized, and the overall presentation is very natural and smooth.
- Advertising and marketing: Advertising agencies can use Vozo to quickly create multiple versions of ads targeting different audiences, improving creative efficiency. By modifying scripts and dubbing ads, create unlimited variations for different audiences.
- Multilingual video production: Vozo supports translating videos into more than 30 languages and dialects, with translation accuracy as high as 98.9%, helping marketers and e-commerce businesses translate product videos into multiple languages. The lip sync technology is applicable to multiple languages, making translated videos more natural and realistic.
- Educational video production: Educators can modify educational videos by editing text and cloning dubbing to match any language or tone.
8.AniTalker
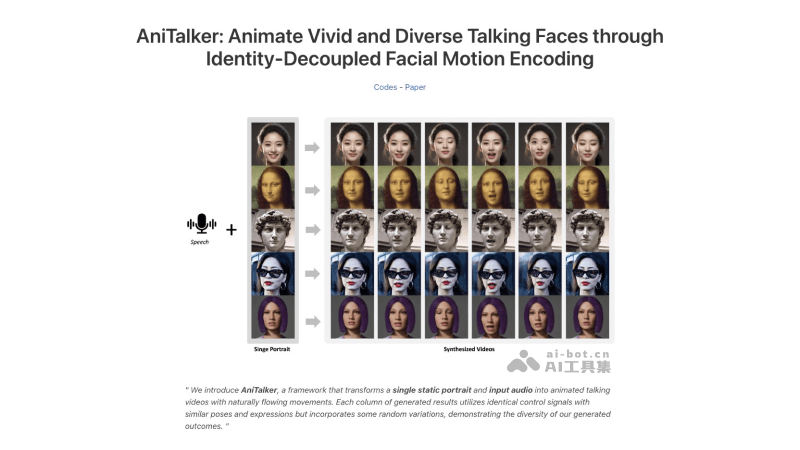
AniTalkeris an open-source framework jointly launched by researchers from the X-LANCE Lab of Shanghai Jiao Tong University and AISpeech, which can convert a single static portrait and input audio into lifelike animated talking videos. The framework captures complex facial dynamics, including subtle expressions and head movements, through a self-supervised learning strategy. AniTalker is based on universal motion representation and identity disentanglement technology, reducing dependence on labeled data, while combining diffusion models and variance adapters to generate diverse and controllable facial animations.
🚀Feature highlights
- Facial animation generation: AniTalker can transform static portrait photos and audio signals into vivid talking facial animations, including precise lip sync and facial expressions and head movements that perfectly match the speech content.
- Diversity and Controllability: Users can adjust inputs and parameter settings according to different needs to generate a series of facial animations with rich expressions and varied movements.
- Realism and Dynamic Performance: AniTalker excels at capturing subtle facial dynamics, including complex nonverbal information such as blinking and smiling, and the precise reproduction of details enhances the realism and expressiveness of the animation.
- Long Video Generation Capability: It is suitable for generating short clips and can also produce long facial animation videos of more than 3 minutes.
✨Use Cases
- Virtual Assistants and Customer Service: AniTalker can generate realistic virtual faces for virtual assistants or online customer service, providing a more natural and friendly interaction experience.
- Film and Video Production: In film post-production, AniTalker can be used to generate or edit actors' facial expressions and movements in scenes that cannot be achieved when capturing the original performance.
- Game Development: Game developers can use AniTalker to create realistic facial animations for game characters, enhancing the game's immersion and the expressiveness of the characters.
- Video Conferencing: In video conferencing, AniTalker can generate virtual faces for participants in situations where privacy needs to be protected or more fun is desired.
9.Linly Dubbing
Linly Dubbing is an intelligent video multilingual AI dubbing and translation tool that integrates multiple AI technologies, including speech recognition, large language model translation, AI voice cloning, and digital human lip-sync technology, to achieve a natural multilingual experience for video content.
🚀Feature Highlights
- Digital Human Lip-Sync Technology: It enables the lip movements of digital human characters to precisely match the dubbing, achieving a highly natural synchronization effect.
- Highly Natural Synchronization: Based on advanced computer vision and speech recognition technology, it can precisely match the lip movements of digital human characters with the dubbing, improving the realism and interactivity of the video.
- Multi-Scenario Applicability: It is suitable for animated characters and can also be applied to various scenarios such as virtual streamers and narrators in educational videos.
✨Use Cases
- Animated Characters: Lip-sync technology can be applied in animation production to make the lip movements of animated characters precisely match the dubbing, improving the naturalness and watchability of the animation.
- Virtual Streamers: When using virtual streamers in live broadcasts or video content, lip-sync technology ensures that the virtual image's lip movements are synchronized with the actual speech, enhancing interactivity and realism.
- Educational Videos: In educational videos, lip-sync technology can be applied to narrators or teaching characters, making the teaching content more vivid and easier to understand.
- Localization of Global Entertainment Content: Lip-sync technology helps maintain consistency between lip movements and dubbing after entertainment content (such as movies, TV series, variety shows, etc.) is translated into different languages, improving the quality of localized content.
10.VASA-1
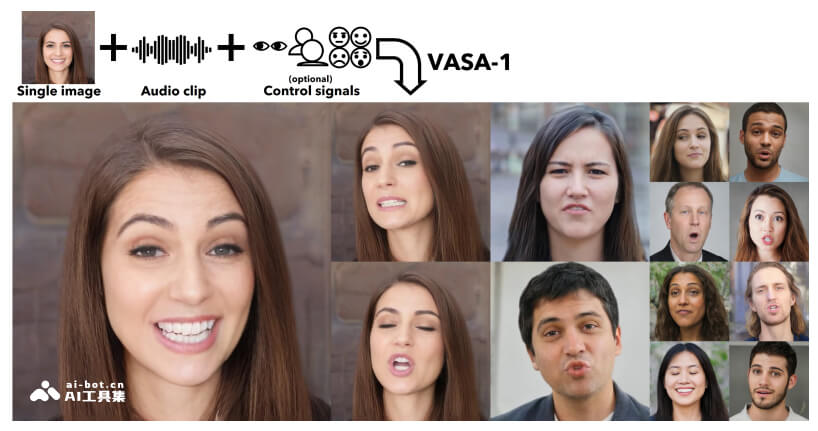
VASA-1 It is a static photo lip-sync video generation framework proposed by Microsoft Research Asia, capable of generating realistic 3D talking facial animations in real time from a single static face photo and a speech audio clip. The core innovation of VASA-1 lies in its holistic facial dynamics and head motion generation model. The model works in the facial latent space, efficiently generating high-resolution videos while supporting online generation and low latency.
🚀Feature Highlights
- Realistic lip-audio synchronization: It can generate lip movements precisely synchronized with the input speech audio, delivering highly realistic talking effects.
- Rich facial expressions: In addition to lip movements, VASA-1 can also capture and reproduce a range of complex facial expressions and subtle emotional details, increasing the realism of the animation.
- Natural head movement: The model can simulate natural head motions, such as turning and tilting, making the generated talking face video more vivid.
- Efficient video generation: VASA-1 supports online generation of 512×512 resolution videos at up to 40 FPS, with extremely low initial latency, making it suitable for real-time applications.
- Flexible and controllable generation: By accepting optional signals as conditions, such as main gaze direction, head distance, and emotion offset, VASA-1 can control the generation process, improving the diversity and adaptability of the output.
- Handling different inputs: VASA-1 can handle photo and audio inputs outside the training distribution, such as artistic photos, singing audio, and non-English speech.
✨Use Cases
- Entertainment industry: VASA-1 can be used to revive deceased actors or create digital characters for new movies, TV series, or video games, opening up new creative possibilities for storytelling and character development.
- Virtual assistants: By providing virtual assistants with lifelike characters that can convey emotions and nonverbal cues, natural and engaging interaction with people becomes possible.
- Telepresence and remote communication: It supports individuals in creating and using personalized characters that can more effectively convey expressions and mannerisms, enhancing the remote communication experience.
- Education and training: Create interactive digital mentors or instructors that can interact with learners in a more immersive and engaging way.
11.Sync Labs
Sync Labs is an AI video dubbing tool that uses AI technology to achieve real-time AI lip synchronization. It provides an advanced AI lip-sync API, supports characters in any video speaking any language, and achieves high-quality lip synchronization, suitable for a variety of video content such as movies, podcasts, games, and animations. It allows creators to record once and create in multiple languages, bringing new possibilities to video content production.
🚀Feature Highlights
- Real-time lip synchronization: Sync Labs can analyze audio data in real time and generate animations that match the mouth shapes of people in the video, achieving precise lip matching.
- Multilingual support: It supports speech recognition and lip synchronization in multiple languages, suitable for global users, allowing video characters to speak in different languages.
- No training required: Simply submit audio and video, and Sync Labs performs synchronization directly, without the need for a complex training process.
- High-quality output: Based on advanced AI technology, it ensures that the synchronized video maintains high quality and realistic effects.
- Fast processing: Compared with traditional lip-sync methods, Sync Labs greatly shortens processing time.
- Flexibility: Supports various video formats and lengths, suitable for different types of content such as dialogues, speeches, songs, etc.
✨Applicable Scenarios
- Film and Television Production: In film or television production, AI real-time lip-sync technology can be used to quickly produce multilingual versions of film and television works, or to achieve perfect lip synchronization when dubbing foreign-language films.
- Education: Educational videos can be translated into multiple languages to expand the audience, and immersive language learning materials can also be created.
- Marketing and Advertising: In the advertising industry, AI lip-sync technology can produce localized advertisements for different regions and cultures, creating multilingual promotional videos for international brands.
- News and Media: In news reporting, multilingual news reports can be quickly produced, creating localized versions for international interviews and speech videos.
12.AniPortrait
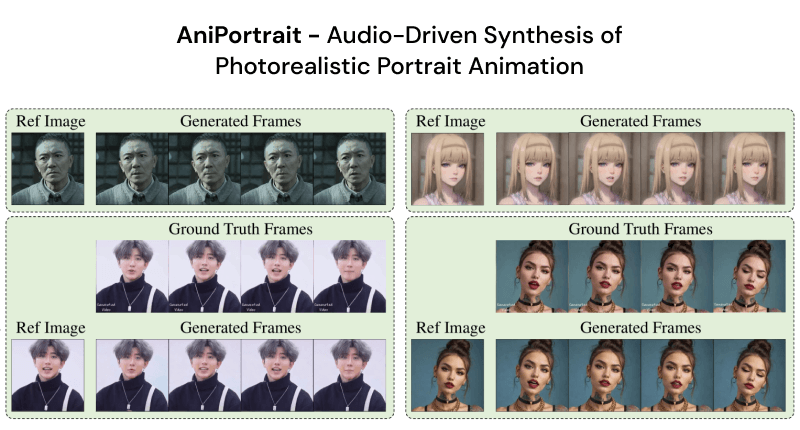
AniPortrait is a photo lip-sync generation framework jointly launched by Huawei and Tencent, capable of converting audio and static portrait images into realistic animations. The core of this technology lies in a two-stage method: first, audio features are extracted from the input audio and converted into a series of 2D facial landmarks; second, a diffusion model and motion module are used to convert these landmarks into coherent and realistic animations.
🚀Feature Highlights
- Audio-Driven Animation Generation: AniPortrait can automatically generate facial animations synchronized with speech based on the input audio file, including lip movement, facial expressions, and head posture.
- High-Quality Visual Effects: Based on a diffusion model and motion module, AniPortrait can produce high-resolution, visually realistic portrait animations, providing an excellent visual experience.
- Temporal Consistency: Ensures the temporal coherence of the animation, making the character movements in the animation smooth and natural, without abrupt jumps or inconsistencies.
- Flexibility and Controllability: Using a 3D facial representation as an intermediate feature, AniPortrait provides flexibility for animation editing and supports users in further customizing and adjusting the generated animations.
- Precise Capture of Facial Expressions and Lip Movements: Through an improved PoseGuider module and multi-scale strategy, AniPortrait can accurately capture and reproduce subtle lip movements and complex facial expressions.
- Consistency with the Reference Image: By integrating the appearance information of the reference image, the framework ensures that the generated animation remains visually consistent with the original portrait, avoiding identity mismatch issues.
✨Applicable Scenarios
- Digital Character Creation: AniPortrait can quickly generate high-quality digital character animations, greatly improving creation efficiency.
- Video Production: Provides video creators with a convenient character animation generation tool, especially suitable for scenarios such as dubbing and narration.
- Virtual Anchors: Can be used to build more natural and expressive AI virtual anchor systems.
- Game Development: Gives NPC characters in games richer facial expressions and movements.