
What is Hallo
Hallo is a technology jointly proposed by researchers from Fudan University, Baidu, ETH Zurich, and Nanjing University.AI lip-syncportrait image animation technology that can drive the generation of realistic and dynamic portrait image videos based on speech audio input. The framework adopts a diffusion-based generative model and a hierarchical audio-driven visual synthesis module, improving the synchronization accuracy between audio and visual output. Hallo's network architecture integrates a UNet denoiser, temporal alignment technology, and a reference network to enhance the quality and realism of the animation, not only improving the quality of images and videos but also significantly enhancing the accuracy of lip movement synchronization and increasing the diversity of motions.
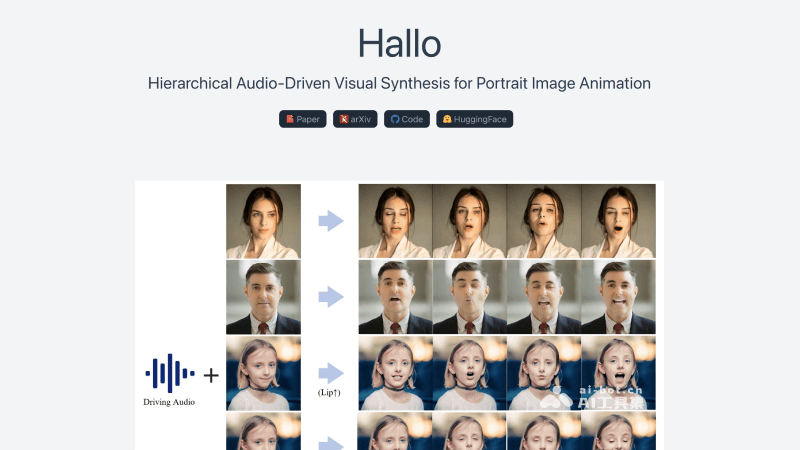
Hallo's Features
- Audio-synchronized animation: Hallo uses advanced audio analysis technology to combine input speech audio with portrait images to generate dynamic facial animations. Through a precise lip movement synchronization algorithm, it ensures that the lip movements in the video animation are synchronized with the sounds in the audio, thereby creating a realistic speaking effect.
- Facial expression generation: Based on the emotions and intonation changes in the audio signal, Hallo can automatically recognize and generate corresponding facial expressions, including smiles, frowns, surprise, and other expressions, making the "performance" of the video animation character more natural and emotionally rich.
- Head pose control: Hallo allows detailed adjustment of the head pose in the video animation, such as tilting and turning of the head, so that the video animation can better reflect the intent and emotion of the audio content and enhance the coordination between vision and hearing.
- Personalized animation customization: Users can customize the animation's style, expressions, and movements according to different application scenarios and personal characteristics. Hallo's personalized customization function supports users in creating unique characters to meet specific visual and emotional expression needs.
- Temporal consistency maintenance: Through temporal alignment technology, Hallo ensures that the movements and expressions in the animation transition smoothly over time, avoiding abrupt and unnatural changes.
- Motion diversity: In addition to the basic movements for synchronizing audio, Hallo also supports the generation of diverse movements and styles. Users can choose different motion libraries as needed to add more dynamic elements to animated characters, such as gestures and blinking, thereby enriching the expressiveness of the video.
Hallo's Official Website Entry
- Official project homepage:https://fudan-generative-vision.github.io/hallo/#/
- GitHub code repository:https://github.com/fudan-generative-vision/hallo
- Hugging Face model library:https://huggingface.co/fudan-generative-ai/hallo
- arXiv technical paper:https://arxiv.org/abs/2406.08801
Hallo's Technical Principles
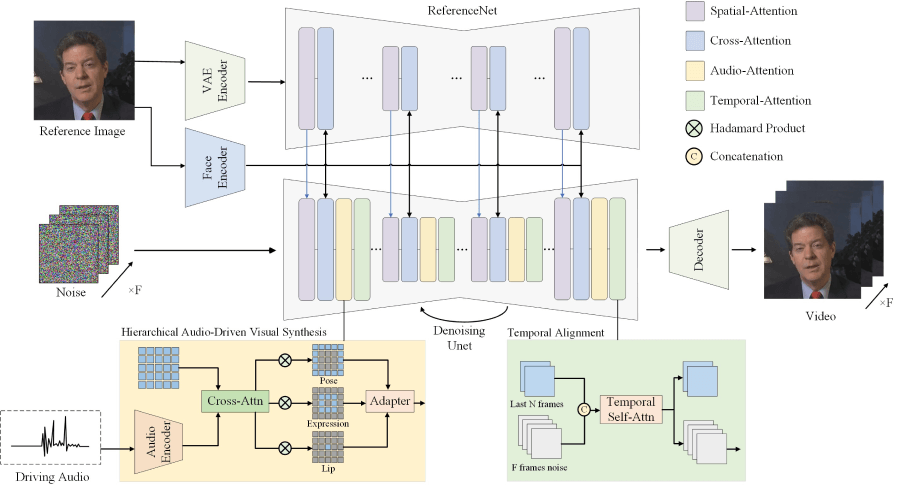
- Hierarchical audio-driven visual synthesis: Hallo adopts a hierarchical approach to process audio and visual information. This hierarchical structure allows the model to separately process lip movements, facial expressions, and head poses, and then fuse these elements together through adaptive weights.
- End-to-end diffusion model: Hallo uses a diffusion-based generative model, a method for generating data from latent space. During the training phase, data is gradually added with noise, and then in the reverse process the noise is removed to reconstruct clear images.
- Cross-attention mechanism: Through the cross-attention mechanism, Hallo can establish connections between audio features and visual features. This mechanism enables the model to focus its attention on the facial regions most relevant to the current audio input.
- UNet denoiser: Hallo utilizes a UNet-based denoiser to progressively remove noise from images and generate clear animation frames. The UNet architecture is renowned for its effectiveness in image segmentation tasks, using low-level feature maps through skip connections to improve generation quality.
- Temporal Alignment Technique: To maintain temporal coherence in animations, Hallo employs a temporal alignment technique, which helps ensure smooth transitions and consistency between consecutive frames.
- Reference Network (ReferenceNet): ReferenceNet is used to encode global visual texture information to achieve consistent and controllable character animation, helping the model reference existing images during the generation process to enhance the visual quality of the output.
- Facial and Audio Encoders: Hallo uses a pretrained facial encoder to extract the identity features of the portrait, while also using an audio feature encoder (such as wav2vec) to convert audio signals into information that can drive animation motion.
- Adaptive Weight Adjustment: Hallo allows adjustment of the weights of different visual components (such as lips, expressions, and pose) to control the diversity and details of the animation.
- Training and Inference: During the training phase, Hallo improves single-frame generation capability by optimizing the parameters of the facial image encoder and the spatial cross-attention module. During the inference phase, the model combines reference images and driving audio to generate animated video sequences.