
What is Vidu Q4 Preview
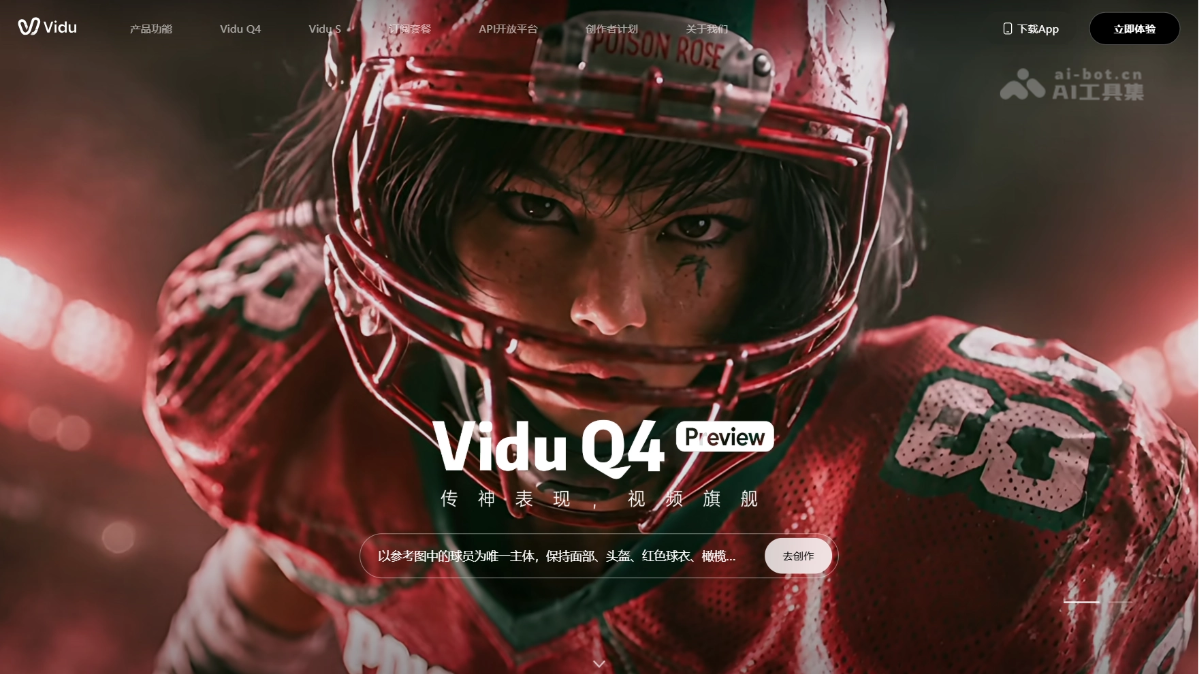
Vidu Q4 Preview is the first preview version of Shengshu Technology's new generation flagshipvideo generationmodel. Vidu Q4 Preview has been comprehensively upgraded in character performance, with more delicate expressions, fuller emotions, and more natural movements. It supports up to 15 reference images and 3 reference audio clips, maintaining high consistency in character appearance, scenes, and voice. In terms of camera language, it strengthens dynamic camera movement, smooth shot transitions, and complex scene continuity. Visual effects such as explosions, fireworks, and particles are also more impactful, supporting 2K/4K and 10-bit color depth output.
Main Features of Vidu Q4 Preview
-
Vivid Character Performance: More delicate expressions, fuller emotions, and more natural body movements. Both the emotional flow of dialogue scenes and the tense bursts of action scenes are full of impact.
-
Voice Reference: Supports up to 3 reference audio clips, enabling unified character voice and more expressive dialogue emotion.
-
Multi-Image Reference Consistency: Supports up to 15 reference images, achieving visual consistency across multiple subjects such as characters, scenes, and props, supporting the realization of complex creative ideas.
-
Camera Narrative: Strengthens dynamic camera movement, shot transitions, and complex shot continuity. Camera work in scenes such as fights, chases, and standoffs is more impactful.
-
Soul-Stirring Visual Effects: Visual effects such as explosions, fireworks, particles, and energy flows occur naturally with the storyline, supporting 2K/4K and 10-bit color depth output.
Technical Principles of Vidu Q4 Preview
- U-ViT Diffusion Transformer Architecture: The core idea of the Diffusion Transformer architecture is to combine diffusion models with Transformers: replace the traditional convolutional U-Net with a scalable Transformer backbone, treat time, text conditions, and noisy image patches uniformly as token sequences, and enhance information flow between shallow and deep layers through long skip connections, achieving better fidelity and inter-frame coherence in image and video generation tasks.
- Diffusion Generation Process: The generation process follows the Latent Diffusion paradigm: use a VAE to compress video into a low-dimensional latent space, patchify spatial-temporal data into token sequences with positional encoding, iteratively denoise by the diffusion Transformer in Transformer blocks based on conditions such as text prompts, capture intra-frame spatial and inter-frame temporal dependencies through global self-attention, gradually restore pure noise into semantic latent representations, and restore them to original resolution frames by a video decoder, supporting output at different resolutions.
- Multi-Reference Conditioning Mechanism: The reference-to-video (reference2video) capability is built on unified condition injection: 1–15 reference images are visually encoded and input into the model as condition tokens together with text prompts. Specific reference subjects can be referenced via tags in the prompt, locking the appearance and identity consistency of characters, scenes, and props throughout generation; 0–3 reference audio clips are injected as voice conditions, making sound and image share the same source and unifying character voice.
- Joint Audio-Video Generation: The Vidu series adopts an end-to-end approach with joint audio-video modeling, simultaneously producing visuals, dialogue, and sound effects in the same generation process, avoiding lip-sync misalignment and rhythm fragmentation caused by separate audio-video generation and later splicing.
How to Use Vidu Q4 Preview
-
Go to the Official Website: Visit Vidu official website orRunningHub, register/log in to your account.
-
Select Generation Mode: Choose "Reference-to-Video" or "Image-to-Video" based on your needs.
-
Upload reference materials: Upload reference images and MP3 audio, and reference the corresponding reference subjects in the prompt using tags.
-
Enter prompt: Describe the scene content, camera movement, and emotional atmosphere. You can optionally enable "Smart Multi-Frame" to enhance the generation effect.
-
Set specification parameters: Select resolution, aspect ratio, and duration.
-
Click Generate: Consume credits to generate a video, with output in about 10 seconds, and you can repeatedly test and adjust.
-
Iterative optimization: If unsatisfied, adjust the prompt, reference images, or camera position description and regenerate until the effect is satisfactory.
-
Export and deliver: After confirming the final video, export it in 2K/4K high-definition specifications; API users can integrate calls through the
viduq4-previewinterface at api.vidu.com.
Core advantages of Vidu Q4 Preview
-
Vivid expressiveness: Delicate facial expressions, full emotions, and natural movements. Both dialogue and action scenes are compelling, continuing the Vidu Q series tradition of being "born for drama."
-
Industry-leading reference capacity: Up to 15 reference images + 3 reference audio clips, achieving multi-subject consistency for characters, scenes, props, and timbre.
-
Strong lens narrative capability: Dynamic camera movement, silky transitions, and complex shot connections are natural, bringing more tension to confrontation, chase, and fight scenes.
-
More impactful visual effects: Complex visual effects such as explosions, pyrotechnics, particles, and energy flows occur naturally with the plot, with clear advantages in anime and high-energy themes.
-
Flagship image quality specifications: Supports 2K/4K output and 10-bit color depth, allowing greater room for lighting, texture, and detail presentation.
Comparison of Vidu Q4 Preview with similar competitors
| Comparison dimension | Vidu Q4 Preview | Kling 3.0(Kling 3.0) |
|---|---|---|
| Technical architecture | U-ViT diffusion Transformer + unified condition injection | All-in-One multimodal vision-language (MVL) architecture |
| Reference image capacity | Up to 15 reference images + 3 reference audio clips(highest among public models) | Element Binding system, with about 4–7 reference images and subjects combined |
| Maximum resolution | 2K / 4K, 10-bit color depth | Native 4K / 60fps (Ultra tier) |
| Single clip duration | 3–16 seconds, audio and video together | 3–15 seconds, extendable to 3 minutes (Professional version) |
| Native audio | Supported, reference timbre consistency | Supported, 5+ language lip sync |
| Camera control | Dynamic camera movement, silky transitions, complex connections (automatic) | 6-shot storyboard system, AI director automatic/manual arrangement |
Application scenarios of Vidu Q4 Preview
- Advertising and e-commerce marketing: Generate multiple versions of opening, script, and shot plans at low cost for A/B testing, then output the best plan in 2K/4K, highlighting product materials, lighting, and visual impact, greatly reducing the production cost and cycle of marketing videos.
- Comic drama / short drama / film and television content production: Achieve cross-episode consistency in character appearance and voice with 15 reference images + 3 audio clips. 16-second synchronized audio and video output is suitable for serialized updates. Expressive acting and tension-filled shots make both dialogue-driven emotional scenes and action-packed bursts more captivating.
- Storyboard preview and creative validation: Quickly transform a script into visualized dynamic storyboards to validate character blocking, camera paths, scene design, and emotional pacing. Let ideas be seen first, then decide which shots are worth investing more production resources in.
- Anime and high-energy genre creation: Dynamic camera movement, silky smooth cuts, and soul-stirring visual effects such as explosions, fireworks, and particles fit the narrative rhythm of hot-blooded anime and action short films. This is Vidu's traditional home turf and advantage.