
What is Vidu Q1
Vidu Q1 is a highly controllable video large model launched by the team of Professor Zhu Jun, Vice Dean of the Institute for Artificial Intelligence at Tsinghua University and founder and chief scientist of Shengshu Technology. It supports the generation of 1080p high-definition videos, with delicate image quality and rich details, and can meet the generation needs of 5-second videos. After the first and last frame function was upgraded, only two images are needed to generate a cinematic natural camera movement effect. Vidu Q1 has precise sound effect control capabilities and supports marking sound effect types and durations on the timeline, with synchronization accuracy reaching ±0.1 seconds. The model optimizes the controllable details of multiple subjects. Users can upload reference images and text instructions to precisely adjust the position, size, and movement trajectory of subjects in the video. It can perform local super-resolution reconstruction for blurred areas, and 4K videos can be enlarged 8 times without mosaics. On the authoritative overseas video generation evaluation lists VBench-1.0 and VBench-2.0, it topped the list with total scores of 87.41% and 60.98% respectively, surpassingRunway, OpenAI Sora, and other models. In the domestic SuperCLUE image-to-video list, Vidu Q1 also took first place on both lists with 63.52 points in the anime style and 67.78 points in the realistic style.
Main Functions of Vidu Q1
- High-Definition Image Quality and Resolution: Supports the generation of high-definition videos at 1080p resolution, with delicate image quality and realistic details.
- First and Last Frame Function: Users only need to upload two images to generate a cinematic camera movement effect. The transition between the first and last frames is smooth and natural, and the camera language feels more "cinematic."
- Sound Effect Generation: A new "one-sentence sound effect generation" function has been added. It can generate background music and sound effects based on prompts, support fine control over the appearance time point of each audio segment, allow segmented control and free overlay, and make sound fit perfectly with the picture.
- Extreme "Quality" Style: The anime style is more stable and smooth, and character actions and emotional expression are more accurate.
- Video Quality and Semantic Consistency: In dimensions such as video quality and semantic consistency on VBench-1.0, Vidu Q1 reaches the SOTA (State of the Art) level, and the generated videos perform excellently in surface realism and intrinsic realism.
- Common Sense Reasoning and Physical Understanding: In the two major dimensions of common sense reasoning and understanding of physical laws on VBench-2.0, Vidu Q1 also performs excellently, demonstrating leading understanding and generation capabilities.
- Precise Adjustment of Subject Attributes: Users can upload reference images and text instructions, select any character or object in the video, and precisely adjust its position (coordinate axis positioning), size (percentage scaling), movement trajectory (custom path curve), and action details (such as "raise hand 15 degrees" and "blink frequency 2 seconds/time"). Actual tests show that when the same instruction generates a video 10 times, the character offset error is less than 5 pixels, while traditional models usually exceed 200 pixels.
- Multi-Subject Consistency: In multi-subject scenes, Vidu Q1 can maintain consistency among subjects, ensuring that the actions, positions, and other aspects of multiple characters or objects in the video are coordinated and unified. This is crucial for producing complex multi-subject video content (such as animation, film and television short dramas, etc.).
- Sound Effect Timeline Control: Users can mark sound effect types and durations on the timeline, such as setting wind sound from 0:00-0:03 seconds (intensity 70%) and glass breaking sound from 0:04-0:05 seconds (left channel priority). The sound effect synchronization accuracy of Vidu Q1 can reach ±0.1 seconds. Compared with the random matching of traditional AI sound effects, this greatly enhances the immersion and appeal of the video.
- Local Super-Resolution Reconstruction: Perform local super-resolution reconstruction on blurred areas; even when 4K video is enlarged 8x, there is still no mosaic. Light and shadow intensity, material texture, depth-of-field blur, and more can be manually adjusted to further improve the video's visual quality.
Technical Principles of Vidu Q1
- Technical Architecture: Vidu Q1 is developed based on the Diffusion Model and the U-ViT architecture. U-ViT combines the scalability of Transformer with long-sequence modeling capability, and can process 1080p videos up to 16 seconds long. The model reduces the spatial and temporal dimensions of video through a video autoencoder, enabling efficient training and inference.
- Multimodal Fusion: Vidu Q1 integrates information from multiple modalities such as text, images, and video, and through flexible multi-element input achieves consistent generation across multiple angles, subjects, and elements. This enables Vidu Q1 to generate videos with a high degree of consistency and dynamism.
- Automatic Generation and Annotation: To address the annotation problem for large-scale video training data, Vidu Q1 uses a high-performance video caption generator to automatically annotate training videos. During inference, a re-captioning technique is applied to restate user input in a form more suitable for the model.
- Expansion of Controllable Video Generation: Vidu Q1 conducted experiments on other controllable video generation tasks, including edge-detection-to-video generation, video prediction, and subject-driven generation, among others. The experiments demonstrated the potential of Vidu Q1 in different application scenarios.
Vidu Q1 Project Address
- API Address:platform.vidu.cn
Vidu Q1 Evaluation Results
- Vidu Q1 topped the VBench-1.0 and VBench-2.0 lists on the overseas authoritative video generation evaluation leaderboard VBench Leaderboard, surpassing Runway, Sora, LumaAI, and other domestic and international video generation models with total scores of 87.41% and 60.98%, respectively, taking first place on both lists in the text-to-video track.
- It reached SOTA (State of the Art, i.e., the current most advanced model) level in comprehensive dimensions such as video quality and video semantic consistency in VBench-1.0, as well as common-sense reasoning and physical understanding in VBench-2.0, demonstrating outstanding performance.
- In the VBench 2.0 evaluation, Vidu Q1 took first place in the two major dimensions of common-sense reasoning and understanding of physical laws, demonstrating leading understanding and generation capabilities.
- In the image-to-video specialized list released by the domestic authoritative general large model comprehensive evaluation benchmark SuperCLUE, Vidu Q1 took first place on both lists with scores of 63.52 in anime style and 67.78 in realistic style, demonstrating its strong and stable image-to-video capabilities at the specialized application level.
How to Use Vidu Q1
- Registration and Login: Visit Vidu 's official website and click Register or Log In.
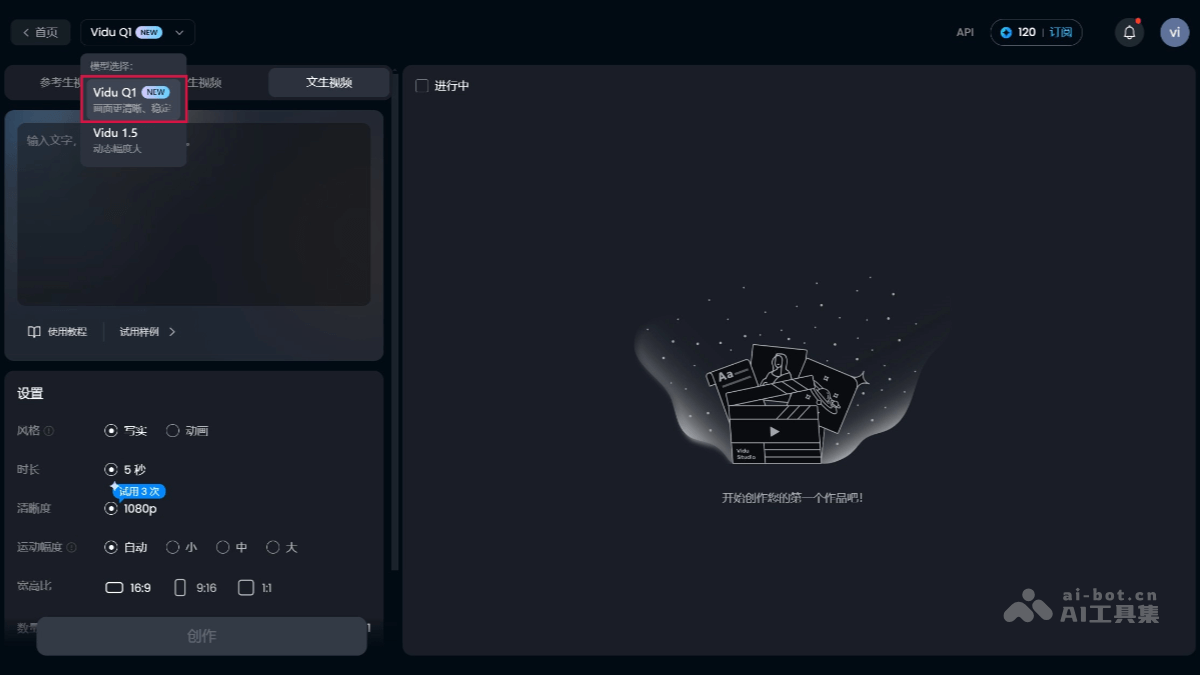
- Model Selection: Select the Vidu Q1 model in the upper left corner.
- Text-to-Video: Enter text to describe the content you want to generate, make personalized settings, and you can choose to try 1080p clarity.
- Image-to-Video: Upload an image and a reference image for the ending frame, and enter an image description of the content you want to generate. Make personalized settings; 1080p clarity is supported.
- Reference-to-Video: The Vidu Q1 model is not currently supported; you can switch to the 2.0 model.
- Create Video: After the settings are complete, click Create to obtain the generated video and make adjustments.
Application Scenarios of Vidu Q1
- Film and Television Production: Vidu Q1 can quickly generate high-quality video content, greatly shortening the production cycle and reducing costs. Its multi-shot generation capability and control over spatiotemporal consistency provide convenience for special effects production, scene editing, and more.
- Advertising: Vidu Q1 can quickly generate video ads in multiple styles and themes, meeting the needs of different clients. Based on user interest and behavioral data, it can achieve precise delivery and personalized recommendations, improving ad conversion rates and effectiveness.
- Animation Production: Vidu Q1's multi-subject consistency control capability is of great value in animation production, ensuring consistency in character details across different perspectives and reducing the workload of animators.