

What is the Open LLM Leaderboard
The Open LLM Leaderboard is an open-source large model leaderboard launched by HuggingFace, the largest large model and dataset community, built on the Eleuther AI Language Model Evaluation Harness. The Open LLM Leaderboard evaluates models across multiple dimensions, including instruction following, complex reasoning, mathematical problem-solving, and professional knowledge Q&A, through a variety of benchmarks (such as IFEval, BBH, MATH, etc.). The leaderboard covers various types such as pretrained models and chat models, and provides detailed numerical results and model input/output details. The Open LLM Leaderboard helps users identify the current state-of-the-art models and drives progress in the open-source community.
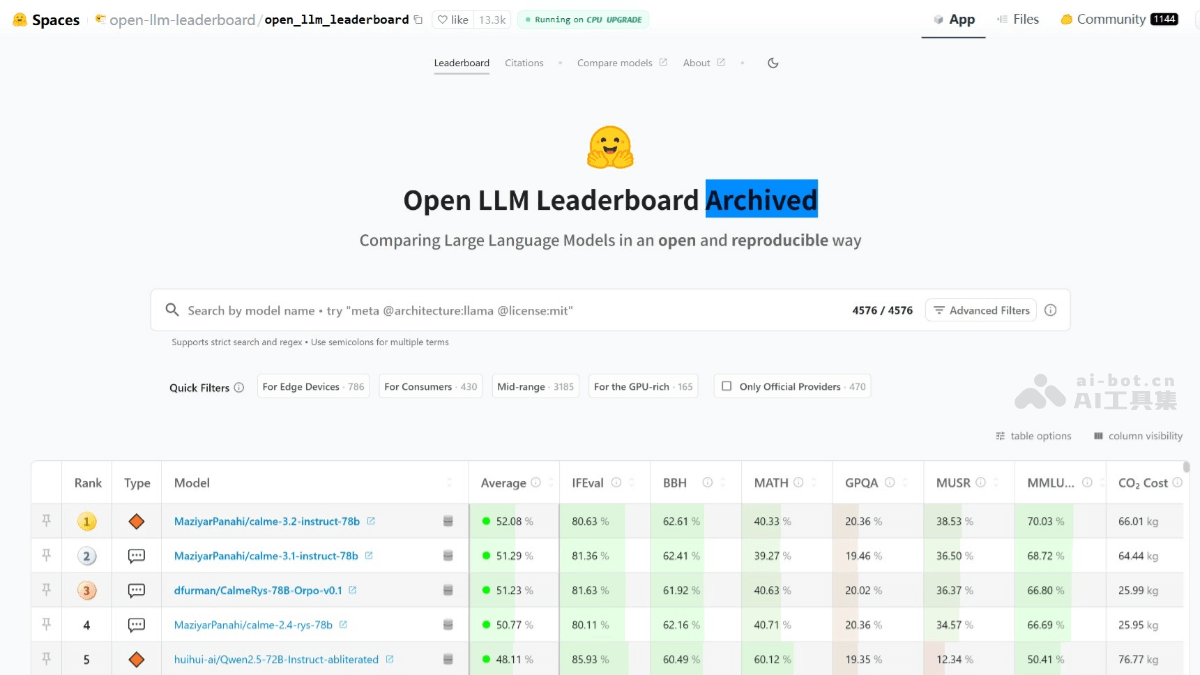
Main Features of the Open LLM Leaderboard
- Multi-dimensional benchmarking: Includes a variety of benchmarks (such as IFEval, BBH, MATH, GPQA, etc.), covering multiple domains including instruction following, complex reasoning, mathematical problem-solving, and professional knowledge Q&A, to comprehensively evaluate model capabilities.
- Support for multiple model types: Supports pretrained models, continually pretrained models, domain-specific fine-tuned models, chat models, etc., covering different application scenarios.
- Detailed result display: Provides detailed numerical results and model input/output details to help users gain an in-depth understanding of model performance.
- Community interaction: Community members tag and discuss models, ensuring the fairness and transparency of the leaderboard.
- Reproducibility support: Provides code and tools to help users reproduce the results on the leaderboard, enhancing the credibility of the research.
Evaluation Benchmarks of the Open LLM Leaderboard
- IFEval: Evaluates the model's ability to follow explicit instructions, such as format requirements, using a strict accuracy metric.
- BBH(Big Bench Hard): Uses 23 highly difficult subtasks covering multi-step arithmetic, algorithmic reasoning, and language understanding to test the model's comprehensive capabilities.
- MATH: Tests the model's ability to solve high school competition-level math problems, requiring strict adherence to a specific output format.
- GPQA(Graduate-Level Google-Proof Q&A Benchmark): A highly difficult knowledge Q&A task designed by experts, covering professional knowledge across multiple domains.
- MuSR(Multistep Soft Reasoning): Uses complex multi-step reasoning problems, such as murder mystery puzzles, to evaluate the model's long-distance context parsing and reasoning capabilities.
- MMLU-PRO(Massive Multitask Language Understanding – Professional): An improved version of the multitask language understanding evaluation, with an increased number of choices, higher question difficulty, and reduced noise.
How to Use the Open LLM Leaderboard
- Visit the leaderboard page: Visit the Open LLM Leaderboard page to view the current model rankings and performance data.
- View model details: Click on the name of a model you are interested in to view detailed information.
- Filter and compare models: Use the filtering function provided on the leaderboard page to filter models by conditions such as model type and performance metrics. Compare the performance of different models across various benchmarks to choose the model that best suits your needs.
- Reproduce evaluation results: If you need to reproduce the evaluation results of a model, use the code tools provided by Hugging Face:
git clone git@github.com:huggingface/lm-evaluation-harness.git
cd lm-evaluation-harness
git checkout main
pip install -e .
lm-eval --model_args="pretrained=<your_model>,revision=<your_model_revision>,dtype=<model_dtype>" --tasks=leaderboard --batch_size=auto --output_path=<output_path>-
-
Replace
<your_model>、<your_model_revision>and<output_path>with actual values. -
For instruction models, add
--apply_chat_templateand--fewshot_as_multiturnoptions.
-
Application scenarios of the Open LLM Leaderboard
- Model evaluation and selection: Developers and researchers quickly screen out the best open-source language models suitable for specific tasks (such as intelligent customer service, content generation, etc.).
- Academic research: Provides a unified benchmark testing platform for academia, helping researchers evaluate model performance and driving the development of language model technology.
- Community interaction: Promotes interaction in the open-source community, encourages developers to submit models to the leaderboard, and share research results.
- Education and learning: As an educational resource, it helps students and beginners understand the evaluation methods and performance metrics of language models, and provides a practical platform.
- Technical validation and comparison: Verifies whether newly developed language models meet industry standards, compares them with other models to identify their own strengths and weaknesses, and provides a reference for optimization.
