
What is the Doubao large model?
The Doubao large model is the AI large model family launched by ByteDance, including Doubao PixelDance、Doubao Seaweed Multiple models such as video generation, text-to-image, image-to-image, simultaneous interpretation, role-playing, speech synthesis, voice cloning, speech recognition, Function Call, and vectorization. The Doubao large model has strong language understanding, generation, and logical capabilities, and can perform personalized creation, emotionally rich speech synthesis, high-precision speech recognition, multi-style image generation, and top-tier video generation. The Doubao large model provides services through Volcano Engine, supporting enterprises and developers in building intelligent applications and promoting the implementation of AI technology in various business scenarios.
The performance of the Doubao large model is outstanding in multiple evaluations. For example, in 11 industry-recognized benchmark test sets including MMLU, BBH, GSM8K, and HumanEval, the overall score of the Doubao-pro-4k model reached 76.8 points, with significant progress in code capability, professional knowledge, and instruction following.
Main functions of the Doubao large model
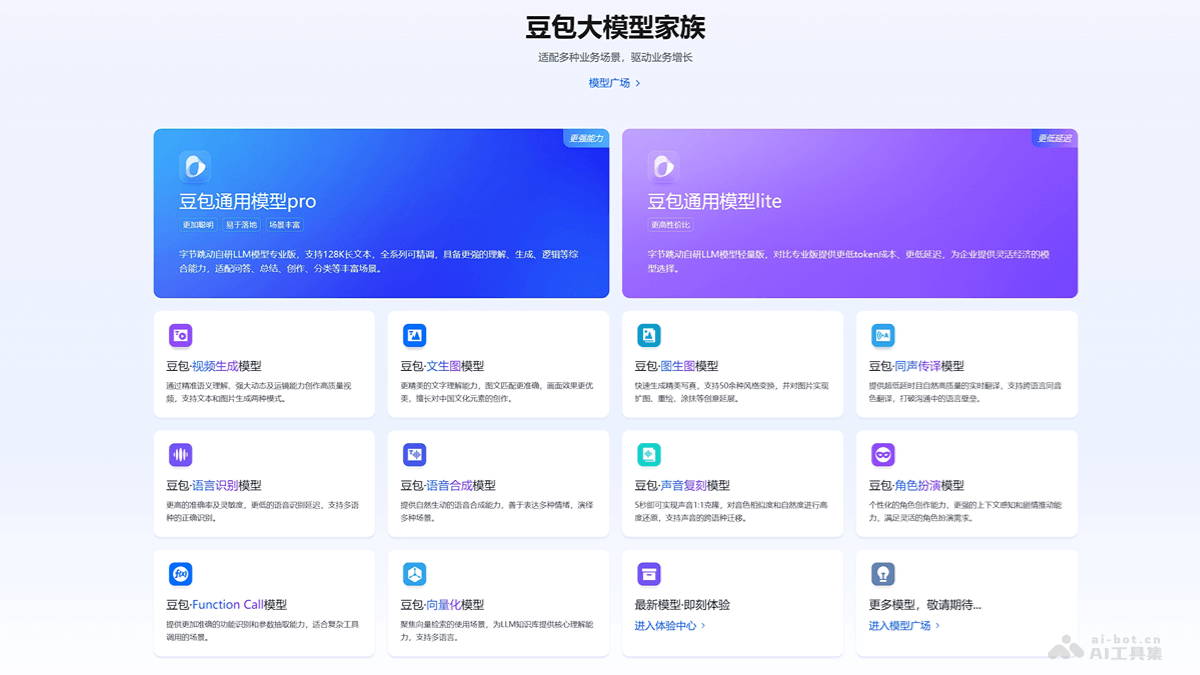
- General model: A self-developed LLM model by ByteDance, supporting 128K long text, with the entire series fine-tunable, and stronger comprehensive capabilities in understanding, generation, logic, and more, suitable for rich scenarios such as question answering, summarization, creation, and classification.
- Video generation: Creates high-quality videos through precise semantic understanding, powerful dynamics, and camera movement capabilities, supporting two modes: text generation and image generation.
- Role-playing: Creates personalized characters, with context awareness and plot advancement capabilities, suitable for virtual interaction and story creation.
- Speech synthesis: Generates natural and vivid speech, can express multiple emotions, suitable for text-to-speech conversion.
- Voice cloning: Quickly clones voices, highly restores timbre and naturalness, supports cross-language transfer, and is used for personalized speech synthesis.
- Speech recognition: Accurately recognizes and transcribes speech, supports multiple languages, and is suitable for voice commands and transcription services.
- Text-to-image: Converts text into images, excels at image-text matching and the creation of Chinese cultural elements, and is used for image generation and visual content creation.
- Image-to-image: Generates new images based on existing images, supporting creative operations such as style transformation, outpainting, redrawing, and smudging.
- Simultaneous interpretation: Provides ultra-low-latency and natural high-quality real-time translation, supports cross-language translation with the same voice timbre, and breaks down language barriers in communication.
- Function Call: Accurately recognizes and extracts function parameters, suitable for complex tool invocation and intelligent interaction.
- Vectorization: Provides vector retrieval capabilities, supports the core understanding of LLM knowledge bases, and is suitable for multilingual processing.
Functional features of the Doubao large model
- Doubao General Model Pro: An advanced language model self-developed by ByteDance, supporting 128K long text processing, suitable for multiple scenarios such as question answering, summarization, and creation.
- Doubao General Model Lite: A lightweight language model, providing lower cost and latency, suitable for enterprises with limited budgets.
- Doubao·Video Generation Model: Leveraging advanced semantic understanding technology to transform text and images into engaging, high-quality video content.
- Doubao Speech Recognition Model: Featuring high accuracy and sensitivity, it can quickly and accurately recognize and transcribe speech in multiple languages.
- Doubao Function Call Model: Designed specifically for complex tool invocation, it provides precise function recognition and parameter extraction capabilities.
- Doubao Text-to-Image Model: Transforms textual descriptions into exquisite images, with particular expertise in capturing and expressing Chinese cultural elements.
- Doubao Speech Synthesis Model: Capable of synthesizing natural, vivid speech and expressing rich emotions and scenarios.
- Doubao Vectorization Model: Focused on vector retrieval, it provides core understanding capabilities for knowledge bases and supports multiple languages.
- Doubao Voice Cloning Model: It takes only 5 seconds to achieve 1:1 voice cloning, delivering highly similar timbre and naturalness.
- Doubao Simultaneous Interpretation Model: Enables ultra-low-latency real-time translation and supports cross-language translation with the same timbre, eliminating language barriers.
- Doubao Role-Playing Model: Possesses personalized character creation capabilities and can perform flexible role-playing based on contextual awareness and plot advancement.
How to Use Doubao Large Models
- Determine Requirements:Clarify the project or business requirements, such as whether text generation, speech recognition, image creation, video generation, etc. are needed.
- Choose the Right Model:Select the appropriate Doubao large model according to the requirements, such as the text-to-image model, speech synthesis, video generation model, etc.
- Register and Access Volcano Engine:Visit the Volcano Engine official website to register an account. It is ByteDance's cloud service platform and provides Doubao large model services.
- Apply for Access Permission:Apply on the Volcano Engine platform for permission to use Doubao large models, and fill in the relevant information and usage scenarios.
- API Integration:Obtain the corresponding API interface information, including the API endpoint, request method, and necessary authentication information.
- Development and Testing:Develop applications according to the API documentation and integrate Doubao large models into your business processes.Conduct thorough testing to ensure that the model output meets expectations.
- Deploy the Application:After testing is completed without issues, deploy the application integrated with Doubao large models to the production environment.
- Monitoring and Optimization:Monitor the application performance and model effectiveness, and optimize based on feedback.
Product Pricing of Doubao Large Models
- Large Language Models
- Pay based on tokens usage:
- Doubao-lite-4k (including the branch version lite-character): context length 4K, input 0.0003 yuan per thousand tokens, output 0.0003 yuan per thousand tokens, post-paid, free quota 500,000 tokens.
- Doubao-lite-32k: context length 32K, input 0.0003 yuan per thousand tokens, output 0.0006 yuan per thousand tokens, post-paid, free quota 500,000 tokens.
- Doubao-lite-128k: context length 128K, input 0.0008 yuan per thousand tokens, output 0.0010 yuan per thousand tokens, post-paid, free quota 500,000 tokens.
- Doubao-pro-4k (including branch versions pro-character and pro-functioncall): context length 4K, input ¥0.0008 per thousand tokens, output ¥0.0020 per thousand tokens postpaid, free quota 500,000 tokens.
- Doubao-pro-32k: context length 32K, input ¥0.0008 per thousand tokens, output ¥0.0020 per thousand tokens postpaid, free quota 500,000 tokens.
- Doubao-pro-128k: context length 128K, input ¥0.0050 per thousand tokens, output ¥0.0090 per thousand tokens postpaid, free quota 500,000 tokens.
- Pay by model unit: exclusive computing resources, more independent and controllable
- Doubao-lite-4k, Doubao-lite-32k: supported performance (TPS) 3000, ¥60 per unit per hour, ¥28,000 per unit per month.
- Doubao-lite-128k: supported performance (TPS) 4500, ¥240 per unit per hour, ¥112,000 per unit per month.
- Doubao-pro-4k, Doubao-pro-32k: supported performance (TPS) 3200, ¥160 per unit per hour, ¥80,000 per unit per month.
- Doubao-pro-128k: supported performance (TPS) 3500, ¥1200 per unit per hour, ¥550,000 per unit per month.
- Pay based on tokens usage:
- Vision models
- Doubao-text-to-image model-Smart Drawing: inference service, ¥0.2 per call, postpaid, free quota 200 calls.
- Speech large models
- Doubao-Speech Synthesis: inference service, ¥5 per ten thousand characters, postpaid, free quota 5,000 characters.
- Doubao-Voice Cloning: inference service, ¥8 per ten thousand characters, postpaid, free quota 5,000 characters.
- Embedding models
- Doubao-embedding: maximum input length 4K, input ¥0.0005 per thousand tokens, postpaid, free 500,000 tokens.
- Model fine-tuning
- Billed by token usage (training text * number of training iterations), charged after training is completed.
- Doubao-lite-4k, Doubao-lite-32k, Doubao-lite-128k: LoRA pricing ¥0.03 per thousand tokens, postpaid.
- Doubao-pro-4k, Doubao-pro-32k, Doubao-pro-128k: LoRA pricing ¥0.05 per thousand tokens, postpaid.
For more model and pricing information, you canvisit the Doubao large model official websiteto get the latest information.
Application scenarios of Doubao large models
- Content creation and media:Use text-to-image, image-to-image, and video generation models to generate visual content such as article illustrations, comics, posters, and short videos.Speech synthesis models provide voiceovers for video and animation production.
- Customer service:Provide virtual customer service and chatbot services through role-playing models.Use speech recognition and speech synthesis models to improve voice customer service systems.
- Education and training:Text-to-image models assist in the production of teaching materials, such as generating teaching illustrations.Role-playing models create personalized learning experiences and virtual teachers.
- Entertainment and games:Use role-playing models in games to create dialogue and behavior for non-player characters (NPCs).Use speech synthesis models to provide natural language communication for game characters.
- Smart assistants:Combine speech recognition and speech synthesis models to develop intelligent personal assistants.Use text-to-image models to generate personalized recommended content.
- Marketing and advertising:Use text-to-image models to automatically generate advertising creatives and marketing materials.Analyze consumer feedback with general models to optimize ad copy.
- Enterprise Automation:Automate complex workflows and tool invocations through Function Call models.Use vectorized models for efficient information retrieval and knowledge management.
- Search and Recommendations:Use vectorized models to improve search engine accuracy and response speed.Combine general models to recommend relevant content or products to users.
- Legal and Financial:Use general models for contract analysis, case research, and compliance checks.Use speech recognition models to transcribe meeting records and interview content.

