
What is Qwen3.5-Omni
Qwen3.5-Omni is an omni-modal large model launched by Alibaba Tongyi Lab, capable of simultaneously understanding text, images, audio, and audio-video inputs. The model adopts a Thinker-Talker division-of-labor architecture and Hybrid-MoE technology, achieving SOTA results in 215 audio/audio-video tasks, surpassingGemini-3.1 Pro. The model supports a 256K ultra-long context, semantic interruption, voice cloning, and voice control, natively integrates WebSearch and Function Call, and possesses naturally emergent Audio-Visual Vibe Coding capabilities, able to directly generate runnable code based on audio-video instructions.
Main Features of Qwen3.5-Omni
-
Omni-modal understanding: The model natively and seamlessly processes text, images, audio, and audio-video inputs, and supports timestamped fine-grained description generation.
-
Intelligent video analysis: The model can generate structured video notes, identifying visual content, dialogue, shot transitions, and sensitive information.
-
Vibe Coding: Without specialized training, code generation capabilities naturally emerge based on audio-video instructions.
-
Human-level conversation: Supports semantic interruption and voice control, can distinguish environmental noise from genuine interjections, and adjusts emotion and speech rate in real time.
-
Voice cloning: Upload a recording to customize an exclusive AI voice, supporting natural generation in multiple languages.
-
Intelligent task execution: Natively integrates WebSearch and Function Call, autonomously judging and invoking tools to complete complex tasks.
Technical Principles of Qwen3.5-Omni
- Thinker-Talker division-of-labor architecture: Thinker is responsible for multimodal understanding, receiving visual and audio signals and encoding positional information via TMRoPE; Talker is responsible for speech generation, using RVQ encoding based on Thinker's output to achieve efficient speech synthesis, with the two collaborating to separate understanding and generation.
- Hybrid-Attention MoE:Tasks such as listening, seeing, and understanding are assigned to different expert networks, avoiding interference between modalities, and achieving 215 SOTA performances while maintaining text and visual capabilities without degradation.
- ARIA dynamic alignment technology: The model adaptively adjusts the rate of text and speech units, solving the problems of missing characters and unclear pronunciation of numbers caused by traditional fixed ratios, and supporting real-time voice control responses.
How to Use Qwen3.5-Omni
- API call: VisitAlibaba Cloud Model Studioand search for Qwen3.5-Omni on the official website to call the API, which offers three sizes—Plus, Flash, and Light—to meet the performance and cost needs of different scenarios.
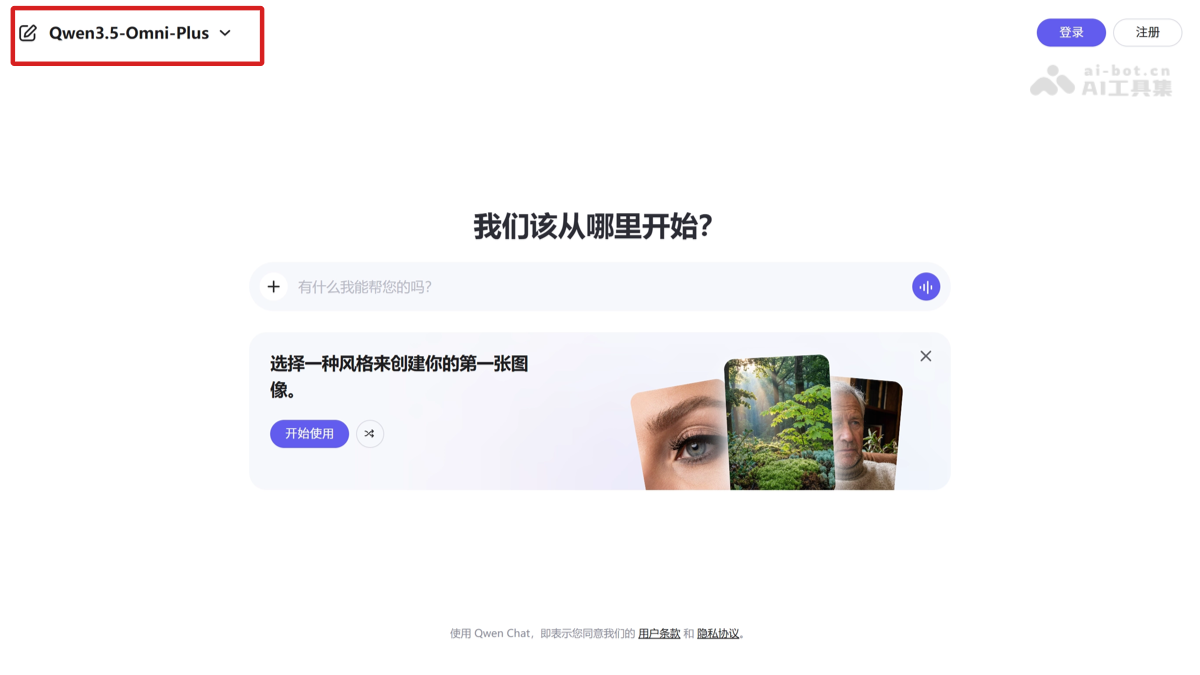
- Online experience: Directly on Qwen Chat experience all the capabilities of Qwen3.5-Omni, with no deployment required for a quick start.
Key Information and Usage Requirements of Qwen3.5-Omni
-
Publisher: Alibaba Tongyi Lab
-
Model positioning: Omni-modal large model (text/image/audio/audio-video)
-
Version specifications: Offers three sizes: Plus, Flash, and Light
-
Performance results: 215 SOTA items, comprehensively surpassing Gemini-3.1 Pro
-
Context length: 256K (supports 10 hours of audio / 1 hour of video)
-
Language support: 74 speech recognition languages + 39 dialects
-
Core architecture: Thinker-Talker division of labor + Hybrid-MoE
Core Advantages of Qwen3.5-Omni
-
Native Full-Modality Unification: Truly seamless understanding of text, images, audio, and audio-video.
-
Top-Tier Performance: 215 SOTA benchmarks topped, with audio/audio-video capabilities comprehensively surpassing Gemini-3.1 Pro.
-
Ultra-Long Context: 256K context length, supporting 10 hours of audio or 1 hour of video processing.
-
Natural Interaction: Supports semantic interruption, voice control, and voice cloning, delivering a conversation experience close to that of a real person.
-
Emergent Capabilities: Possesses Audio-Visual Vibe Coding without specialized training, able to generate code based on audio and video.
-
Intelligent Execution: Native support for WebSearch and Function Call, seamlessly connecting chat to task execution.
-
Multilingual Coverage: 74 languages of speech recognition + 39 dialects, breaking down language barriers.
Comparison of Qwen3.5-Omni with Similar Competitors
| Comparison Dimension | Qwen3.5-Omni | Gemini-3.1 Pro | GPT-4o |
|---|---|---|---|
| Publisher | Alibaba Tongyi Lab | OpenAI | |
| Modality Support | Text/Image/Audio/Audio-Video | Text/Image/Audio/Audio-Video | Text/Image/Audio/Audio-Video |
| Context Length | 256K (10 hours audio/1 hour video) | Specific duration not disclosed | 128K |
| Audio Understanding SOTA | 215 leading | Surpassed | Partially behind |
| Audio-Video Understanding | Comprehensively leading | Overall on par | Not a focus of optimization |
| Speech Recognition Languages | 74 + 39 dialects | Multilingual support | Multilingual support |
| Voice Cloning | Supported | Supported | Limited support |
| Vibe Coding | Naturally emergent | Requires specialized optimization | Requires specialized optimization |
| Semantic Interruption | Supported | Supported | Supported |
| Voice Control | Supported (volume/emotion/speech rate) | Limited | Limited |
Qwen3.5-Omni Application Scenarios
-
Video Creation and Editing: Automatically generates structured descriptions with timestamps, recognizes scenes, dialogue, and shot transitions, detects sensitive content, and turns long videos into searchable notes.
-
Smart Meeting Assistant: Transcribes meeting content in real time, distinguishes speakers, generates meeting minutes, and supports multilingual recognition and translation.
-
Code-Assisted Development: Directly generates front-end pages or Python code based on design mockups or spoken requirements, enabling Vibe Coding.
-
Personalized Voice Assistant: Clones a专属 voice to create a digital avatar, supports voice control of volume and emotion, and provides companion-style interaction.
-
Multilingual Real-Time Communication: The model supports 74 languages of recognition + 39 dialects, enabling cross-language real-time conversation and translation.
-
Intelligent Task Execution: Combine WebSearch with tool invocation to complete complex tasks such as checking the weather, booking hotels, and searching for information.