
What is Qwen3-235B-A22B-Thinking-2507
Qwen3-235B-A22B-Thinking-2507 is the world's most powerful open-source reasoning model released by Alibaba. Based on a sparse Mixture of Experts (MoE) architecture with 235 billion parameters, it activates 22 billion parameters each time, and has a 94-layer Transformer network and 128 expert nodes. The model is designed specifically for complex reasoning tasks and supports 256K native context processing capability, enabling it to handle long texts and deep reasoning chains. In terms of performance, Qwen3-235B-A22B-Thinking-2507 has significantly improved in core capabilities such as logical reasoning, mathematics, scientific analysis, and programming, especially setting new best results for global open-source models in benchmarks such as AIME25 (mathematics) and LiveCodeBench v6 (programming), surpassing some closed-source models. It also performs excellently on general tasks such as knowledge, creative writing, and multilingual capabilities.
The model adopts the Apache 2.0 open-source license and is free for commercial use. Users can experience and download it throughQwenChat, the ModelScope community, or Hugging Face. Pricing is $0.7 per million input tokens and $8.4 per million output tokens.
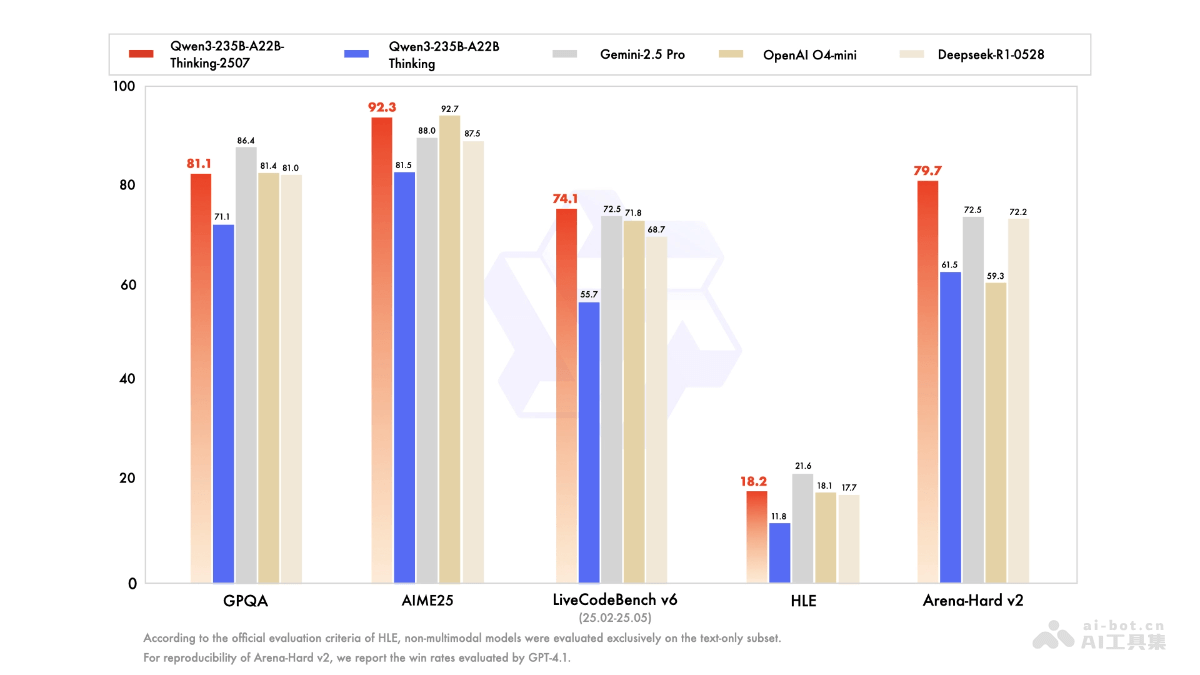
Main features of Qwen3-235B-A22B-Thinking-2507
-
Logical reasoning: Performs excellently in logical reasoning tasks and can handle complex multi-step reasoning problems.
-
Mathematical computation: Significantly improved mathematical ability, especially setting new best results for open-source models in highly difficult mathematics tests such as AIME25.
-
Scientific analysis: Can handle complex scientific problems and provide accurate analysis and solutions.
-
Code generation: Can generate high-quality code and supports multiple programming languages.
-
Code optimization: Helps developers optimize existing code and improve code efficiency.
-
Debugging support: Provides code debugging suggestions to help developers quickly locate and solve problems.
-
256K context support: Natively supports 256K long-text processing capability, can handle ultra-long contexts, and is suitable for complex document analysis and long-form conversations.
-
Deep reasoning chain: Automatically enables multi-step reasoning without the need for users to manually switch modes, suitable for tasks requiring deep analysis.
-
Multilingual conversation: Supports conversation and text generation in multiple languages, meeting cross-language communication needs.
-
Instruction following: Can accurately understand and execute user instructions and generate high-quality text output.
-
Tool calling: Supports use in combination with external tools to extend the model's functionality.
Technical principles of Qwen3-235B-A22B-Thinking-2507
- Sparse Mixture of Experts (MoE) architecture: Qwen3-235B-A22B-Thinking-2507 adopts a sparse Mixture of Experts (MoE) architecture, with a total parameter count of 235 billion and 22 billion parameters activated per inference. This architecture contains 128 expert nodes, and each token dynamically activates 8 experts, balancing computational efficiency and model capability.
- Autoregressive Transformer structure: The model is based on an autoregressive Transformer structure, has 94 Transformer layers, supports ultra-long sequence modeling, and natively supports a 256K context length. This enables the model to handle complex long-text tasks.
- Reasoning mode optimization: Qwen3-235B-A22B-Thinking-2507 is specifically designed for deep reasoning scenarios and by default is forced into reasoning mode. It performs outstandingly in fields that require professional knowledge, such as logical reasoning, mathematical computation, scientific analysis, programming, and academic evaluation.
- Training and Optimization: The model further improves performance through a two-stage paradigm of pretraining and post-training. In multiple benchmark tests, such as AIME25 (mathematics), LiveCodeBench (programming), and others, the model set a new global best result among open-source models.
- Dynamic Activation Mechanism: The dynamic activation mechanism in the MoE architecture allows the model to dynamically select expert nodes during inference based on task complexity.
Project address of Qwen3-235B-A22B-Thinking-2507
- HuggingFace Model Library:https://huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507
Application scenarios of Qwen3-235B-A22B-Thinking-2507
-
Code Generation and Optimization: It can generate high-quality code and help developers optimize existing code.
-
Creative Writing: It performs outstandingly in creative writing, story creation, copywriting, and other areas, and can provide rich creativity and detailed ideas.
-
Academic Writing: It can assist in writing academic papers, literature reviews, and more, and provide professional analysis and suggestions.
-
Research Proposal Design: It helps design research proposals and provides scientifically reasonable suggestions.