
What is QVQ-Max
QVQ-Max is a visual reasoning model launched by Alibaba Tongyi, and is theQVQ-72B-Previewofficial upgraded version of. QVQ-Max can "understand" image and video content, and combine information to analyze, reason, and solve problems. QVQ-Max supports applications in learning, work, and life scenarios, such as solving math problems, assisting with data analysis, and providing outfit suggestions. QVQ-Max shows strong potential in visual reasoning capabilities, and is expected to become a practical visual intelligence assistant, helping people solve more real-world problems.
Main Features of QVQ-Max
- Image Parsing: Quickly identify key elements in an image, including objects, text labels, and small details that are easily overlooked.
- Video Analysis: Analyze video content, understand the scene, and infer subsequent plot based on the current frame.
- In-depth Reasoning : Further analyze image content and reason by combining relevant background knowledge.
- Creative Generation: Create role-playing content according to user needs, such as designing illustrations and writing short video scripts.
Performance of QVQ-Max
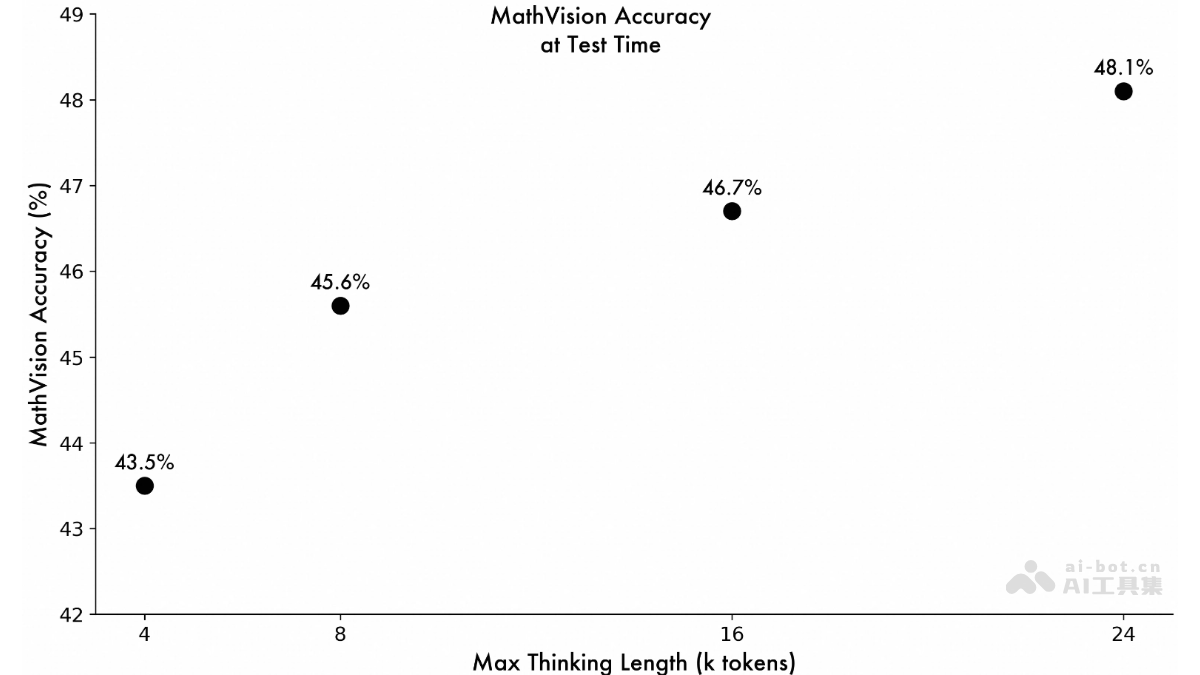
In the MathVision benchmark test, by adjusting the model's maximum thinking length, the model's accuracy continued to improve, showing great potential in solving complex math problems.
Generation Examples of QVQ-Max
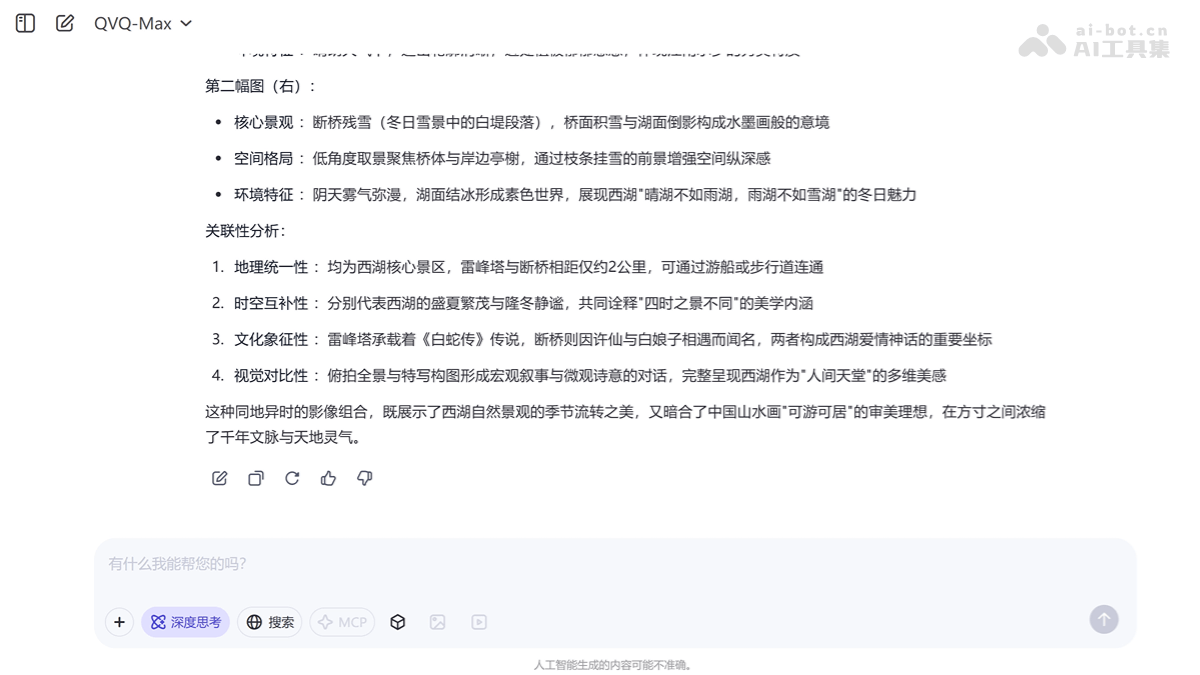
- Multi-image Recognition
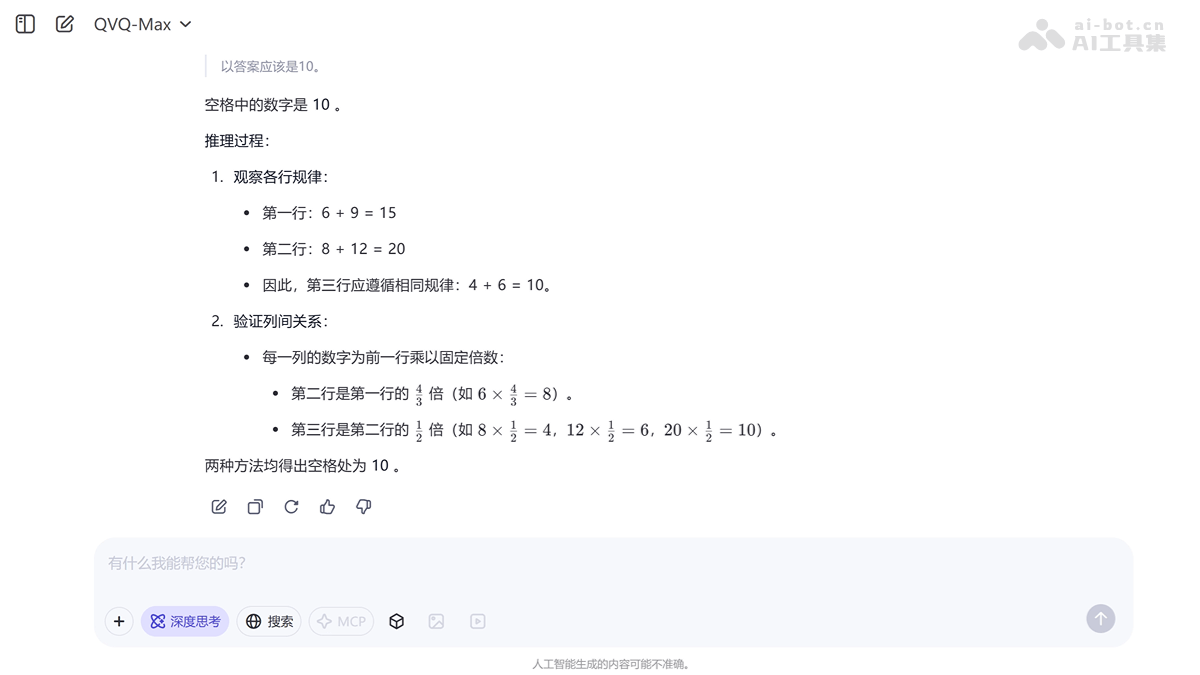
- Mathematical Reasoning
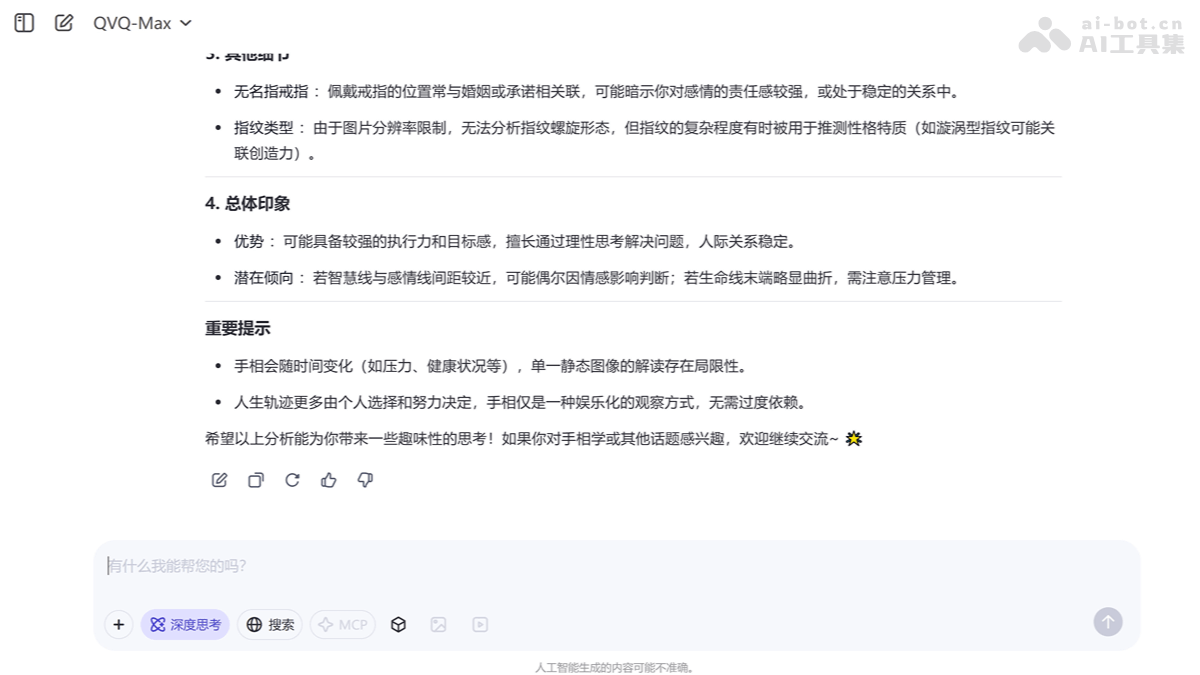
- Palm Reading
QVQ-Max Project Address
- Project Official Website:https://qwenlm.github.io/zh/blog/qvq-max
How to Use QVQ-Max
- Visit the Website: VisitQwenChat's official website.
- Register and Log In: Create an account and log in according to the prompts.
- Enable Visual Reasoning Function: Select the QVQ-Max visual reasoning model in the web interface.
- Enter a Question or Task: Upload images or videos in the input box, and describe the task or question.
- Submit the Question: After entering, submit it.
- Wait for the Model Response: The model generates an answer or solution based on the input content.
Future Plans of QVQ-Max
- Improve Observation Accuracy: Based on visual content verification techniques (such as grounding), verify the model's observation results on images and videos to improve recognition accuracy.
- Strengthen Visual Agent Capabilities: Enhance the model's ability to handle multi-step and complex tasks, such as operating smartphones and computers, and even participating in games, becoming a more powerful visual intelligence assistant.
- Enrich Interaction Methods: Allow the model to break through text limitations during thinking and interaction, covering more modalities such as tool verification and visual generation, providing a richer interactive experience.
Application Scenarios of QVQ-Max
- Workplace Assistance: Assist with data analysis, information organization, programming code writing, and other work to improve efficiency.
- Learning Tutoring: Help students solve difficult problems in subjects such as mathematics and physics.
- Life Assistant: Recommend outfit plans based on wardrobe photos, guide cooking based on recipe images, and provide practical advice in daily life.
- Creative Creation: Supports artistic creation, such as designing illustrations, generating short video scripts, creating role-playing content, etc., inspiring creative inspiration.
- Visual Analysis: Analyzes complex images such as architectural drawings and engineering charts to assist decision-making and design in professional fields.