"Manus Has No Secrets" is a 70-page PPT explaining AI Agent written by teacher Minghao. It mainly introduces the process of AI Agent technology from L1 to L3, and discusses the definition, implementation principles, user experience, and future development trends of AI Agent. Through the analysis ofManusand other Agent products, it deeply discusses the current state, challenges, and future directions of AI technology. (A verbatim transcript is attached at the end of the article)
Starting from the definition of Agent, it proposes a shift from "features" to "seeing," emphasizing that the core of Agent lies in its generality and its ability to handle complex tasks. Agent is defined as an intelligent entity that can autonomously complete tasks, perform reasoning, and interact, with the goal of enabling users to achieve complex functions through simple natural language instructions.
It discusses the technical principles of Agent implementation, including the application of technologies such as pretrained models, reinforcement learning, and few-shot learning. It particularly mentions the concept of "Less structure," emphasizing the importance of letting models autonomously explore thinking paradigms rather than relying on overly structured methods.
From the user's perspective, it discusses the experience and perception of using Agent. Through specific use cases, it shows the advantages and shortcomings of Agent in practical applications. For example, Manus performs excellently when handling complex tasks, but in some cases may also experience performance degradation or errors.
It compares the gap between the performance of Agent in practical applications and expectations, and analyzes the problems and challenges existing in current Agent technology. Although Agent has made significant progress in complex task handling, multimodal interaction, and other aspects, performance bottlenecks still exist in some tasks.
It focuses on introducing the birth background, design philosophy, and technical innovation of the Agent product Manus. Through its innovative interaction methods and powerful task handling capabilities, Manus demonstrates the potential of Agent technology. Manus's design philosophy is to enable users to complete complex tasks through simple natural language instructions, without requiring users to perform complex operations.
Standing at the height of the industry, the article analyzes the development process of the AI industry over the past few years, as well as possible future development trends. It discusses the impact of technologies such as large models, Agent technology, and multimodal interaction on the AI industry, and how to promote the further development and application of AI technology.
It provides a comprehensive summary and reflection on the concept, technical implementation, user experience, and other aspects of Agent. It proposes expectations and suggestions for the future development of Agent, including how to improve Agent's generality, performance, and user experience, and how to establish advantages in market competition.
"Manus Has No Secrets - 70-page PPT Explains AI Agent"
Introduction
Hello everyone, I'm Minghao. I checked my Xiaoyuzhou backend, and it's been just over half a month since my last solo blog update on PPT. In the last episode, I talked about DeepSeek and some expectations for all Agents in 2025. But looking back now, I realize that what I said about Agents at the time was actually somewhat vague. I essentially took a rather clever shortcut approach to that chapter's content at that point in time. So, looking back, that section didn't really have many viewpoints; it was more like an arrangement and combination of existing information.
Why is that? To be honest, at that point in time, neither I nor the industry as a whole had a very clear understanding of Agents. This directly leads to today's topic. Over the past week or so, the entire AI industry has been talking about Manus. As an industry observer, I've also gained deeper awareness and understanding of this matter, which is why today's podcast episode came about.
Background and Significance of Manus
Two and a half months of 2025 have already passed, and I've made three super-long PPTs. Today's content is called "Manus Has No Secrets." I originally added a subtitle called "Will 2025 Be the Year of AI Agents?" But during the process of making the PPT, I found that this question might not need to be asked anymore. Let's formally begin today's content, which has no secrets. This PPT has about five chapters, and if you need it, you can also download my PPT document.
The titles of the five chapters are: Core Narrative Definition, Agent Implementation Principles, Manus User Experience, and some final blunt output. What I'm glad about is that when you have a relatively good understanding of something, you can be more tolerant. When you don't understand it as well, you tend to just list information. Let's formally begin today's content.
From DeepSeek to Manus
About a month ago, my previous PPT was titled "Looking at the 2025 AI Industry Development from DeepSeek's Explosive Popularity." This PPT covered the entire process of DeepSeek's explosive rise, the AI industry narrative over the past two years, new potential for momentum, and the final chapter on Agents. But actually, I think the first three of these four chapters were all old stuff. The fourth chapter should have had some viewpoints and highlights, but limited by my awareness and understanding of this industry, I feel that the fourth chapter about DeepSeek and AI Agents at the time wasn't quite ideal.
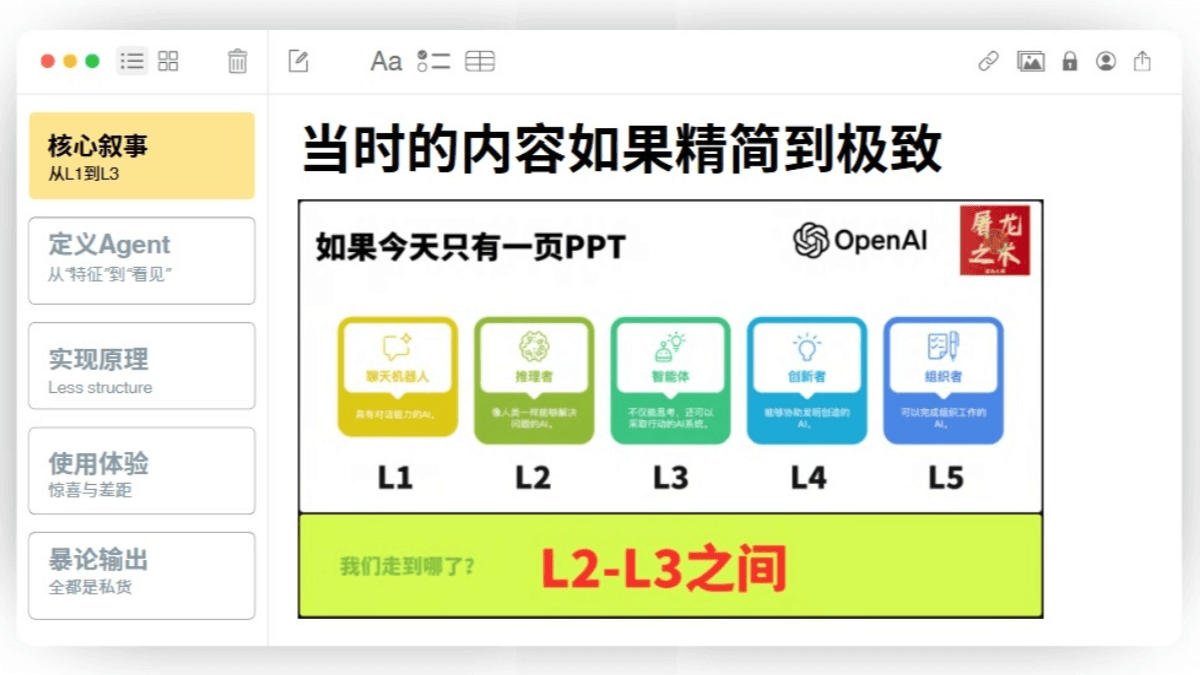
Fortunately, we've arrived at today's topic. Similarly, in my previous podcast's PPT, I mentioned that if that roughly 70-page PPT were summarized in just one page, it would be the L1 to L5 defined by OMI. We are currently between L2 and L3. Specifically, L1 is Chatbot, represented by ChatGPT. Many products we can use today are L1. L2 is reasoning models, such as OpenAI's O1, DeepSeek 21, and the series of reasoning models released by top manufacturers afterward. L3 is the most directly discussed topic today—Agent.
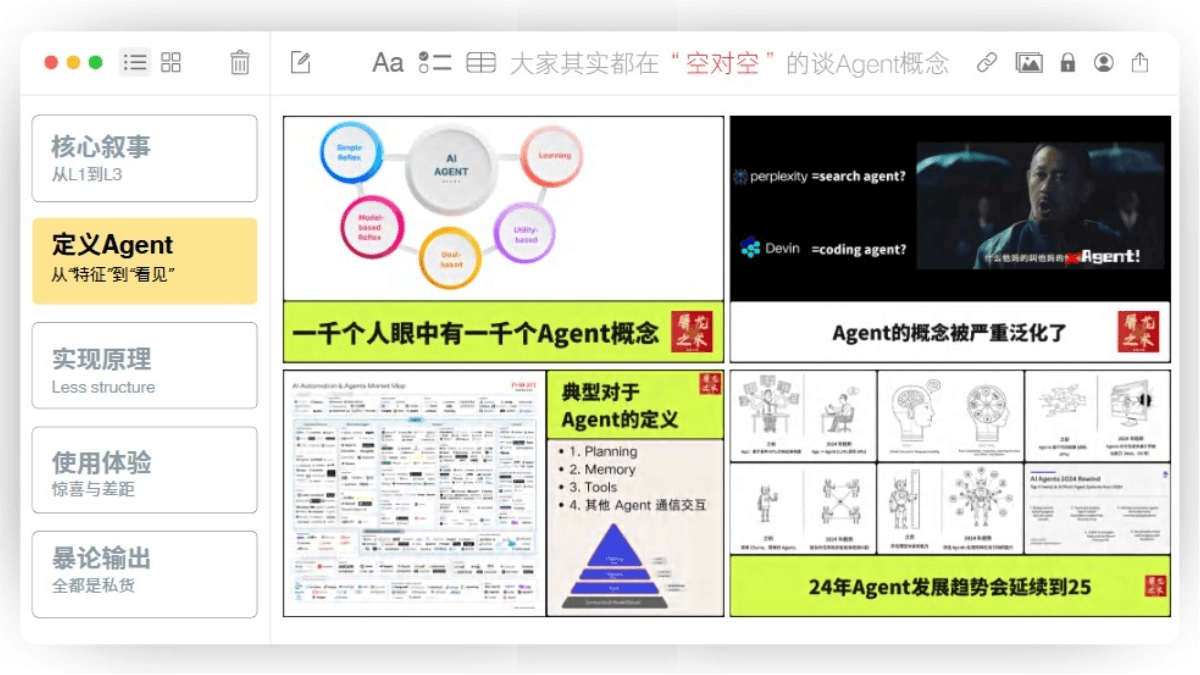
In my previous PPT, I also mentioned that the concept of Agent has been infinitely generalized. Today is good—someone has defined it more clearly. So if today I still had to summarize everything in just one page of PPT, I could still use these PPTs to summarize it.
Detailed Interpretation from L1 to L3
Let's talk about L1 to L3 in detail. Actually, when I was putting together the PPT earlier, I didn't explain it in that much detail—I just listed some questions. For example, if we go back further from LE's Chatbot, to the wave of AI 1.0-era model companies that emerged in 2014 and 2015, they are actually still around today, such as China's AS Xiaolong. So, thinking back, what was the biggest difference between AI 1.0 in that era and AI in the large-model era? How did we get from the way things were then to large models, to GPT? And then think about the end of 2022—actually GPT-3 was released in mid-2022, and then 3.5 was released. It wasn't until ChatGPT was released on November 30, 2022, that it was defined as the industry reaching a milestone.
What I want to ask is: what did ChatGPT mean for GPT-3.5? This is L1. Then when we go from L1 to L2, from OpenAI's O1 released in September 2023 to DeepSeek 21 released in 2025, how did we get to L2? There's another point: why does every major update of large models seem to kill off a wave of application companies? Extending this question, it becomes: are models and products ultimately unified or separate? Some might say the model is the product, while others might say models and products should be separate. So does this question have different answers at different stages?
My core idea is actually very simple: what I just asked about—how we went from the earlier 1.0 era to the large-model era, and then from foundation large models to reasoning models, to today where we're exploring Agents.
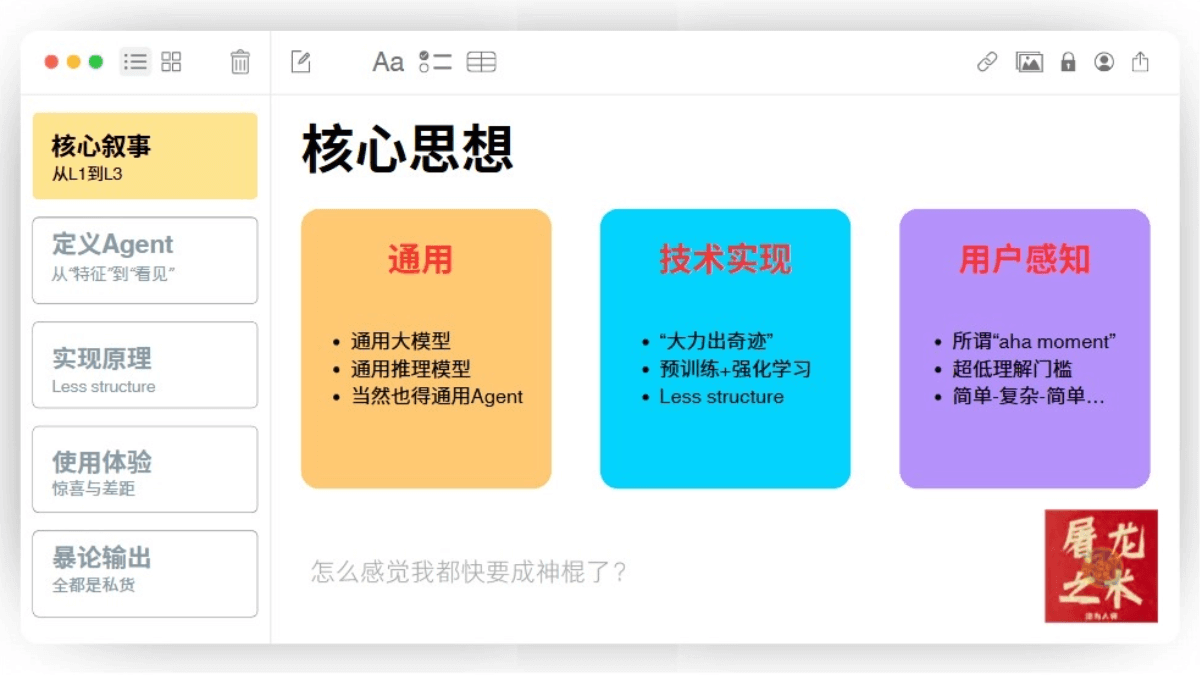
Keywords: general-purpose, technical implementation, user perception
The first keyword I wrote is "general-purpose," meaning that the large models in this step are called general-purpose large models. When it comes to reasoning models, we also started working on what are called general-purpose reasoning models. Because we have hardly made any vertical industry-specific vertical models, right? Once reasoning models came out, they were general-purpose. Pushing this further, if L3 is Agents, then shouldn't it also be a general-purpose Agent?
The second keyword is "technical implementation." We just asked how we walked step by step from the earlier AI 1.0 to large models—we previously used a keyword: "brute force yields miracles," right? By L2, reinforcement learning became important. At L3, or in the process from AI 1.0 to L1 and then to L2, you'll find that everyone has consistently followed a view: as little control as possible, give more data, use more reinforcement learning, and let the model learn on its own. This is the process of technical implementation.
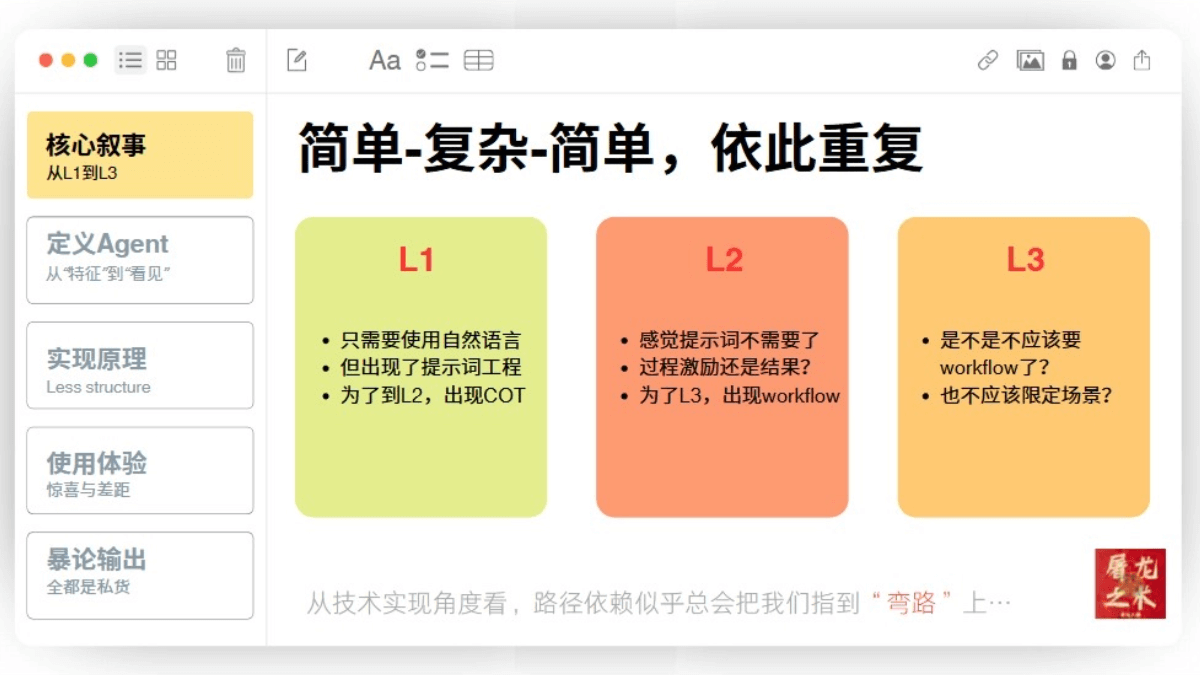
The third keyword is "user perception." That is, for a user, how do they perceive changes in technology. People often talk about the so-called "Aha Moment," that moment when users go wow as if they've seen magic. For an ordinary person, is that such a hard thing to understand? Then you'll find that from L1 to L2 to L3, it's all going through a process of changing from simple to complex and then back to simple and then to complex again. So if we summarize the whole process from L1 to L3, I'd say there are a few keywords: general-purpose, technical implementation, user perception. It sounds a bit like mysticism, right? Let's look at them one by one.
The Importance of Generality
Let's look at "general-purpose" first. I used a page from a PPT that Teacher Kaifu presented at a press conference when Innovation Works was just founded in 2015. He talked about how AI 2.0, that is, large models, overcame the limitations of AI 1.0's single-domain and multi-model approaches. For example, in the earlier 1.0 era, we used a single dataset and then trained fixed models in a single scenario. In the large-model era, it became general-purpose, right? This emerged in the large-model era.
The Path of Technical Implementation
So how did we get to L2? If you are interested, you can go back and watch my previous blog episode on DeepSeek in detail. After O1 was released, the world's mainstream model vendors all wanted to reproduce O1's reasoning model. So they used two paths or two technical approaches. One is called COT (chain of thought). People think that letting a large model think step by step is called chain of thought. After chain of thought emerged, it became a question of, during the training process, whether we reward each link in the chain or reward the result. So at that time there was a route that targeted each process, namely PRI (process reward).
But the final result tells everyone that whether it was Kimi's O1, which emerged first, or DeepSeek's RE, when we look at their open-source articles and some of their employees' social media posts, it ultimately proved to rely entirely on reinforcement learning from results. The whole process of how we got to L2 is that we do not need to impose more restrictions on the model itself during the process, just like when AlphaGo appeared and then AlphaZero. That is, without needing to learn game records from humans, we can obtain a stronger AlphaGo model, and it broke free from human experience.
DeepSeek is the same. DeepSeek's base model is called V3. Based on V3's model capabilities, reinforcement learning was done, rewarding only the results of the model itself, and then RE Zero appeared, just like AlphaZero. This is the whole process of how we got to L2. Then from RE Zero, after a little more pretraining, a simple increase in basic information, and data adjustments, we got R1, which we are using today. And R1's training plan and method also appeared on Llama and Qwen at the same time, and also improved the efficiency of those models. This is the whole process of how we got to L2.
Changes in user perception
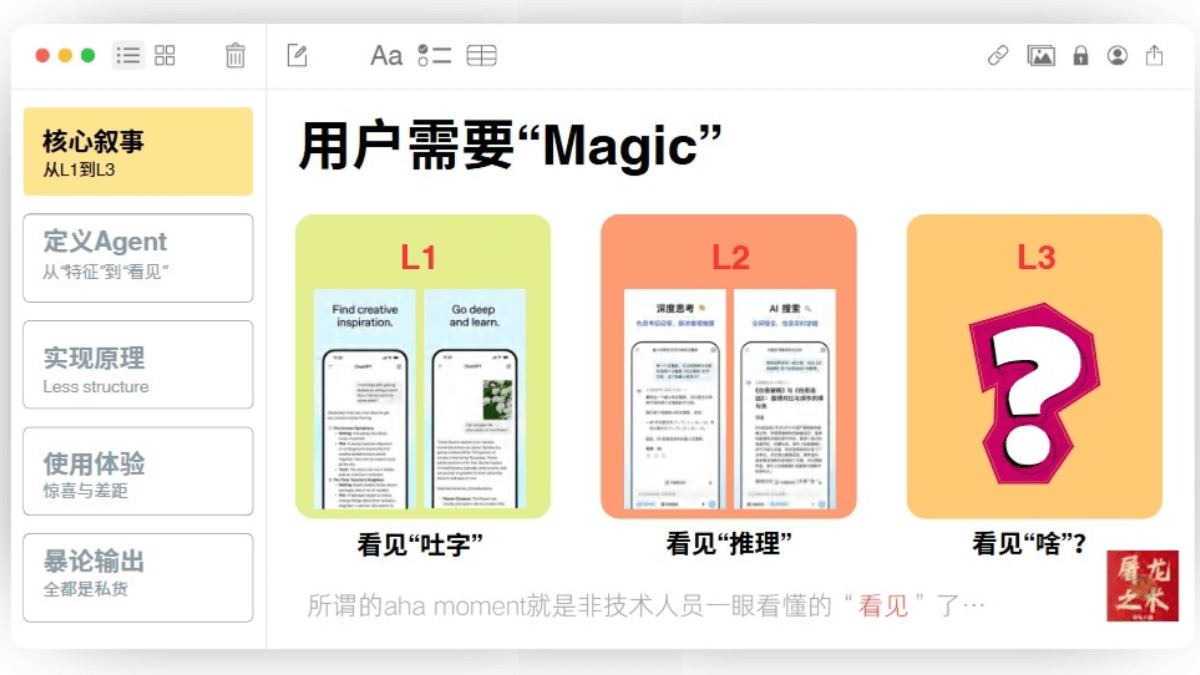
If you look at such a process, you will find that this is a purely technical route implemented at the model layer. Then what about at the user layer? I have a saying: "Users need magic," just like the Aha Moment. What is a Moment? It is that the user, as a non-technical person, sees very clearly. Seeing is very important.
Let's look back at the L1 era. When ChatGPT was released, what did users see? To put it bluntly, they saw the machine "spitting out words." It was that simple, right? Then in the L2 era, that is, with O1 or DeepSeek R1, what did users see? Users saw the model reasoning. Following the same logic, if L3 is Agents, or if that Aha Moment appears in the Agent section, then it should also be that users see something, right? Users need magic.
Changes in simplicity and complexity
Then let's talk about a keyword we mentioned earlier, "simple and complex." This is a repeated process. Looking at the L1 era, when ChatGPT had just been released, everyone said that we only needed natural language to interact with large models. But you found that very complex prompt engineering was needed, right? You needed to describe a lot, and even use strict formats to stimulate the model before it would give you a good answer. Then this is L1. By the time we got to L2, as we just said, chain of thought had appeared earlier, right? I wanted the model to think step by step, and then when R2 was truly realized, you found that when we are now using various reasoning models such as DeepSeek's RE, it feels like that prompt engineering is not really needed anymore. The model itself may understand, but the process of training R is actually a process in which everyone takes some detours.
There are many companies and many vendors using intensely competitive methods in the process. And now we are going to L3, to do Agents. You will find that many vendors are trying to define the execution of models using something called workflow. If we continue this logic, from simple to complex and then to simple and then to complex and then to simple, then shouldn't L3 also not need workflow, and also not be limited to scenarios? Because you will find that in the past several technology iterations, from the perspective of technical implementation, this kind of path dependency often leads us onto some detours, and in the end what succeeds is never the detours.
Summarize the process from L1 to L3
Let me summarize the first chapter, breaking it apart and crushing it finely, from L1 to L3. The first keyword is "general," not vertical, not limited to specific scenarios, and not setting boundaries. Of course, this will be very difficult, and the initial implementation will definitely be imperfect. General, second, let the large model do it itself, do not intervene, do not add conditions, fewer restrictions, better incentives. Of course, for companies doing related work, what tests them more is the trade-off between cost and results. Third, make the operation foolproof, especially for users, let users see, and even seeing the implementation process is very important. You cannot again and again lead users into complex areas. Then what else is needed?
Enter Chapter 2: The Definition of Agent
We enter Chapter 2. In a true sense, let us look at Agent. Actually, in the previous reasoning process from L1 to L3, some conclusions have gradually emerged. Let us still converge the boundaries a bit. This chapter is called Defining Agent, with the subtitle "From Features to Seeing." Because you will find that in the process of Chapter 1 I talked about many features, just like that elephant in the room. We can describe its legs, describe its tail, describe its ears, describe its trunk. Those are all its features. But if you want to define that elephant in a complete sense, you need to see it. Let us still look from the two most non-Agent Agent directions. These are also the two directions I talked about a lot in the previous DeepSeek PPT. One is search, and one is coding.
The Relationship Between AI Search and Agent
Let us first talk about search. At this point today, the leading AI search companies include Pop Lexi, Jasper, Kimi, and domestic vertical platforms such as Meta, Nanom, Zhihu, and others. You will find that there are also many questions directed at AI search companies. From the first day AI search companies appeared, many people would ask, do AI search companies need to have their own models? If not, then isn't that just a wrapper? Right? Then does the opportunity for AI search belong to traditional search engine companies or to startups?
After this wave of DeepSeek became popular, all US companies all integrated DeepSeek. What is everyone's difference? Can differences in information sources really bring lasting competitive advantage? Can product design create an absolute gap?
There also seem to be many open-source AI search solutions. From the perspective of engineering implementation, it feels like there is not much difficulty either. At the same time, is there meaning in searches specifically focused on vertical directions such as law, finance, and healthcare? When you hear these analyses, do you find them particularly familiar? This is AI search, right?
The Relationship Between AI Coding and Agent
From the perspective of AI Coding, the Chat products of leading large model companies could be programmed from the very first day they appeared. The driving force behind the evolution of Coding capabilities must be the evolution of the large models themselves, especially the evolution that began with Cloud 3.5. It seems that all companies engaged in AI Coding are essentially Talk based on Cloud 3.5 or 3.7. What exactly are the moats of these projects? Can the boundaries of engineering experience products create a gap?
There are also many open-source solutions for AI Coding, and all major companies will most likely build them. Will there be a brand effect for the products? Does it make sense to go vertical? If you focus on a vertical scenario in either frontend or backend, you will find that roughly the same questions are frequently asked. But is there an answer to this question? Probably not.
The Generalization of the Agent Concept and the Lack of Consensus
So this brings us back to what I said at the very beginning. I have also listed four slides from the Agent chapter in my previous DeepSeek PPT. For example, “1,000 studies, 1,000 Agent concepts”—the concept of Agent has been severely generalized. Then there are some typical definitions of Agent, including the development of the Agent industry in 2024. But you will find that in these discussions, people are mostly talking in the abstract. Because no consensus has been reached. Let me remind you: up to this slide, my PPT has not mentioned anything about Manus, nothing at all. Starting from this slide, let us look at various aspects of Manus.
Manus's Core Philosophy: Let Users See
My first description of Manus is “all work.” In order to let users see, I emphasized many times earlier that seeing is very important. I took a screenshot of a case on the official Manus website, where they analyze Tesla's stock price. In the screenshot of the webpage, you will see his entire to-do list. Then he checks various websites and obtains various charts. After the charts are done, he makes them into a webpage and gives it to you.
Essentially, at the product level, all of Manus's work is to let users see. Remember. What did I say earlier about what L1 seeing is? It is seeing the output of words. What is L2 seeing? It is seeing reasoning. What is Agent seeing? It is seeing the Agent at work—all work is to let users see. So how is letting users see achieved? Let us look at the third part, which is Manus's implementation principles, with the subtitle “Less Structure, fewer controls, fewer restrictions.”
Chapter 3: Manus's Implementation Principles
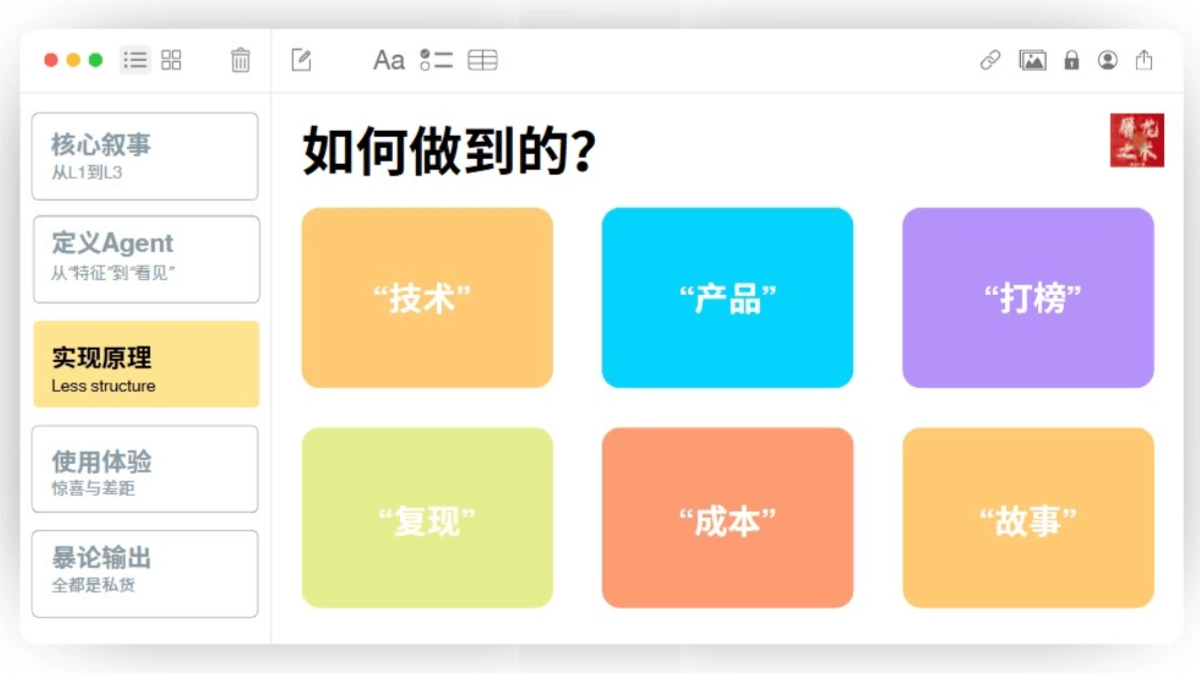
In Chapter 3, I further divided it into six subsections: technology, product, bundling, cash cost, and a short story. Let us look at them one by one. First, technology. In fact, before Manus there were already many so-called Agent products. Even in 2023, there were already some open-source or closed-source Agent products. For example, Auto GPT, Ison Pic's Computer Use, and the Auto GLGLM released by OpenAI's Deep Research. In fact, everyone's underlying logic seems to be roughly the same: the Agent breaks down tasks, executes tasks, and gives results. And because of the recent maturity of reasoning models, there seems to be no difficulty in the first step of breaking down tasks. At the same time, because of protocols like the MCP protocol launched by SOPIC, which allows large models to use various tools and APIs, after the emergence of such protocols, including the series of A0 frameworks released by OpenAI yesterday, it seems that having models use tools and build architectures is no longer a threshold.
Many people will ask, why didn't it go viral earlier? What was missing? Take Manus as an example. Before Manus was released, they actually showed their test version to some investors and very senior partners. At that time, someone asked the team a question, asking the Manus team how many workflows you wrote yourselves? Everyone can guess what the answer was. The answer is 0. Do you remember how we achieved the existing COT (Chain of Thought) at L2, and then PRM (Process Reward Mechanism) to incentivize the process, but found it was wrong, and the final approach was not to preset any restrictions or architecture, and only incentivize through results. In this logic, Manus is the same as all previous model companies reproducing O1, with no preset flow.
So conversely, why is it called "general"? If you preset a certain workflow, then you are actually not that general. You may only perform better within a few scenario boundaries you preset. So why is this? That is, or why must I mark "Less Structure" in red on this page? Because in several previous videos about OpenAI's release of O1, a core researcher at OpenAI expressed this view. Don't teach it, just give incentives, and give as few various restrictions as possible. The fewer the restrictions, the better the model performs. The same sentence also appeared in the PPT of Manus's second-day closed-door sharing session by their product partner Teacher Zhang Tao with Pick, called "Less Structure, More Intelligence", less control, better intelligence.
If we look at Manus from the perspective of product form, there is a relatively simple analogy. This analogy is also one borrowed from a KOL's form when we organized YC in tech before. That KOL is called Product Level 2, and he made a very vivid analogy. Of course, this analogy may be a very common and easy-to-think-of way after we saw Manus at this time today, which is to give AI a virtual machine. Looking back, Pop Lexi is equivalent to giving AI search companies represented by Monica, which are more plugin- and chatbot-oriented, or AI search-type companies. Perhaps what is given to AI is a browser. It may be like this, perhaps what is given to AI is an IDE editor, and today what Manus gives AI is a virtual machine.
Let me give another more realistic real-world example. This example is also one given by the Manus team at the second-day closed-door sharing session. They said that when we previously used large models, it was a bit like hiring an intern. This intern has a doctoral degree and knows a lot. But in the process of using this intern, you only gave him a pen and paper. Then what do you think he can do? You only give him a pen and paper, what can he do? But if you also give him a browser, what else can he do? If you also give him, for example, access permissions to various core internal databases, what else can he do? If you also give him some necessary training and requirements, what will he be able to accomplish?
Going all the way down this path is actually what Manus is doing. Give it a virtual machine, give it a browser, give it the necessary database access permissions, and at the same time do certain training. This is Manus. So for users, what exactly did we see? We have said countless times earlier that what users see is very important.
What exactly did users see?
So what exactly does the user see? First, they see Manus planning a task, and there will be a very detailed to-do list. Second, you will see it executing this to-do list—whether it is browsing web pages, calling APIs, programming, writing code, in all kinds of ways, you will see it doing it there. Third, you will see its summarization and conclusion. After completing all these tasks, it has to check one by one whether they are done, and turn every step of the work it did into an overall summarized thing. The last step gives you a complete delivery: a PDF file, a web page, an article, a piece of copy, or even a program, a piece of code—anyway, a complete delivery to you. So you see it planning, executing, summarizing, and finally delivering to you. Well then, at this point you will find that Manus has made it happen.
Manus team's next step: effect evaluation
For the Manus team, the thing that comes immediately right after they finish is to see how effective this is. So on the Manus official website there is a chart that is a scoring table, which is their comparison with OpenAI's DeepSeek and SOTA (State of the Art); these are also two similar Agent products. And their leaderboard is called GAI benchmark. In L1, this benchmark is also divided into three tiers: L1 is the easiest questions, L2 is a bit harder, and L3 is the hardest questions. Let's look at what this GAI is. It is actually just a question bank, right? And this question bank has roughly more than four hundred questions, letting the model solve these questions, or rather testing it with these questions, to see the accuracy rate of correct answers, and then to measure the Agent's capability.
We just said it has three levels. Beginner questions usually do not need tools, or at most need only one tool, and can achieve the result in no more than five steps. Intermediate requires executing 5 to 10 steps, and must combine the use of different tools. L3 advanced requires that AI be able to execute action sequences of arbitrary length, use an arbitrary number of tools, and have broad access to world knowledge—it sounds pretty scary, right? Let's look at specific examples, such as roughly what an L1 question looks like. Another example is: after 1977 in the 20th century, what was the name of the only winner of the Markov competition whose nationality was recorded as a country that no longer exists? Do you understand? Beginner questions, what are intermediate questions?
In the 2015 Metropolitan Museum of Art exhibition named after that year's Chinese zodiac, how many of the twelve zodiac animals have hands that can be seen? Second level, third level. In a YouTube 360-degree VR video uploaded in March 2018, the narration was voiced by the voice actor of the Gollum character in The Lord of the Rings. After the first appearance of a dinosaur in the video, what number did the narration immediately mention? If you were given an internet-connected computer, how many do you think you could answer? For questions like this, so this kind of question is extremely difficult.
Case of Manus solving a complex problem
Manus has a very interesting little example. The Manus team also talked about this at the closed-door meeting that day. At the time, they tested a GAIL3 question. What was this question? In a YouTube video link in a style similar to National Geographic, various penguins walk out of and back into the frame, and the Agent is asked to count the maximum number of penguin species that appear simultaneously in a single frame. Do you understand this question? Then what did Manus do? Manus first opened this video link, and then the first action it took was pressing K on the keyboard, then taking screenshots one by one to record which species of penguin appeared in which frame, and finally concluded that the frame with the most had three species of penguins. That was not the end. After finishing, the next action Manus went back to check was pressing 3 on the keyboard, and finally confirmed the answer.
I'm not sure whether to use YouTube, or whether to use a video website. Do you know what the YouTube shortcuts K and 3 do? K is pause; of course, some people say the spacebar also pauses — right, the spacebar also pauses, but the spacebar may cause a change in the progress bar next to it. K is purely for pausing the video. What is 3? YouTube's shortcuts 1 through 9 correspond to 10% to 90% of the video progress. This is what AI is doing.
Manus's generality and cost considerations
So besides this GAI, what else was done? Actually, not many people talked about this, because only they mentioned it at the closing meeting that day. Everyone knows that today YC should be the incubator that has invested in and researched the most projects in the incubator field at this point in time. In one of its batches, there may be one or two hundred projects, and now 70% to 80% are AI projects. If everyone is interested, you can go look at the summary I did with technology last year. Our summary was for 2024, and then in the latest batch of YC projects in 2025, there may be more than a hundred projects related to AI Agents.
The Manus team did this: they pulled out all these projects. Because your projects may be in healthcare, law, sales, finance, or even a smaller scenario like 4S dealership sales. No matter what you do, you will always have an official website, and on your official website there will always be an introduction to your business, whether it is images, video, or text descriptions. The Manus team pulled out all the descriptions of these YC25WG Agent projects and had Manus redo the secondary line. The final result is that it can roughly cover 76% of these various different Agents. Is this step called generality? Or is it somewhat like what DeepSeek did after making RE, training Llama and Qwen at the same time.
Then let's consider the next small topic: the topic of cost was also raised by the Manus team. They said the Manus team would believe that at this point in time in the Agent era, especially in the AI Agent era, the metric to measure a business should probably not be the conventional ones like DAU (daily active users), MAU (monthly active users), retention. There should be a core metric called AHPU (Agent Hours Per User), which is the time one user uses an Agent. Think about it. For example, right now we use DeepSeek, or Doubao, or Quark, or Hunyuan, or Yuanbao. How long does one conversation with it consume? 5 seconds? 10 seconds? 20 seconds? At most 30 seconds, right? But if everyone has used Manus, you will find that for a complex task handed to an Agent, even a fast one may take more than ten minutes, and a slow one may take several hours or even longer. Then think about how big the gap in computing power cost is in between. It may not be ten times or a hundred times, but even a gap of 1,000 times or 10,000 times.
At the same time, because of such a time gap, their own statistics say that on average, the cost consumed per question by DeepSeek is about 20 US dollars on average. SOTA is about ten US dollars, and they are now about two US dollars. After some open-source solutions reproduced Manus's functionality, some technical personnel went to implement it again using open-source solutions. I remember seeing some solutions where doing some tasks may also require 30 US dollars in computing power cost.
The impact of Agents on the Token economy
This massive expansion of cost triggered another problem, which became a PPT page when I was doing the 2024 summary at the beginning of the year. The content of that PPT was forwarding the estimate of the Token market by Xiu Han, the founder of Nie. At the beginning of this year, he made such an estimate.
He said that at the beginning of this year, in China, basically we don't count the applications of large model vendors themselves, but if we count third-party calls. If an application can consume tens of billions of tokens per day, then it is basically a relatively large vertical app. Tens of billions of tokens roughly means your computing power cost is 5,000 yuan per day. There are probably a few hundred such apps, consuming just a few million per day. For the whole year, this is a market of several billion to nearly 10 billion. This is the visible ceiling of the business model of third-party calls to large models at that point in time.
And importantly, everyone will say, and I also mentioned this in the previous episode of the podcast, and also mentioned under NS sum, that basically every 12 months the cost of computing power will drop by 10%, will drop tenfold. If we further consider that multimodal iteration may bring another tenfold drop, then every year it is dropping by a hundredfold. So in an extreme scenario, if a user uses AI in a video generation way for all 2 hours, that is roughly 3 billion tokens. A product with 1 million DAU per user would consume 3 quadrillion in investment, which is 300,000 times the current level, and that is the extreme state. Today you will find that people used to worry about whether the business growth of this third-party market could reach 100 if costs drop a hundredfold this year. But with the new measurement method of Agent, you will find that 100x is really too easy.
If we expand a bit further on the AHPU we mentioned earlier, this metric is more like a single-threaded metric. If there is multithreading concurrency, because if everyone uses Manus, you will find that many Manus users have Manus execute many tasks at the same time. Then if you are a provider of return-to-work, what should your allowed maximum concurrency be? If you also consider that during these parallel processes there is user intervention, which will restart some new processes, then it seems this number can be calculated infinitely. So a conclusion appears, which is that my friend, the author of Gongshi Fensi Ji, posted the weekend before last, saying that because he was in the United States communicating with many investors, he would find that no matter how we evaluate Manus, no matter what, this week may be the first week in which the Token changes brought by Agent are discussed. We have truly begun to discuss the impact of Agent on Token changes.
The origin story of Manus
Finally, let me tell a short story. The Manus team was not originally working on Manus. In fact, they first wanted to make a browser, an AI browser. And quite coincidentally, if you know this industry, you should know that there was once a very famous browser in the United States called Up, but Up has confirmed that it has stopped updating. It is also very coincidental that the day Up confirmed its notice to stop updating was also the day the Manus team decided not to make a browser.
Why would everyone find that a browser is not very suitable as an Agent? Its bearer is actually a state that is very easy to understand from the user experience layer. But today with Manus, after you finish assigning the task, you can leave. But if it is a browser, it will occupy your screen, you cannot do anything else, you cannot even disconnect from the network, you cannot do any other operations, you will interrupt it. That’s why Manus chose another path. I give him a virtual machine, he can run on the virtual machine. As long as the task is downloaded, he can go. So the browser becomes a middleman, abandoned. So in reverse, back to my title, if anyone still remembers, the title of this episode is “Manus Has No Secrets.”
Why is it said that Manus has no secrets?
Why do we say Manus has no secrets? Manus's core team has three people: CEO Xiaohong, Chief Scientist Pek, and product partner Teacher Zhang Tao. In February, when Xiaohong was interviewed on Xiaojun's podcast, she mentioned that when it comes to AI today, the existing capabilities for building Agents are still not enough. There should be a virtual machine Chatbot, there should be a computer in the cloud, and the code it writes and the things it needs to look up through the browser should all be executed on that computer. Because it is a virtual machine, it does not matter if it breaks; it can just get another one. It can even destroy that virtual machine after the current task is completed. So I myself think that architecture is called a virtual server, a browser that can write code by itself to call APIs, and can handle all kinds of complex tasks. This is what we are doing.
In October 2024, Pek open-sourced a model, which was also a reasoning model made by reproducing O1. At this point today, the execution of many tasks on Manus with reinforcement learning and less architectural control uses this open-source model. In October 2024, on the last page of Teacher Zhang Tao's February PPT about DeepSeek, he mentioned the inspiration TPC gave him in product use. He said it is necessary to provide excellent product value. In my understanding, that is the "seeing." Teacher Zhang said, if you want 95% of people to use the first application, what should an AI application look like? If you are building an Agent, obtaining observation of the external world is very important, and it can be added as well. So you can see that before Manus was released, these three core founders had already talked about all the execution technology paths, implementation principles and solutions, and product design. So there is no secret.
Announcements and user feedback about Manus
On the second day after Manus went viral, they issued an announcement. I want to reread here what Teacher Zhang Tao posted on March 6. He said, first of all, an apology to users and media friends who have been paying attention to Manus. We know that many people have not experienced Manus in the past 17 hours. For the team, it was no different from an adventure full of all kinds of accidents. We completely underestimated everyone's enthusiasm. At the beginning, the original intention was just to share the phased gains in exploring the form of Agent products. Therefore, server resources were completely prepared at the level of releasing a demo in the industry, and we never expected it would cause such a big stir. The invitation code mechanism is currently adopted because the server capacity at this moment is indeed limited, and there is no other choice.
In the last paragraph, the Manus everyone sees now is still a baby in swaddling clothes, and it is still far from the experience we want to deliver to everyone in the official version.
It is very far. There is still a lot of room for improvement in aspects such as model hallucination, friendliness of deliverables, and running speed. After I finish telling all the previous story, you can understand why Manus issued such an announcement at that point in time.
Chapter Four: Manus Usage Experience
Okay, entering our fourth part, let's try using this Manus. I found some cases from friends around me: Teacher Liu Fei, Junyu, Li Jigang, Da Congming, Lan Xixi. All of them and I are on Jike, so Boss Ma must remember to pay me.
First, let's look at Teacher Liu Fei. Teacher Liu Fei made several cases, and I picked two. The first is that he hoped to have Manus score the current AI large models, and then produced a report, which looks quite presentable. The second request was to make a summary of the podcast industry: platforms, share, and content distribution. This kind of thing, which I call the collection and organization of basic information, is relatively low-threshold for Manus today and is done relatively well.
Then let's look at this demo of the region. The WeChat public account called 'Maowo'—you can still go check his experience with Manus. Among the several cases he did, a few are fairly representative. One is what I call the ability to collect complex information, not just simple information organization. For example, one task was to have it collect the official icons of several apps. Based on the result, it may have only completed 70%. Because some icons, for example, were in the wrong format, and the model would lazily change the file extension itself. Then his second task was to have it go to the customs official website to obtain the monthly export values of some trading partners. From the execution, it looked in the wrong place; it did not really go to the customs official website to find these things. So in terms of data, it was not particularly ideal. So to summarize Manus's cases, collecting and organizing complex information may still not be that easy for Manus, or you need to give Manus clearer destination instructions. For example, in the customs case, you have to tell it, just look here.
Then Teacher Li Zhigang, as the king of prompts, right? He did two tests. One was, for example, making a PDF about ancient Chinese Peking opera. This task was completed very well. The production of the Peking opera, including its presentation as a PDF format, was very good. Then he had me use HTML plus some visualized images to explain reinforcement learning. From the perspective of making an HTML webpage to explain a concept, the task itself was completed. But you will find that those diagrams and icons still need improvement.
Then Da Congming, that is Cyber Shaanxi, gave an even harsher test and had it make a Doom. Doom is that most primitive shooting game. In the end, something came out, and this thing can run. Apart from not having the gun image of a firearm, it can move left and right and can be controlled with the keyboard. There is a map, and the fact that this thing can run is already very good. This is Da Congming's case.
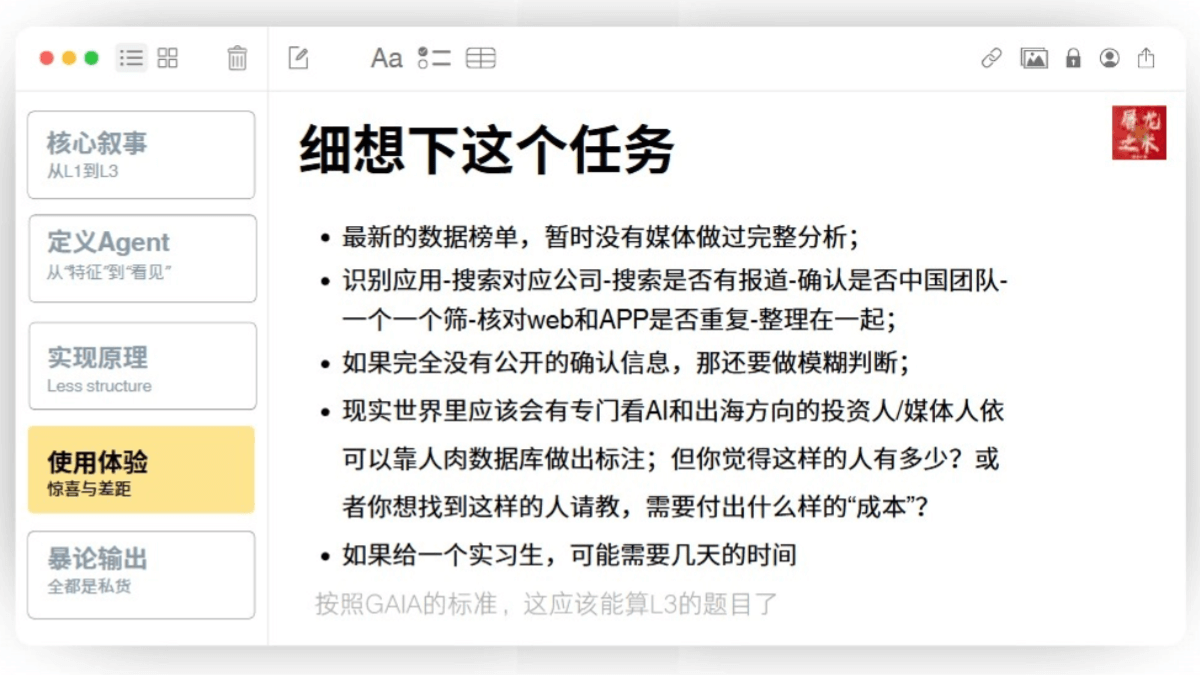
What I want to talk about a bit more is this case of mine and Teacher Lanxi. The two of us used one case, and the two of us had not communicated beforehand; we independently gave Manus such a task. What was this task? It is very interesting. That is, a few days ago H6Z released the Top 100 AI applications list that is updated every half year. It is divided into the Top 50 web AI applications and the Top 50 mobile app AI applications. Then after this list was released, we simultaneously gave Manus several tasks, which were: to see how many of the applications on this list were made by Chinese companies or Chinese teams.
Everyone think carefully about this task. First, this list had just been released, and at that point in time there was not yet professional media doing analysis. Of course today there already is, but at that point in time there was not. Think about the execution process of this task. First, Manus had to identify these application icons and names. Then it had to search the corresponding company websites or news reports, and then confirm whether they were Chinese teams, and it had to screen them one by one. At the same time, more importantly, as I just said, this list of 100 has 50 web and 50 apps. But you should know that among the 50 web and 50 apps there are duplicates. For example, ChatGPT must be both in web and in app, so the model also had to check the duplication with external apps, and finally organize the results together for me.
So if there is no fully public confirmation information, some vague judgments still need to be made. For example, the team might be in Singapore, right? So how should these teams be counted? Then in the real world, if this task is specifically looking at AI going overseas, or investors and media looking at this direction, a person can manually produce annotations like this, right? But how many people do you think there are like this? In China, or if you want to find such a person to consult, what cost would you need to pay? If you give this work to an intern, how long do you think he would need to finish this work? I think this question, according to the standard of the GIA test set we just talked about, should already count as L3.
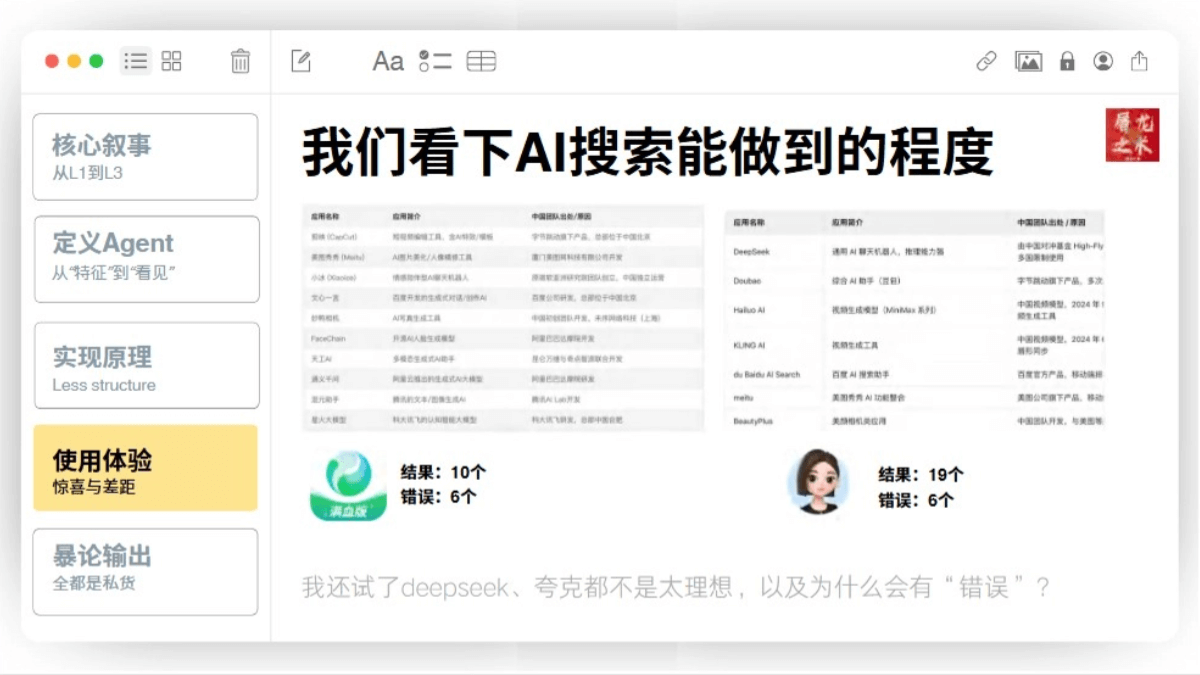
Let's look at the results. I think, well, let's not look at the results first. I similarly threw this question to the AI search tools at today's point in time. For example, I gave it to Tencent's Yuanbao, to Doubao, to DeepSeek, and to Quark. The worst performer was Tencent's Yuanbao. He told me ten, but if you look closely at the ten he gave, six out of the nine were not on that list of one hundred. He talked nonsense about six.
At the numerical level, the one that gave the most results was Shitoubao, which gave 19, but six of them were also not on that list, and some were even mismatched. DeepSeek and Quark were also not especially ideal. Everyone is also wondering why there are errors, why there is nonsense, right? Hallucination.
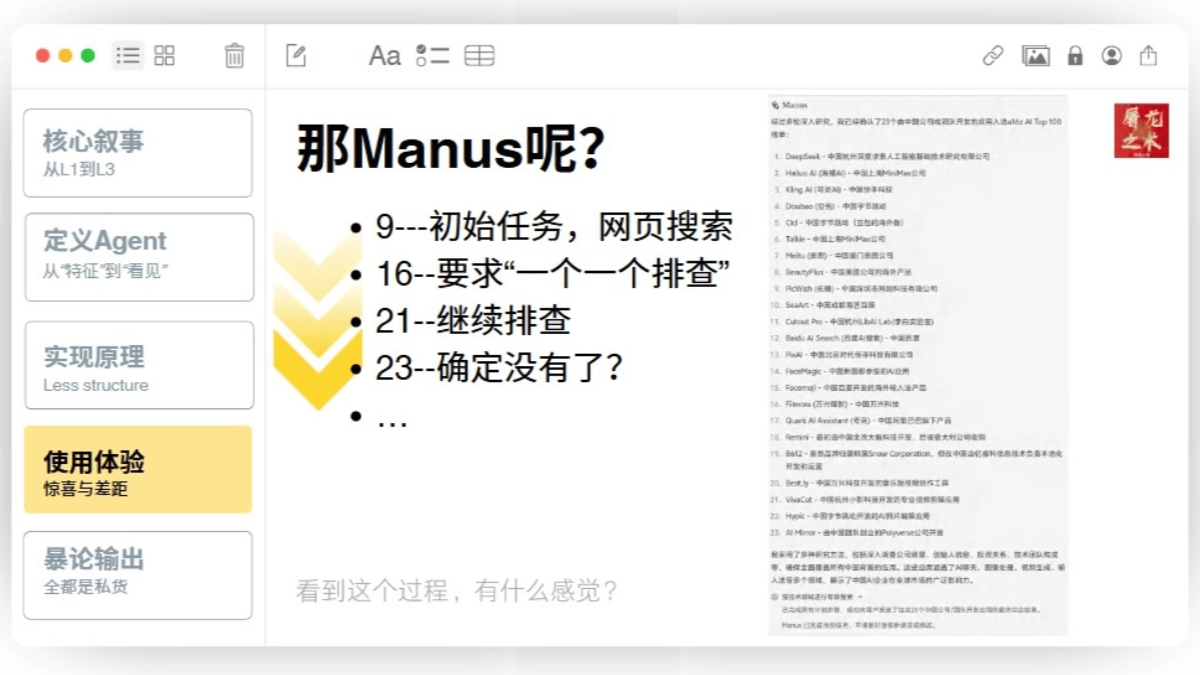
So to what extent did Manus do it? The first time I gave him the task, the result he returned to me, the number was nine. How did the nine come about? Very simple. When H6Z released this list, it was accompanied by an article. That article was about the analysis and description of this list. That list mentioned 19 Chinese apps. Manus's first return of the task to me was a lazy result. When I saw this result, I said you need to check one by one, so I gave a second prompt, that is, an addition to the second task. Then he said okay, I will check one by one. Then the result he returned to me the second time was 16. The third time I said you need to keep checking, there must be more, and he went to check again. The third time he returned 21 to me, and at that time I asked. The fourth time I said, is he sure there are no more? Then he checked again, and finally returned 23 to me.
At this point, the system prompt said the context length was limited. From the conclusion, the real number should be even more than 23, but it should already be a very close number. So what do you feel when you see this process?
Those just now all seem to be good results, right? So is there anything bad? Yes, of course. For example, in this task with Teacher Li Jigang, we both found that, for example, we both wanted him to make some diagrams, but I did not tell him where to make these diagrams, so he drew some stick-figure diagrams in a stick-figure style, very ugly, very simple, right? For example, I made something similar to military transportation to customs data. I asked him to find Spring Festival travel data, and likewise he looked in the wrong place, and the result he gave me was not good. Then for example, I asked him to make a PPT. I wanted it to have screenshots and the content of the source webpage, and he directly screenshotted a webpage. As a result, that webpage was not logged in, and a QR code was pasted on it. Then all the image positions were also wrong, and there was not much layout information. This is not an ideal result, right? But he looks like he is working seriously, it is just that he did not do it very well. Is there anything even worse?
Of course there are. The most common one I just mentioned—the context limitation is constrained by the large model itself. So you'll often find that after a task is executed many times, it will prompt you that in a particularly long context, you'd better start a new conversation. For example, a virtual machine may have some issues; the virtual machine needs to restart, and if it can't restart, it just keeps restarting. Then maybe because the user's load is too high, it needs to rest for a few minutes and try again. So it's not perfect—it doesn't even come close to perfect. It has many problems, and the success rate isn't that high.
Because take the standard L3 questions on GAIA—it only has about a 57% success rate, so more than 40% are unsuccessful, right? So how exactly should we rationally view this matter, or view Manus? I'll use the viewpoint of Yize, a self-media blogger who was also one of the earlier people to test Manus in this wave. He said it's at the level of an intern, lacking practical experience, somewhat lacking in flair, a 24-hour high-throughput working college student. The final output's level depends on the level of the Agent's core and the quality of accessible data. This is a relatively rational evaluation, I think.
Chapter Five: Controversies and Reflections on Manus
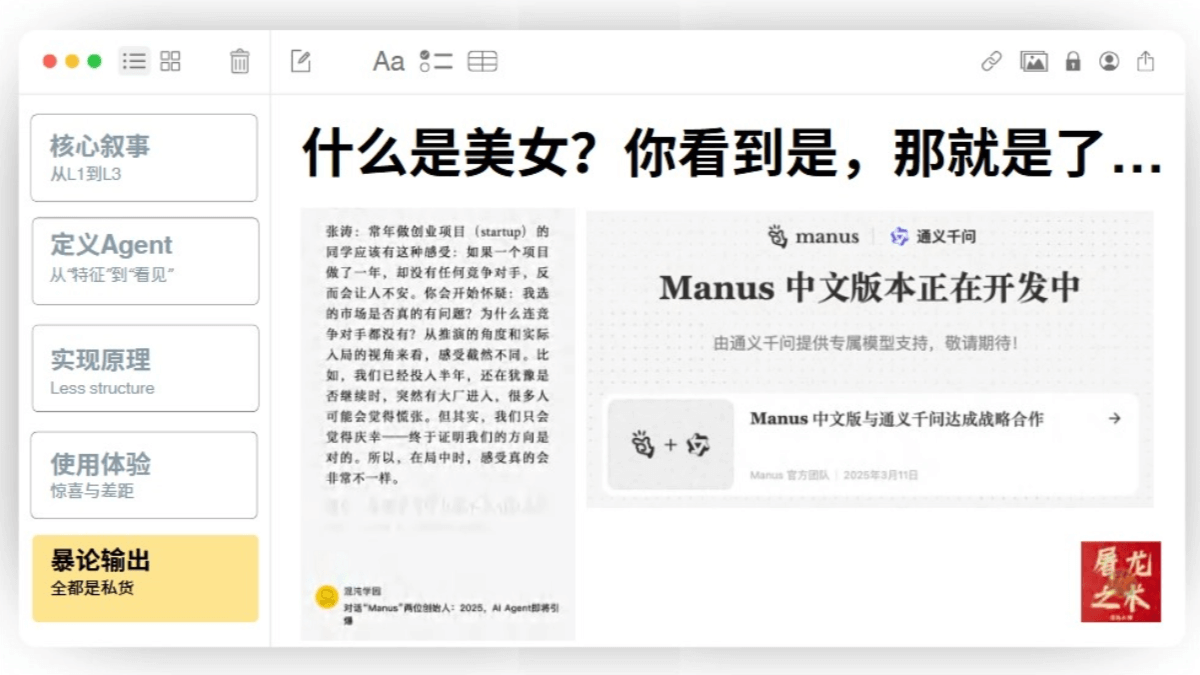
Alright, after we finish talking about usage, we come to today's final chapter, which I call "Violent Output Is All Dead Goods." I listed a few keywords. The first keyword: "Good for nothing." The second keyword: "It's just Talk." The third keyword: "Open source, reproduced in three hours." The fourth keyword: "No technological innovation." The fifth keyword: "Definitely cannon fodder." The sixth keyword: "Marketing definitely cost money." Let's go through them one by one.
"Good for nothing." Indeed, you'll find that at this point in time, for a general-purpose or so-called general Agent product, it's hard to require it to be perfect in every vertical category, especially in highly vertical scenarios. But there's a problem here—this problem, or rather this scenario, is a very interesting scenario.
On the day Manus went viral, a journalist friend called to chat with me and ask me, because he knew I had an invitation code and knew I was using it. He's someone who doesn't pay that much attention to the tech industry—more of a mainstream media journalist. So his first question was a very plain one: "Is it easy to use?" When I heard this question, my first reaction was that I first had to think about how to answer it. I paused for a moment, then I put on some armor. What was this armor? It was that I told him, I said many current test cases will have better solutions, so the answer to this question can only represent myself. But please remember what they emphasize—"
What does "general-purpose" mean? It means that, for example, if today you ask it to make a PPT, tools specifically for making PPTs will definitely have better solutions than it. But it wasn't specifically prepared for PPT, right?
This actually brings up a story from 1995 when Bill Gates went on a show to talk about the internet. The host asked, I heard that a major piece of news happened on the internet a couple of days ago—you could listen live to a baseball game. Then the other person said, "Yes." Then the host asked, "Then what is my radio for?" Then he also said, recently some car website launched where you can look up all kinds of car data. The host asked again, "Then what is my car magazine for?" I think it's the same thing.
"Isn't it just Talk?"
After "general-purpose," the second keyword is "isn't it just Talk." This has probably appeared too many times in all kinds of places over the past period. Isn't it just a wrapper? My answer is very simple: "isn't it just" is a lazy way of speaking, and even a bit arrogant.
What is "Talk Popularity"? Is it Talk Seek, Talk Yuanbao, and a bunch of applications that have integrated DeepSeek? Is it Talk? On this topic, I found the views of three fellow investors of mine on Twitter and Geek Park.
First is Yusen. Yusen is an investor in Manus, so he is an interested party. He posted this passage, saying that in January 2013 he saw a product called Pop Lexi, found it quite interesting to use, and immediately asked a guru friend who was very experienced in both search and AI. He took one look and said, "Interesting, but this has no moat. I could whip one out over the weekend." Later, he really did send me a prototype over the weekend.
In mid-2023, a good friend asked me if I was interested in investing in Pop Lexi at a valuation of a few hundred million US dollars. I was already using it often by then, but remembering what that guru had said, I politely declined. "Do wrapper applications have no moat?" Then a partner at Lightspeed also said on Twitter that technology may often not be the ultimate metric in an absolute sense. What can truly form a moat is the product, network effects, sales channels, and brand. It is these things.
Another partner who runs a USD fund was even more direct. He said, "Cognition, Glean, Process, Moveworks all seem to be wrappers, but they are already at a $50 million A2 round, and they are already valued at $1 billion." Of course, some people will also say, "You investors don't know shit." Anyway, of course, wrappers in the pure sense are still very hot. Likewise, on this issue's H6Z Top 50 APP list, six are wrappers in the pure sense. That is, the app icons also look very much like ChatGPT, and the functions they provide are also wrappers of large models in the true sense.
"Open-source reproduction in 3 hours"?
The third keyword is "open-source reproduction in 3 hours." Yes, open-source reproduction of Manus in 3 hours. Open-source solutions have followed very quickly, right? The two most famous now are: Open Manus and OW. Powerful? Very powerful. But what I want to say is that for a user, if you want to actually use these open-source solutions, you first have to download the code on GitHub, set up the environment locally, deploy a server in the cloud, call APIs of various models, and finally may even have to execute things via the command line. That sounds like too high a barrier, right?
Then I will quote a sentence from Gefei. He said, "Whipping up a demo by hand is fast, but running a product well is very hard." Those who can only guard their own mistakes have only considered the 2 in the 4-2-4 time allocation principle. What is the first one? The first is discovering demand. Before others discovered this demand and made this product, he did not whip one out. After others released it, imitating it superficially is of course easier. The second 2 is that he has only implemented the most core function. He has not seen or reproduced the large amount of detailed work others did behind the scenes, so the imitation fails badly. The third 4 is publicity and promotion. At present, he has not considered that this is long-term work.
"No technological innovation"?
The fourth keyword is "no technological innovation." So what exactly is innovation? If we look only at the AI large model industry over the past two years, it seems there is only one situation: large models are what count as underlying technology, what count as innovation. So previously there was a conclusion that said, "Before the technical capabilities of large models converge, everyone should be cautious about doing user acquisition." I just want to ask, then what is a product? Aren't we all looking forward to 2025 being a year of explosive growth for AI products, AI applications, and AI Agents?
Let me give two more realistic cases. One is also a geeky netizen who said in a reply to a Manus comment, "I asked a friend who is a finance director and usually doesn't care about AI. After looking at Manus, he said, 'This is what I expected AI to look like.'" Another good friend of mine is a university teacher. He said, "Yesterday I went back to Fudan and had dinner with the teachers, and I recommended various AI uses to them. The teachers said they already can't keep up with the times, but they really want to try. Manus is the kind that is a bit more foolproof, with no intervention ability, and it's okay if the completion quality is a bit worse." More importantly, the third one was posted by a former employee of the Manus team. He said, "From my perspective, Manus is the best manifestation of Monica company's ability to seize opportunities. But interpreting Manus that way is too shallow, because their engineering practice and accumulation in Agent workflow are real."
What I was involved in was only the first domestic launch of an Agent from September to October 2023. The to-do lists in it were all best practices after studying various companies' Agent solutions at the time. Then in March 2024 I worked on the GPT S platform. From the beginning of 2024, I had been continuously accumulating browser technology and accumulating a great deal of understanding of how to utilize browser context. I started working on search in November 2023. The ability of Agents to access information online also requires accumulation. I was not involved in that part. In July 2024, I gained growth experience in acquiring social traffic through Rost. In November 2024, in the Coding product, the understanding of the Coding capabilities of various models—indeed, each thing is a relatively thin layer. But it is also a fact that the combinatorial innovation formed by these building blocks in this window is strong enough. But that is also because they may have both the cognition and enough engineering capability to carry out an air strike in this small window.
"Marketing must have cost money"?
The fifth keyword is "marketing must have cost money." This should be a very important topic in this wave of discussion about Manus. Let me lay out the timeline:
-
At 12 noon on March 5, Teacher Zhang Tao sent me a WeChat message. He said, "We will release their new product at 10 p.m. Tomorrow, that is, at 10:30 on March 6, we will have the first round of communication with friends. If you are interested, I will send you the Tencent Meeting number."
-
On the evening of March 5, founder Xiaohong and Teacher Zhang Tao posted this video on Jike. Xiaohong posted it at 11 p.m. on March 5, and Teacher Zhang Tao posted it at 0:17 a.m. on March 6.
-
From 9:10 p.m. to 11:50 p.m. on March 5, the Cyber Zen Mind Big Clever public account reposted Manus's official video, and at 7 a.m. on March 6 posted a test, namely those demos he tested.
-
Kazike, at 6 a.m. on March 7, stayed up all night and made an experiential piece of content.
That was all the content of the first wave of dissemination, and nothing more. Up to this point in time, all the introductions we could see came from these two Jike posts and the pushes from two public accounts. Then, actually, after the video was released it blew up, and then there was the demo session the next day. So the closed-door meeting the next day had long been expected; it was not a clarification meeting. He had long wanted to introduce this thing of his to friends.
I can list a few of my good friends who were on the scene. For example, Teacher Qu Kai was there, Keji was there, Huasheng was there, Agent Universe was there, Yize was there, Uncle Huang was also there, and I was there too. There are also some friends, and all of us were there—some at the offline event in Beijing, some online. What I can guarantee is that none of us, not a single one, took money from Manus. No one. So at that point in time, Manus also issued an announcement saying, "We have never opened any paid channel for obtaining invitation codes, and we have never invested any marketing budget." As an individual who personally participated, I absolutely believe this announcement from the team.
Looking at the results, that Zeekr post from Huasheng is also very representative. He said, "Actually, it all started because the team made a pretty good product, chatted with friends in the circle, and asked everyone to test it out. The way things developed should have completely exceeded their expectations and control, and that's all." So why were people willing? I used a two-word keyword: "good karma." Also, in my previous DeepSeek PPT, I recommended that if you want to understand DeepSeek's technical implementation, watch a two-hour video. The name of that video is "The Best Tribute Is Learning." Who made that video? Teacher Zhang Tao made it. More importantly, in my blog, the previous episode about DeepSeek, "Distance and Misunderstanding," was made by me, Lili, Zhang Tao, and another teacher.
Over the past period of time, Teacher Zhang Tao, through this approach, in a sense accumulated enough good karma. We non-technical people, who do not understand technology that deeply, should thank Teacher Zhang Tao for his evangelism. So why was there such a strong first wave of organic supporters? Because of good karma.
Of course, many people may not believe it, so let me put it another way, in reverse. Because at 8 a.m. on March 6, there was already a question about Manus on Zhihu. At that time, the top-ranked answer said, "There is nothing wrong with the first AI product that self-media discovered and reviewed before technical practitioners." He said there was no traction on Hacking News or V2EX because their friends are not from the tech circle; their friends are us.
Another example: this wave of dissemination started from the Geek official account and Xiaoyuzhou. On the morning of March 6, starting from this smallest circle, it first spread to the core tech media circle, then to the financial media circle. By that day, some Party and central media outlets reported on it. If you think this marketing was designed, how much money would you need, and how many relationships would you need to pave in advance? I know many PR people from big companies listen to my podcast. If I gave you enough budget today, could you reproduce this kind of dissemination? The answer is self-evident, right?
Some people will also say there was no discussion on Twitter at all, because they did not give it to people outside first, to users on foreign Twitter, for testing, so how could there be discussion? Only later did a lot of discussion appear on Twitter. So what I want to say is that everyone must verify some things through the method of exporting for domestic sale. Is there no way and logic for independent judgment? Finally. Is the era of AI Agents really coming?
Conclusion: The arrival of the AI Agent era
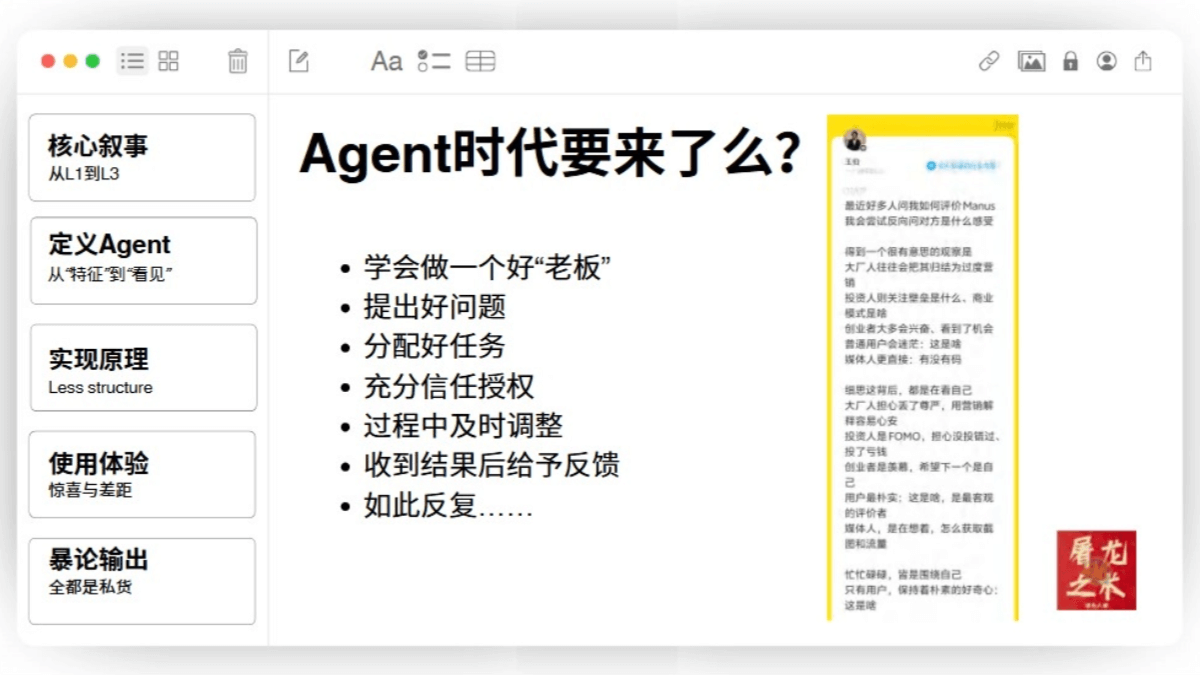
From my own experience, this is how I feel. I said I have a clearer idea of how to face an era like this. You have to learn to be a good boss, ask good questions, assign good tasks, give sufficient trust and authorization, adjust promptly during the process, and give feedback after receiving results, and repeat this over and over. This is my personal feeling as a non-technical practitioner who is interested in the industry, after all, someone who has used many AI tools. And at the same time, I want to quote Teacher Yubo's evaluation of Manus. This is what he said:
"Recently many people have asked me how I evaluate Manus, and I try to ask them in reverse what their feelings are, which gives a very interesting observation. People from big companies tend to attribute it to excessive marketing, investors focus on what the moat is and what the business model is, entrepreneurs are mostly excited and see an opportunity, users are confused about what this is, and media people are more direct, wondering whether there is a code to scrutinize. Behind all this, they are actually all looking at themselves. People from big companies worry about losing dignity, and explaining it through marketing makes them feel more at ease. Investors are formal, worrying about missing out if they do not invest and losing money if they do. Entrepreneurs are envious, hoping the next one will be them. Users are the most plain: what is this? They are the most objective evaluators. Media people are thinking about how to get images and traffic, bustling around themselves, and only users maintain a simple curiosity: what is this?"
So what do I want to say on the last page? First, in the past more than two years, in this era of AI that I call the dark forest. Whenever someone takes a step and gets the market right, it always gives you more positive feedback than you expected. This has been proven countless times. We should thank Manus for its explosive popularity in 2025. The year 2025 will become increasingly challenging. I share this encouragement with all of you. Thank you for listening to this episode of the podcast. My PPT is available on Xiaoyuzhou if needed. Thank you.
Get"Manus Has No Secrets"PDF original file, scan the code to follow and reply: 20250314