
What is LongCat-2.0-Preview
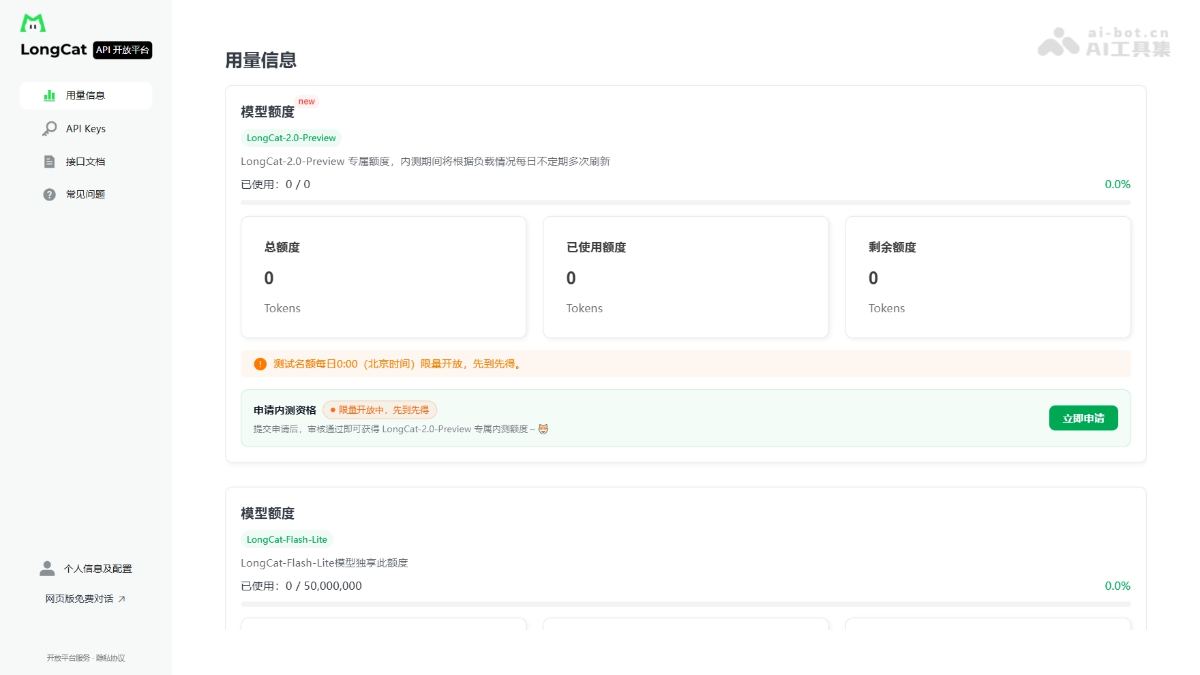
LongCat-2.0-Preview is a trillion-parameter-level large model preview version launched by Meituan. It adopts a MoE architecture, with total parameters reaching 1.6T and activated parameters at approximately 48B, supporting a 1M ultra-long context. The model completed the full training and inference process based on 50,000–60,000 domestic accelerator cards, with NVIDIA compute accounting for 0%. It is the industry's first to run a closed loop of trillion-level large model training and inference on domestic chips. The model is currently open for internal testing, providing 10 million free Tokens per day.
Main Features of LongCat-2.0-Preview
-
Ultra-long context understanding: Supports 1M token long-text input, capable of processing massive content such as entire books, large codebases, and lengthy reports.
-
Code generation and reasoning: Based on the MoE architecture, it precisely schedules expert networks and performs stably in programming, mathematical reasoning, and complex instruction-following tasks.
-
Multi-turn dialogue and semantic retrieval: Through a sparse attention mechanism, it quickly locates key information in long dialogue histories and reduces redundant computation.
-
Multimodal content understanding: Combined with Meituan's accumulation in local life scenarios, it supports in-depth parsing of complex business documents and mixed text-image content.
Technical Principles of LongCat-2.0-Preview
-
MoE (Mixture of Experts) architecture: Of the total 1.6T parameters, only 48B are activated to participate in a single forward computation. Through gated routing, the most relevant expert modules are dynamically selected, reducing inference costs.
-
N-gram Embedding: Some parameters originally located in the expert layers are moved forward to the Embedding layer, introducing phrase-level modeling capability so that high-frequency language patterns can be directly matched and hit, reducing layer-by-layer computation overhead.
-
Sparse attention and cross-layer flow-aware indexing: Introduces a lightweight sparse attention mechanism, superimposed with cross-layer semantic path indexing, avoiding full O(n²) Attention computation and ensuring controllable inference latency under a 1M context.
-
Self-developed deterministic operators: Targeting the domestic chip ecosystem, it self-develops FlashAttention backward gradients (FAG), Scatter-type operators, and GEMM modules, controlling performance loss to around 5% and ensuring the reproducibility of long-term training on a 10,000-card cluster.
-
VRAM and communication optimization: Through the V-ZB algorithm, training peak VRAM is compressed to below 60GB, and the expert parallelism (EP), tensor parallelism (TP), and pipeline parallelism (PP) strategies are restructured to adapt to the bandwidth and VRAM constraints of domestic chips.
How to use LongCat-2.0-Preview
- Apply for internal testing eligibility: VisitLongCat Open Platform, click the internal testing application entry on the official website, fill in basic information, and submit for review.
- Wait for review approval: The team will conduct eligibility review after the application is submitted, and after approval, notify the user by email or SMS to activate permissions.
- Log in to the platform to obtain quota: Log in to the LongCat platform with the approved account, and the system will automatically issue a free calling quota of 10 million Tokens per day.
- Choose an access method: Users can experience it directly through the Web chat interface, or obtain an API Key according to the documentation guidelines to integrate the model into their own applications and workflows.
- Start long-text tasks: Enter long documents, codebases, or complex instructions in the dialog box or API request, and the model will complete inference based on the 1M context window and MoE expert network and return results.
Key Information and Usage Requirements of LongCat-2.0-Preview
-
Model Name:LongCat-2.0-Preview
-
Publisher: Meituan / LongCat Team
-
Model Architecture: MoE, total parameters 1.6T, activated parameters 48B
-
Context Window: 1M (million-level) tokens
-
Computing Power Foundation: 50,000–60,000 domestic accelerator cards, full-process domestically produced for training and inference
-
Usage Stage: Invited beta testing, qualification required
-
Free Quota: 10 million tokens per day
-
Hardware Requirements: Users do not need to configure hardware on their end; call via cloud API or Web interface
Core Advantages of LongCat-2.0-Preview
-
Full-process domestic autonomous and controllable: From training to inference, it is entirely based on domestic chips, breaking away from dependence on NVIDIA's CUDA ecosystem and verifying that domestic computing power can support top-tier large model tasks.
-
Leading ultra-long text capability: The 1M context window combined with sparse attention provides significant advantages in scenarios such as long document analysis and video script understanding.
-
Controllable inference cost: The MoE architecture activates only a small number of experts, and N-gram Embedding further reduces computation, making the cost per task far lower than that of dense models.
-
Strong engineering stability: Through deterministic computation and a multi-layer fault-tolerant recovery system, it achieves long-cycle stable training on a 10,000-card-level domestic cluster, with fault localization and reproduction capabilities matching international standards.
-
Deep open-source DNA: The LongCat team has already open-sourced multiple projects such as Flash, Video, Image, and AudioDiT, and version 2.0 is highly likely to continue the open route.
Comparison of LongCat-2.0-Preview with Similar Competitors
| Comparison Dimension | LongCat-2.0-Preview | DeepSeek-V4 |
|---|---|---|
| Publisher | Meituan | DeepSeek |
| Total Parameter Count | About 1.6T | Trillion-level |
| Activated Parameters | About 48B | Specific value not disclosed |
| Context Window | 1M | 1M |
| Training Compute | 50,000–60,000 domestic cards, full process | Trained on NVIDIA GPUs, inference first launched on domestic platforms |
| Architecture Features | N-gram Embedding + sparse attention | MLA + MoE |
| Degree of Domestic Autonomy | Full-process domestic for training and inference, 0 NVIDIA content | Training depends on NVIDIA, inference can run on domestic chips |
| Open-Source Strategy | Highly likely to continue open source | Already open-sourced |
| Usage Cost | During beta testing, 10 million free tokens per day | V4 Flash 0.02 yuan/million tokens, V4 Pro 0.025 yuan/million tokens |
| Ecological Positioning | Verify the upper limit of domestic computing power, deeply cultivate local life scenarios | Extreme cost-effectiveness, serving a wide range of developers |
Application Scenarios of LongCat-2.0-Preview
-
Long document analysis and research report generation: Input million-word-level materials at once for summarization, viewpoint comparison, and in-depth research report writing.
-
Large-scale codebase understanding and development: Process the code of an entire project repository to complete cross-file dependency analysis, bug localization, and functional module generation.
-
Intelligent customer service and ticket handling: In scenarios such as e-commerce, food delivery, and travel, understand users' historical orders and complex complaint chains based on ultra-long context.
-
Multilingual translation and localization: Use long context to maintain terminology consistency and handle batch translation of entire technical manuals or film and television subtitles.
-
Education, research, and knowledge management: Assist scholars in quickly reviewing massive literature, building knowledge graphs, and answering comprehensive questions across papers.