
What is InternVideo2.5
InternVideo2.5 is a video multimodal large model jointly open-sourced by Shanghai Artificial Intelligence Laboratory, Nanjing University, and the Shenzhen Institute of Advanced Technology, Chinese Academy of Sciences. It has made significant progress in the field of video understanding, especially in longvideo processingand fine-grained spatiotemporal perception. The model can process videos up to ten thousand frames long, a 6x increase in video processing length compared with the previous generation, and can precisely locate target frames in long videos, enabling "needle-in-a-haystack"-style retrieval. It supports general video question answering and completes professional visual tasks such as object tracking and segmentation.
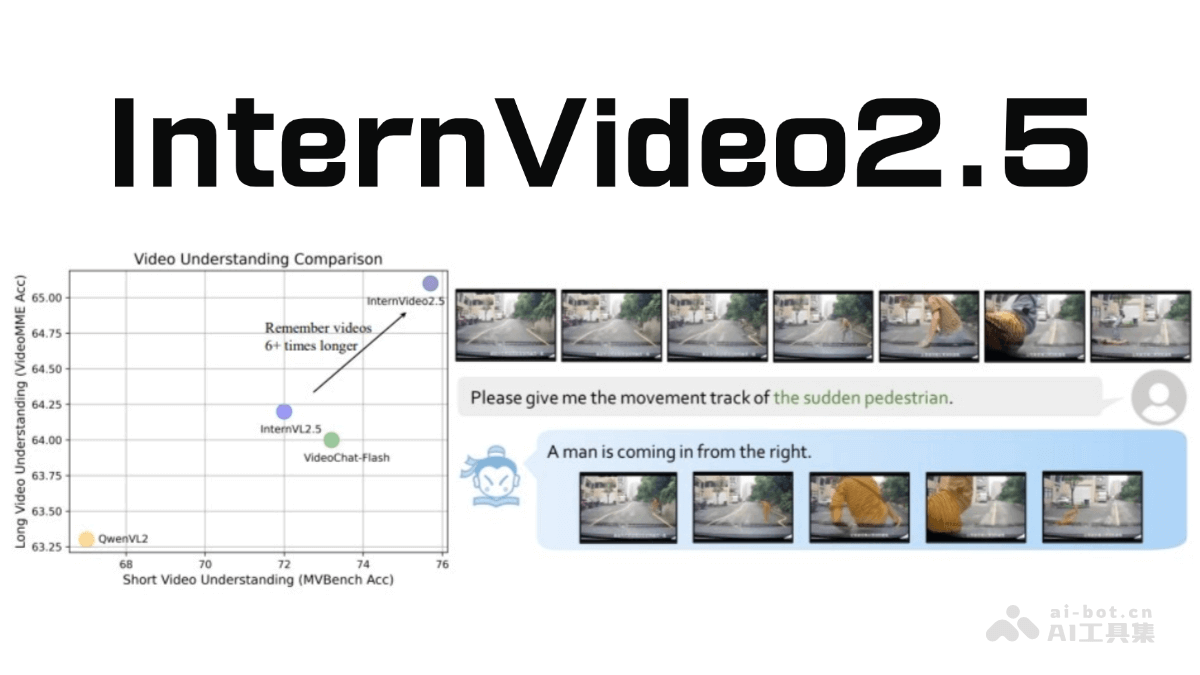
Main features of InternVideo2.5
- Ultra-long video processing: InternVideo2.5 can process videos up to ten thousand frames long, with video processing capability improved 6x over the previous generation (from 3,000 frames to 10,000 frames). It can precisely locate target frames in long videos, enabling "needle-in-a-haystack"-style retrieval, significantly improving the efficiency of video analysis.
- Fine-grained spatiotemporal perception: The model can accurately recognize and locate objects, scenes, and actions in videos, and understand subtle spatiotemporal relationships. It supports general video question answering and completes professional visual tasks such as object tracking and segmentation. It can identify the motion trajectories and state changes of objects in complex scenes, providing precise visual support for fields such as autonomous driving and surveillance security.
- Multimodal fusion: InternVideo2.5 deeply integrates visual perception and language understanding, and can generate detailed descriptions and answer user questions based on video content.
- Professional visual task support: Through task preference optimization (TPO), InternVideo2.5 can handle a variety of professional visual tasks, such as object tracking, segmentation, and temporal localization. It can dynamically adjust the model's processing strategy according to task requirements, providing optimal visual analysis capability in different scenarios.
- Efficient pretraining and optimization: InternVideo2.5 adopts a progressive multi-stage training scheme, using more than 300,000 hours of video corpus for pretraining. It improves model performance and reduces training costs.
Technical principles of InternVideo2.5
- Long-term rich context modeling (LRC): LRC enables InternVideo2.5 to process videos up to ten thousand frames long by extending the model's context length and detail perception capability. The core lies in:
- Video length-adaptive token representation: Dynamically adjust the frame sampling strategy according to the video's length and content characteristics. For example, short sequences (such as second-level videos) use dense sampling (15 frames per second), while long sequences (such as minute- or hour-level videos) use sparse sampling (1 frame per second), ensuring effective capture of motion information at different time scales.
- Hierarchical context compression (HiCo): Through a hierarchical compression mechanism, reduce spatiotemporal redundancy in video signals while retaining key information. Specifically, it includes:
- Spatiotemporal token merging: Perform token merging based on semantic similarity, rather than simple position-based pooling operations. While retaining details, it significantly reduces redundant information.
- Multimodal context integration: In the language model processing stage, further integrate the compressed visual tokens to ensure deep fusion of visual and language information.
- Task preference optimization (TPO): TPO guides model learning by transforming annotation information from fine-grained visual tasks into differentiable task preferences. This enables InternVideo2.5 to handle a variety of specialized visual tasks, such as object tracking, segmentation, temporal localization, and more. Specific implementation methods include:
- Integration of task-specific components: Add task-specific components to the model (such as temporal heads, mask adapters, etc.), and train it with task-specific datasets.
- Visual concept pretraining: Use a large number of image and video-text pairs for pretraining to further improve the model's visual understanding ability.
- Progressive multi-stage training scheme: InternVideo2.5 adopts a progressive multi-stage training scheme to gradually improve model performance:
- Basic learning stage: Perform task recognition instruction tuning and video-language alignment training.
- Fine-grained perception training stage: Enhance visual understanding ability by integrating task-specific components and visual concept pretraining.
- Comprehensive optimization stage: Perform multi-task training and instruction tuning on a mixed corpus to optimize all model components.
- Efficient distributed system: To support the training and testing of large-scale video data, InternVideo2.5 has developed a distributed system based on multimodal sequence parallelism. The system combines sequence and tensor distributed processing, as well as dynamic data packing technology, significantly improving training efficiency.
InternVideo2.5 Project Address
- Github Repository:https://github.com/OpenGVLab/InternVideo/tree/main/InternVideo2.5
- HuggingFace Model Library:https://huggingface.co/OpenGVLab/InternVideo2_5
- arXiv Technical Paper:https://arxiv.org/pdf/2501.12386
Application Scenarios of InternVideo2.5
- Video content understanding and retrieval: InternVideo2.5 can quickly find relevant video content based on users' text queries and supports complex video retrieval tasks.
- Video editing and creation: InternVideo2.5 can provide intelligent support for video editing, such as automatically generating highlight clips of videos, and generating subtitles or narration for videos. It can edit and adjust videos according to users' instructions, improving the efficiency of video creation.
- Surveillance and security: In the field of surveillance and security, InternVideo2.5 can analyze surveillance video in real time, quickly locate abnormal events, and issue alerts.
- Autonomous driving: InternVideo2.5 can process camera data from autonomous vehicles in real time and accurately identify road signs, traffic signals, and obstacles.