
What is InfinityHuman
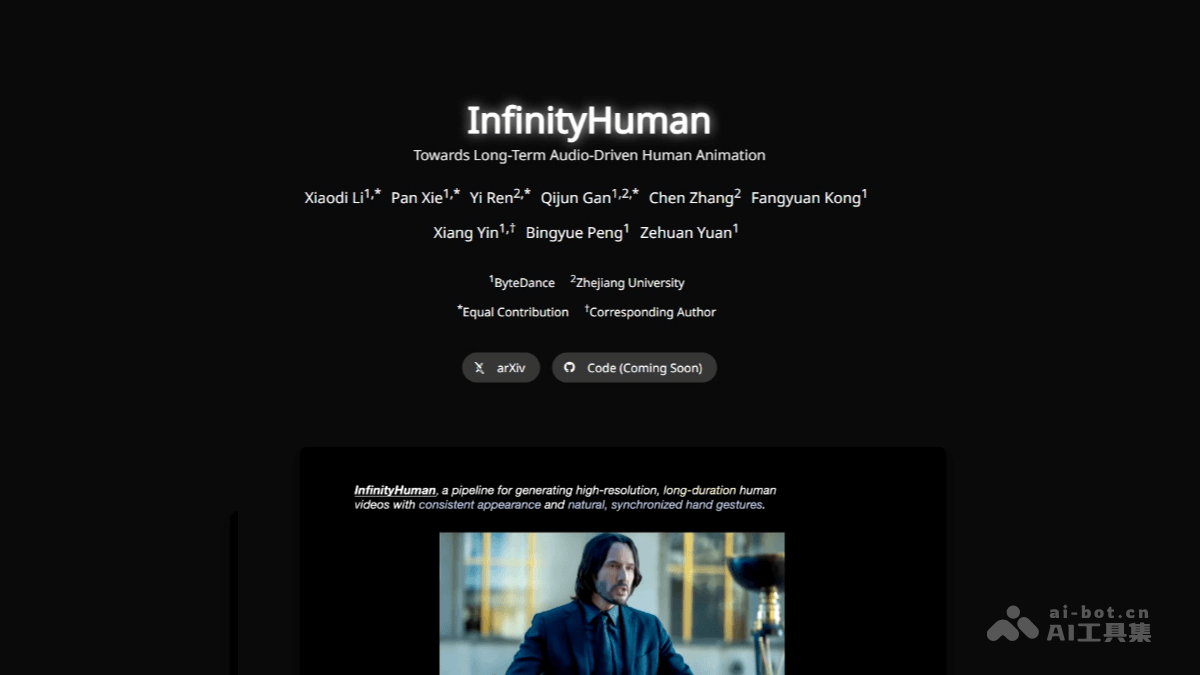
InfinityHuman is a commercial-grade long-term audio-driven humanvideo generationmodel launched by a joint team from ByteDance and Zhejiang University, opening a new chapter in the practical application of AI digital humans. The model is based on a coarse-to-fine framework, generating low-resolution motion representations and gradually producing high-resolution long-duration videos through a pose-guided refiner. The model introduces a hand-specific reward mechanism to optimize the naturalness and synchronization of hand movements, effectively addressing issues commonly found in existing methods such as identity drift, unstable frames, and stiff hand movements. In evaluations on the EMTD and HDTF datasets, InfinityHuman demonstrated outstanding performance, providing new possibilities for applications in fields such as virtual anchors, education, and customer service.
Main Features of InfinityHuman
- Long-duration video generation: Capable of generating high-resolution, long-duration human animation videos while maintaining visual consistency and stability.
- Natural hand movements: Through a hand-specific reward mechanism, generates natural, accurate hand movements synchronized with speech.
- Identity consistency: Utilizes a pose-guided refiner and the first frame as a visual anchor to reduce cumulative errors and maintain long-term consistency of the person's identity.
- Lip synchronization: Ensures that the lip movements of the person in the generated video are highly synchronized with the audio, enhancing realism.
- Diverse character styles: Supports the generation of characters in different styles to meet the needs of various application scenarios.
Technical Principles of InfinityHuman
- Low-resolution motion representation generation: The model generates low-resolution motion representations (pose) synchronized with audio, driven by audio, equivalent to creating a "draft", ensuring that the overall rhythm, movements, and mouth shapes are aligned first.
- Pose-Guided Refiner: Based on the generated low-resolution motion representations, the model uses the pose-guided refiner to gradually generate high-resolution videos.
- Pose sequence: The pose sequence serves as a stable intermediate representation, resisting temporal degradation and maintaining visual consistency.
- Visual anchor: The first frame serves as a visual anchor, continuously used as a reference to correct identity and frames, reducing cumulative errors.
- Hand reward mechanism: Through training on high-quality hand movement data, a hand-specific reward mechanism is introduced to optimize the naturalness of hand movements and their synchronization with speech.
- Multimodal condition fusion: The model fuses multiple modalities of information, including reference images, text prompts, and audio, ensuring the consistency and naturalness of the generated video in both visual and auditory aspects.
Project Address of InfinityHuman
- Project official website:https://infinityhuman.github.io/
- arXiv technical paper:https://arxiv.org/pdf/2508.20210
Application Scenarios of InfinityHuman
- Virtual anchors: Virtual anchors can naturally and fluently conduct news broadcasting, program hosting, etc., enhancing the audience's viewing experience and reducing labor costs.
- Online education: AI teachers can explain knowledge while making corresponding gestures, making the teaching process more vivid and improving students' interest and focus.
- Customer service: Digital customer service can naturally perform responsive actions during voice communication, breaking the mechanical feel of traditional customer service and improving customer satisfaction.
- Film and Television Production: In animated films, TV series, and other film and television works, quickly generate high-quality long-duration character animations, reducing the workload of manual drawing and post-production repair.
- Virtual Social Interaction: Give virtual characters in virtual reality (VR) and augmented reality (AR) natural movements and expressions, making virtual social interaction more realistic and immersive, and enhancing interactivity among users.