
What is Hy ASR 3.0 preview
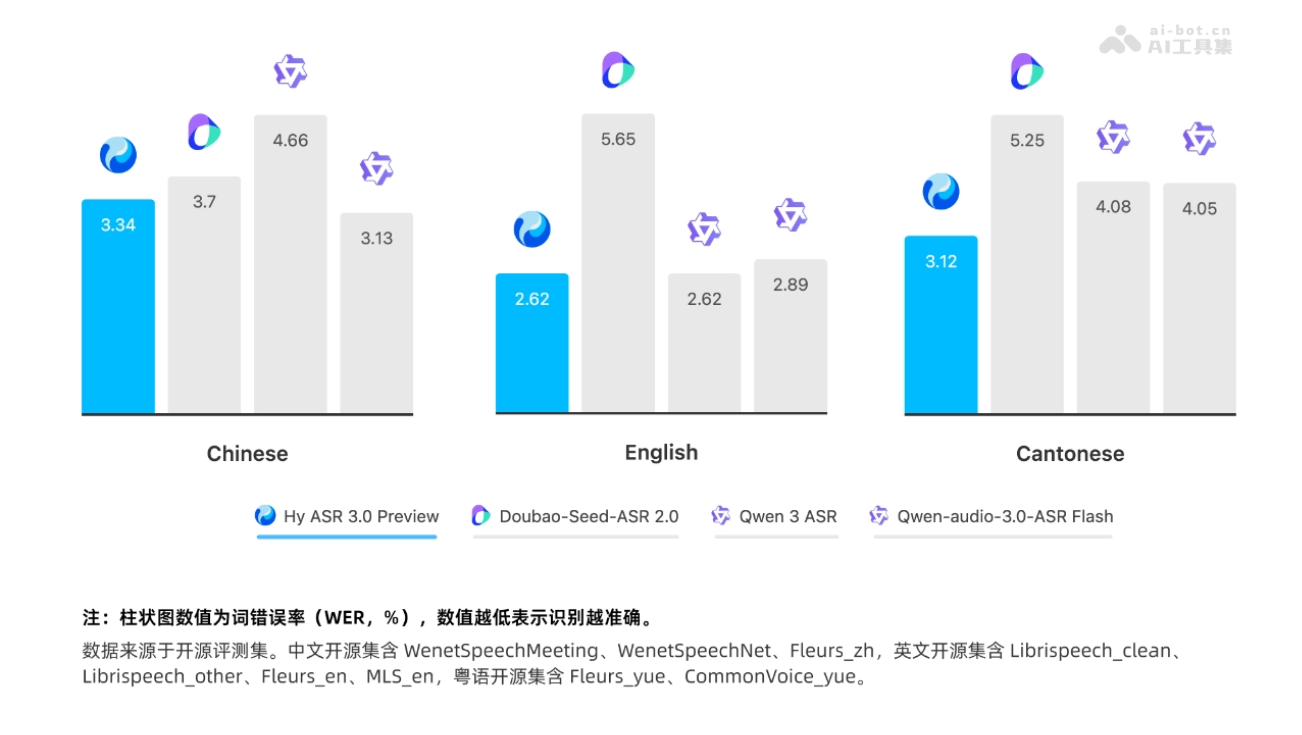
Hy ASR 3.0 preview is Tencent Hunyuan's new-generationspeech recognitionmodel, based on Hy3 large language models, integrating high-precision speech recognition with deep semantic understanding. The model supports Chinese, English, Cantonese, and 10 major dialect regions, with context-aware intelligent error correction, hotword injection, and robustness in complex scenarios such as high noise and whispering. WER on open-source evaluation sets is kept at around 3%, and it comprehensively leads competitors on self-built evaluation sets.
Main Features of Hy ASR 3.0 preview
-
General-purpose accurate recognition: Supports Mandarin Chinese, English, Cantonese, and mixed Chinese-English speech, reducing typos, omissions, and error accumulation in long audio.
-
Contextual semantic understanding: Combines Context to accurately capture the user's linguistic context, intelligently correct homophones, and eliminate semantic ambiguity.
-
Hotword injection adaptation: Supports hotword enhancement for brand names, personal names, industry terminology, etc., reducing business integration and maintenance costs.
-
Robust in complex environments: Specially optimized for acoustic scenarios such as high noise, whispering, and soft speech, maintaining stable recognition performance.
-
Broad dialect coverage: Supports 10 major dialect regions and more than 20 secondary sub-regions, including Northeastern Mandarin, Cantonese, Wu, and Southern Min.
Technical Principles of Hy ASR 3.0 preview
-
Architecture upgrade: Adopts a MoE architecture, with the base model upgraded to Hy3; a self-developed unsupervised speech Encoder trained on tens of millions of hours of speech data extracts high-quality acoustic representations.
-
Pretraining Scaling: Joint training of the Encoder and LLM, introducing tens of millions of hours of multi-source speech data (audiobooks, conversations, video/broadcast, etc.), and obtaining dialect understanding and context modeling capabilities through multi-stage capability injection.
-
Post-training enhancement: Builds a high-quality SFT Recipe covering complex audio, Any Context context, and general capabilities; through multi-stage reinforcement learning, separately optimizes general transcription accuracy, long-range contextual dependencies, and performance in complex long-tail scenarios.
How to Use Hy ASR 3.0 preview
Access via Tencent Cloud API or open TencentYuanbaopress and hold to speak to experience it for free.
Core Advantages of Hy ASR 3.0 preview
-
Semantic understanding upgrade: Based on the Hy3 large language model, integrating high-precision speech recognition with deep semantic understanding, evolving from word-by-word transcription to understanding context and one-click direct output.
-
Comprehensive evaluation leadership: WER on open-source evaluation sets is kept at around 3%, and on self-built evaluation sets it outperforms competitors in general, dialect, context, and complex acoustic scenarios.
-
Context-aware intelligent error correction: Combines Context to accurately capture linguistic context, intelligently correct homophones, eliminate semantic ambiguity, and support long-range dependency modeling.
-
Rapid hotword adaptation: Supports hotword injection for brand names, personal names, industry terminology, etc., reducing business integration and maintenance costs in professional scenarios.
-
Dialect and complex environment coverage: Supports 10 major dialect regions and more than 20 secondary sub-regions, maintaining stable performance in complex acoustic environments such as high noise and whispering.
Comparison of Hy ASR 3.0 preview with Similar Competitors
| Comparison Dimension | Hy ASR 3.0 preview (Tencent Hunyuan) | Doubao-Seed-ASR 2.0(ByteDance) |
|---|---|---|
| Base Model | Based on the Hy3 large language model, MoE architecture | Based on the Seed large language model |
| Speech Encoder | Self-developed unsupervised speech Encoder, trained on tens of millions of hours of data | Detailed architecture not disclosed |
| Core Capabilities | Contextual semantic understanding + high-precision recognition + hotword injection | High-precision general recognition |
| Chinese WER | 3.34% | 3.70% |
| English WER | 2.62% | 5.65% |
| Cantonese WER | 3.12% | 5.25% |
Application scenarios of Hy ASR 3.0 preview
-
Intelligent Customer Service: In phone and online customer service scenarios, Hy ASR 3.0 preview accurately recognizes brand names and business terminology through hotword injection, enabling real-time speech transcription and significantly improving service response efficiency.
-
Content Creation: In the production of long audio content such as podcasts, meetings, and interviews, the model combines contextual semantic understanding to intelligently eliminate ambiguity and outputs coherent, readable, high-quality text with one click, reducing post-editing costs.
-
Voice Search: It supports users in making queries using dialect speech and accurately recognizes voice commands in noisy environments, effectively lowering the input barrier for multilingual and multi-accent users.
-
Office Collaboration: In real-time meeting minutes transcription scenarios, even when faced with low-volume input such as whispers and murmurs, the model still maintains stable recognition, helping teams achieve efficient communication and information retention.
-
Intelligent Terminals: In interactions with IoT devices such as in-car navigation and smart home systems, the model is specially optimized for high-noise acoustic environments, ensuring speech recognition robustness and user experience in complex scenarios.