
What is Doubao Voice 2.0
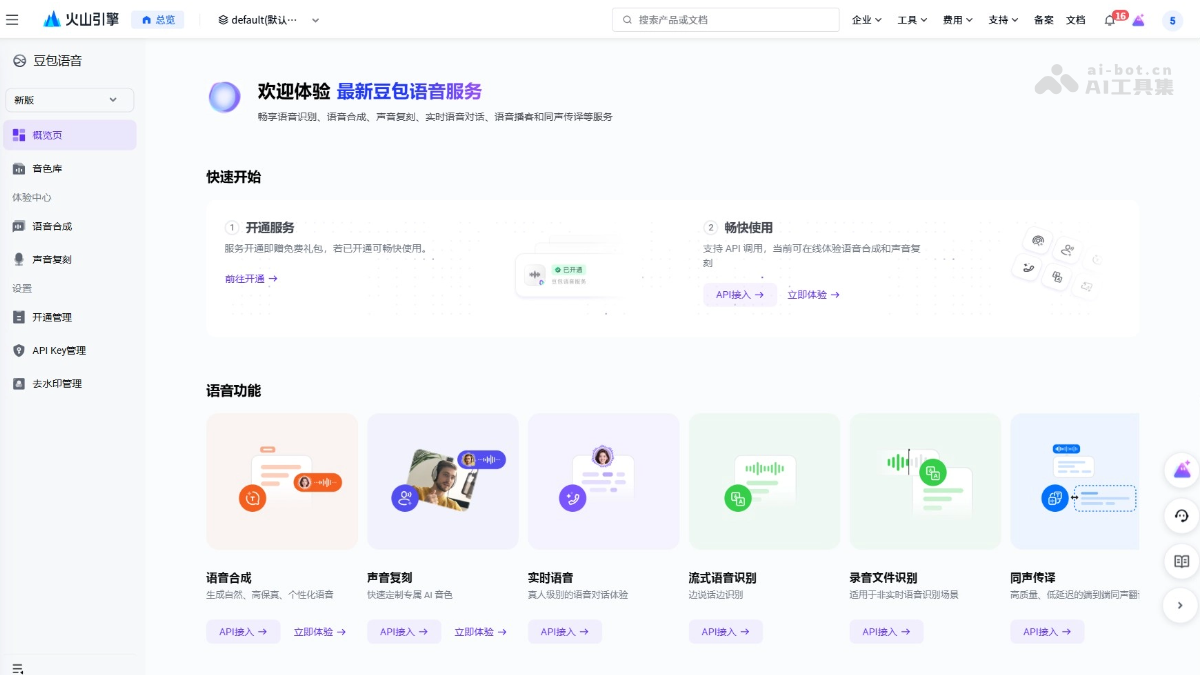
Doubao Voice 2.0 is an upgraded AI voice model launched by ByteDance, comprising three core models: Doubao Speech Recognition Model 2.0 (Doubao-Seed-ASR-2.0), DoubaoSpeech SynthesisModel 2.0 (Doubao-Seed-TTS 2.0), and Doubao Voice Cloning Model 2.0 (Doubao-Seed-ICL 2.0). The speech recognition model's reasoning capability has been enhanced, achieving precise recognition through deep contextual understanding, with the overall contextual keyword recall rate increased by 20%; it supports multimodal visual recognition, not only "understanding words" but also "understanding images," making text recognition more precise through visual information input such as single and multiple images; it supports precise recognition of 13 overseas languages including Japanese, Korean, German, and French. The speech synthesis model 2.0 supports conversational synthesis, can precisely understand semantics and emotions, and achieves reading of complex formulas with an accuracy of up to 90%. The voice cloning model 2.0 can clone a voice timbre in just 5 seconds, supports multiple languages, conveys emotions during interaction, and plays multiple roles. The two have evolved from "sounding alike" to "sounding right," bringing stronger comprehension and expressiveness to voice interaction, and are widely applied in scenarios such as education and novel dubbing. Doubao Voice 2.0 has officially launched in the Volcano Engine Voice Console Experience Center.
Main features of Doubao Voice 2.0
- Doubao Speech Recognition Model 2.0 (Doubao-Seed-ASR-2.0):
- Enhanced reasoning capability: Through the PPO reinforcement learning scheme, the model can deeply understand context and precisely recognize proper nouns, polyphonic characters, etc., without relying on historical vocabulary, with the keyword recall rate increased by 20%.
- Multimodal visual recognition: Adds image understanding capability, which can assist speech recognition by combining image content (such as single/multiple images), reducing errors on easily confused words (such as "滑鸡" and "滑稽").
- Multilingual support: While maintaining high accuracy in Chinese and English, it adds precise recognition of 13 languages including Japanese, Korean, German, and French.
- Handling complex scenarios: For scenarios such as discussions of historical figures (such as recognizing the place name "筠州") and image creation (such as distinguishing "马头" and "码头"), accuracy is improved through logical reasoning and visual analysis.
- Technical foundation: Based on the Seed mixture-of-experts large language model architecture, it continues the advantages of the 2-billion-parameter audio encoder and focuses on adaptation to dynamic interaction scenarios.
- Doubao Speech Synthesis Model 2.0 (Doubao-Seed-TTS 2.0):
-
Conversational synthesis: Supports precise control of speech emotion, tone, and intonation through bracket instructions, voice instructions, and contextual information, understands the context of multi-turn dialogue, and achieves natural and fluent emotional expression.
-
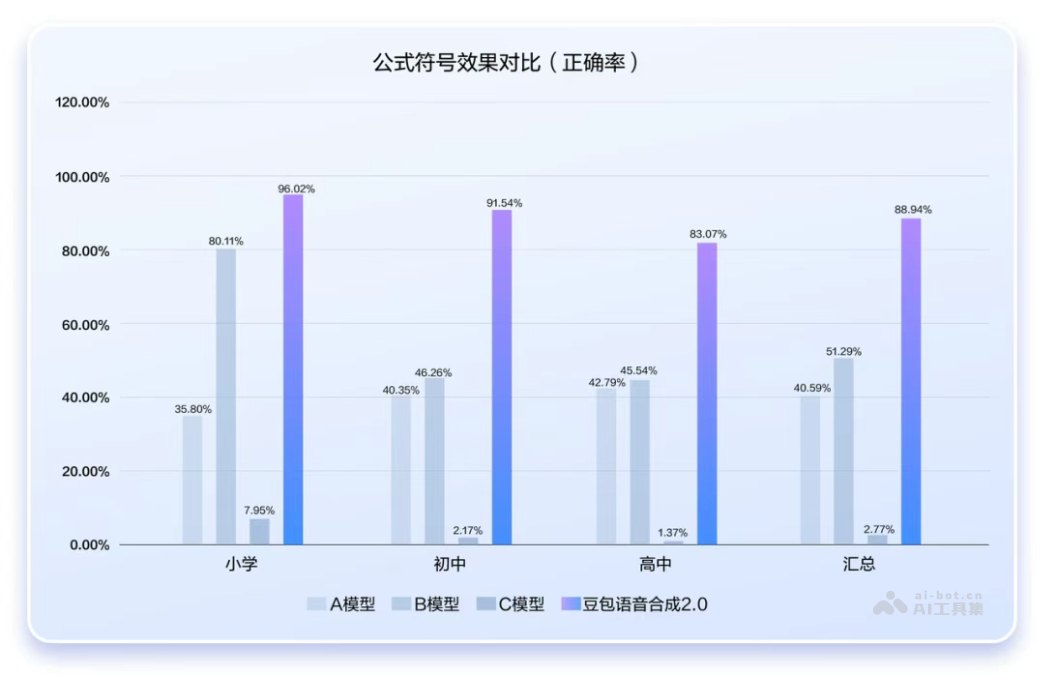
Reading of complex formulas: Specially optimized for educational scenarios, covering formulas across all subjects from elementary school to high school, with an average accuracy of up to 90%, solving the difficulty of reading aloud in subject assistance.
-
Multi-scenario applications: Widely applied in scenarios such as educational assistance, emotional companionship, and content dubbing, making speech more interactive and anthropomorphic.
-
- Doubao Voice Cloning Model 2.0 (Doubao-Seed-ICL 2.0):
-
Rapid voice timbre cloning: Clones the user's voice timbre in just 5 seconds, supports multiple languages such as Chinese, English, Japanese, Spanish, and Portuguese, and easily achieves "voice similarity."
-
Emotional expressiveness: The replicated voice has stronger emotional expressiveness, can convey emotions that fit the context during interaction, and can voice multiple roles.
-
Multi-scenario applications: Suitable for scenarios such as voice interaction, novel dubbing, and podcast dialogue, bringing users a vivid and natural voice experience.
-
Performance of Doubao Voice 2.0
Through specialized optimization, Doubao Voice 2.0 overcomes the challenge of reading complex formula symbols in educational tutoring, raising the average accuracy to 90%, significantly higher than the 50% of traditional models, providing a rigorous and efficient voice interaction experience for educational scenarios.
Project address of Doubao Voice 2.0
- Project official website:https://console.volcengine.com/speech/
Application scenarios of Doubao Voice 2.0
- Educational tutoring: Supports all-subject education from elementary school to high school, with an average accuracy of up to 90%, providing precise voice assistance tools for students and teachers.
- Emotional companionship: Accurately expresses emotions according to context and instructions, making voice interaction more realistic and natural, suitable for emotional companionship scenarios.
- Content dubbing: Adjusts tone and intonation according to text content, widely used in content dubbing for videos, advertisements, audiobooks, and more.
- Novel performance: Conveys the emotions of different characters according to context, suitable for novel dubbing, making stories more vivid.
- Podcast dialogue: The model can understand the context of multi-turn dialogues and supports natural and fluent voice interaction, suitable for dialogue and interaction segments in podcast programs.