
What is HunyuanImage 3.0
HunyuanImage 3.0 is a native multimodalimage generationmodel released and open-sourced by Tencent. With a parameter scale of 80B, it is currently the best-performing and largest open-source image generation model in evaluations. It possesses native multimodal capabilities and can simultaneously process input and output across multiple modalities such as text, images, video, and audio without the need to combine multiple models. HunyuanImage 3.0 has powerful semantic understanding and reasoning capabilities, can parse complex semantics at the thousand-character level and generate long-text content, and can generate realistic, high-quality images. HunyuanImage 3.0 supports real-time image generation, allowing users to generate images while typing, with millisecond-level response and ultra-realistic image quality. It supports complex text generation, such as posters and comics, as well as image generation in various styles, such as object photography and popular science illustrations. Users can experience the model through theTencent Hunyuanofficial website.
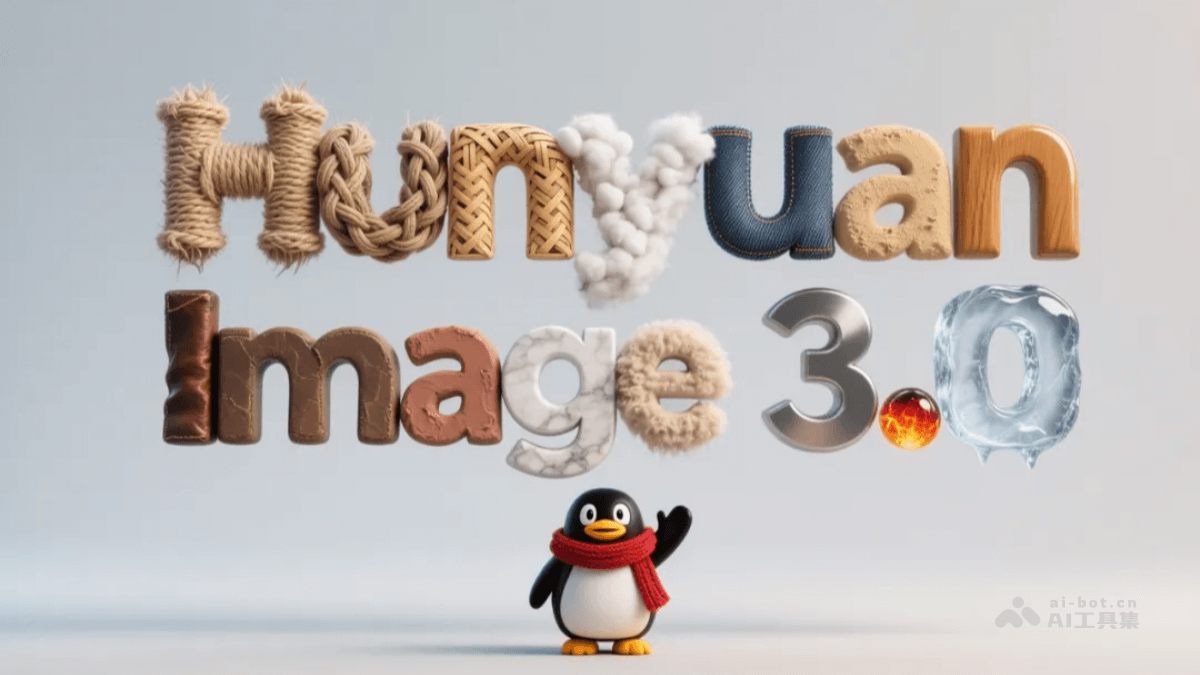
Main Features of HunyuanImage 3.0
-
Multimodal Fusion: Native support for input and output across multiple modalities such as text, images, video, and audio, without the need to combine multiple models.
-
Real-Time Image Generation: It has real-time image generation capabilities, allowing users to generate images while typing, with millisecond-level response and ultra-realistic image quality.
-
Complex Text Generation: It can generate images containing complex text, such as posters and comics, meeting diverse content creation needs.
-
Multi-Style Image Generation: It supports image generation in multiple styles, including object photography, popular science illustrations, and artistic styles, adapting to different application scenarios.
-
Semantic Understanding and Reasoning: It has powerful semantic understanding and reasoning capabilities, can parse complex semantics at the thousand-character level, and generate long-text content.
-
High-Quality Image Generation: The generated images are realistic and high-quality, and the overall image generation performance is industry-leading.
-
Open Source and Free to Use: The model weights and accelerated versions have been released in the open-source community, and users can directly download and use them for free.
-
Broad Application Scenarios: It can be applied in many fields such as content creation, popular science education, advertising design, and social media, greatly improving creation efficiency.
Technical Principles of HunyuanImage 3.0
-
Large Parameter Scale: HunyuanImage 3.0 has a parameter scale of 80B, which gives it powerful representation and generation capabilities, enabling it to handle more complex semantics and generate more detailed images.
-
Native Multimodal Architecture: The model processes multimodal data such as text, images, video, and audio through a unified architecture, avoiding the complexity and performance loss caused by combining multiple models and enhancing fusion and collaboration between modalities.
-
Knowledge-Driven Semantic Understanding: During training, the model incorporates a large amount of knowledge data and can perform reasoning and semantic parsing, thereby better understanding complex prompts and generating images that better match user intent.
-
Mixed Training Data: It uses multimodal data on the order of 5 billion image-text pairs, video frames, and more for mixed training. This rich and diverse data enables the model to learn associations between different modalities and improve generation performance.
-
Real-Time Generation Technology: Through optimized algorithms and architecture design, millisecond-level real-time image generation is achieved, allowing users to see the generated results instantly, greatly improving interactivity and creative efficiency.
-
Multi-task learning: During training, the model integrates multiple tasks, such as image generation, text generation, and image-text alignment, which enables the model to perform well on different tasks and have stronger generalization ability.
Project address of Hunyuan Image 3.0
- Project official website:Tencent Hunyuan
- Github repository:https://github.com/Tencent-Hunyuan/HunyuanImage-3.0
- Hugging Face model library:https://huggingface.co/tencent/HunyuanImage-3.0
How to use Hunyuan Image 3.0
-
Visit the official website to experience it: Users can visitTencent Hunyuanofficial website for an online experience, directly enter prompts and generate images.
-
Download the open-source model: The model weights and accelerated versions have been released in the Github repository and HuggingFace model library, and users can download and deploy them locally.
Application scenarios of Hunyuan Image 3.0
-
Content creation: Help illustrators, designers, and others quickly generate high-quality images and improve creative efficiency.
-
Science popularization education: Generate visual content such as popular science comics to assist teaching and knowledge dissemination.
-
Advertising design: Create advertising posters with a high-quality photographic feel to attract users' attention.
-
Social media: Generate attractive cover images and memes for bloggers and content creators.
-
Product design: Quickly generate product concept images and design sketches to accelerate the product development process.
-
Game development: Generate image resources such as characters, scenes, and props in games.