
What Is Higgs Avatar v1
Higgs Avatar v1 is areal-time AI digital humanmodel for voice agents launched by BosonAI. The model requires only a single static photo to generate a real-time interactive digital human withlip sync, facial expressions, and head movements. The model renders a single frame in only 16 milliseconds, a single H100 can handle 8 concurrent conversations, and it works end-to-end with the self-developed Higgs Audio voice model, making it suitable for scenarios such as customer service, sales, and training.
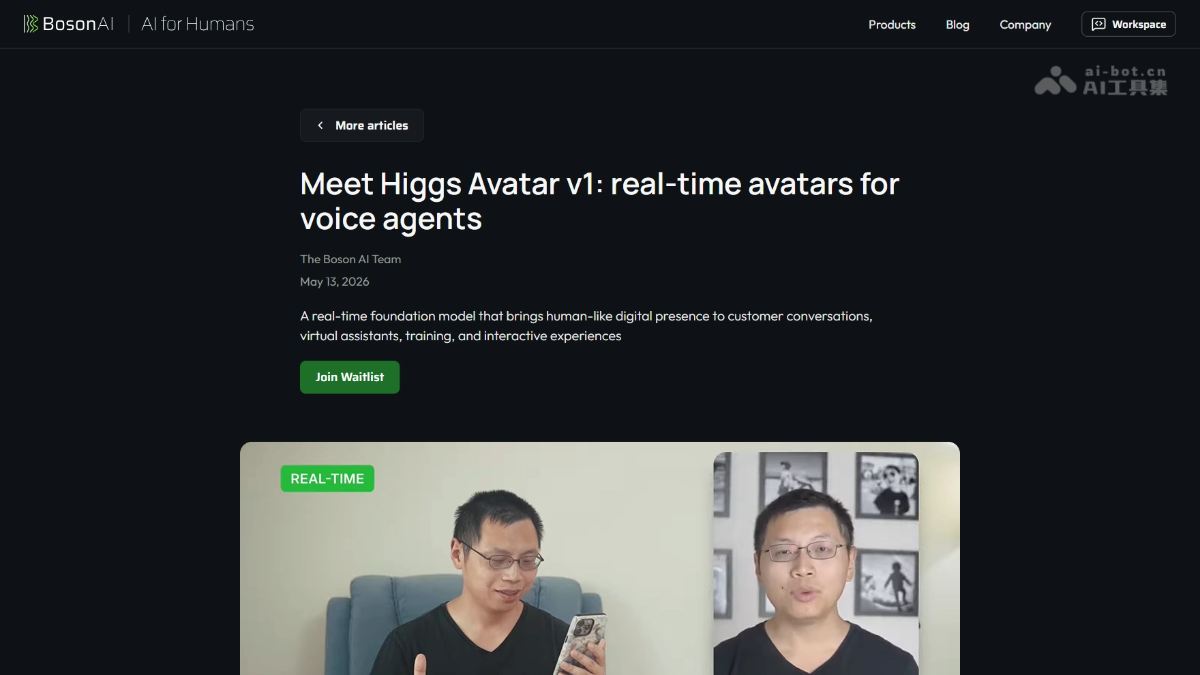
Main Features of Higgs Avatar v1
- Single-Image Real-Time Digital Human Generation: Only a single static photo needs to be uploaded to generate a real-time conversational digital human with a realistic face, without 3D modeling or motion capture equipment.
- Voice-Driven Expression Synchronization: The digital human's lip sync, facial expressions, and head movements follow changes in voice content in real time, achieving a complete interactive loop of listening, speaking, and responding.
- Frame-by-Frame Real-Time Rendering: During a conversation, every frame is generated by AI in real time, with no pre-rendered loops or preset animation scripts, and expressions and movements are completely improvised.
- Multi-Channel Concurrent Conversation Support: A single H100 GPU can simultaneously carry 8 independent real-time conversations, meeting enterprise-grade high-concurrency customer service and consultation scenarios.
- End-to-End Full-Stack Collaboration: Deeply collaborates with the self-developed Higgs Audio voice model, integrating everything from voice understanding to facial rendering, avoiding delays from stitching together multiple components.
Technical Principles of Higgs Avatar v1
-
Pretrained Video Generation Model: Built on a large-scale video pretrained model, enabling the model to generate frame by frame, with each frame output in sync with the audio stream.
-
Streaming Frame-by-Frame Inference Architecture: Adapts a traditional video generation model into a streaming inference mode, with each frame taking about 16 milliseconds to generate, far below the 62.5-millisecond real-time conversation threshold.
-
Speech-Vision Joint Alignment: Co-designed with the Higgs Audio model, establishing mappings between speech features and facial expressions, lip shapes, and head poses during the training stage.
-
Single-Image Identity Encoding: Uses an image encoder to extract identity features from a single photo, maintaining consistency and stability of the person's face during frame-by-frame generation.
-
Production-Grade Inference Optimization: Performs inference acceleration and memory optimization for H100 GPUs, achieving 8 concurrent channels on a single card and reducing the compute cost per conversation.
How to Use Higgs Avatar v1
- Apply for Beta Access: Visit the Higgs Avatar v1 official website https://www.boson.ai/blog/higgs-avatar-v1,点击「Join Waitlist] to fill in information and join the waiting list.
- Wait for Review and Activation: Wait for official review approval and obtain trial access to Private Preview or an enterprise contact entry point.
- Upload an Avatar Photo: Prepare a clear frontal static photo as the base image input for the digital human.
- Connect Voice Conversation: Connect to the Higgs Audio voice model through Boson Presence or API to start real-time voice + video conversation.
- Deploy to Business Scenarios: According to needs such as customer service, sales, or training, integrate the Avatar into existing workflows and launch it in operation.
Core Advantages of Higgs Avatar v1
-
End-to-End Self-Developed: Speech and vision models are co-designed from the training stage, avoiding latency, interruptions, and facial expression mismatches caused by API stitching.
-
Ultra-Low Latency: Supports 16 ms single-frame generation speed, ensuring zero time difference synchronization between digital human facial expressions and speech.
-
High Compute Cost-Effectiveness: A single H100 simultaneously supports 8 channels of real-time conversation, with controllable per-conversation cost, meeting production-grade deployment needs.
-
Zero Motion Capture Threshold: No 3D modeling or motion capture required; a single photo can generate a dynamic interactive avatar.
Comparison of Higgs Avatar v1 with Similar Competitors
| Comparison Dimension | Higgs Avatar v1 (BosonAI) | Live Avatar (Alibaba Jointly with Universities) |
|---|---|---|
| Developer | BosonAI (founded by Li Mu) | Alibaba jointly with multiple universities |
| Open-Source Status | Closed-source enterprise-grade foundation model | Open source (GitHub / HuggingFace) |
| Technical Architecture | Self-developed end-to-end foundation model, natively coordinated with Higgs Audio | 14-billion-parameter diffusion model, DMD distilled into 4-step streaming diffusion |
| Input Method | Single static photo | Microphone + camera real-time audio-video driven |
| Generation Frame Rate | 16 ms per frame (far below the 62.5 ms real-time threshold) | 20 FPS real-time streaming generation |
| Duration Stability | Focuses on real-time conversation, does not emphasize ultra-long durations | Supports continuous generation of over 10,000 seconds, preventing identity drift and color distortion |
| Speech Coordination | Deep end-to-end coordination with the self-developed Higgs Audio speech model | Supports audio-driven lip synchronization, not bound to a dedicated speech foundation model |
| Core Optimization | End-to-end latency and emotion alignment | Rolling RoPE, adaptive attention pooling, and historical interference mechanisms ensure long-term consistency |
| Deployment Method | API / enterprise customization / private deployment | Open-source model, supports self-deployment and secondary development |
| Concurrency Capability | A single H100 supports 8 concurrent real-time conversations | Supports time-step forced pipeline parallelism, linear acceleration scaling |
Application Scenarios of Higgs Avatar v1
-
Intelligent Customer Service: Provides 7×24-hour voice and video customer service with a realistic face for e-commerce, finance, and other industries, enhancing user trust.
-
Sales Advisor: Serves as a virtual salesperson in insurance, real estate, and other fields, enhancing persuasiveness and conversion efficiency through face-to-face interaction.
-
Corporate Training: As an AI coach or instructor, provides employees with immersive one-on-one skills training and business guidance.
-
Medical Consultation: Provides visual preliminary consultation and health advisory services in telemedicine scenarios, alleviating patient anxiety.
-
Interactive Entertainment: Used for virtual interviews, AI role-playing, and immersive interactive content creation, enhancing audience engagement.