
What is GLM-5.1-highspeed
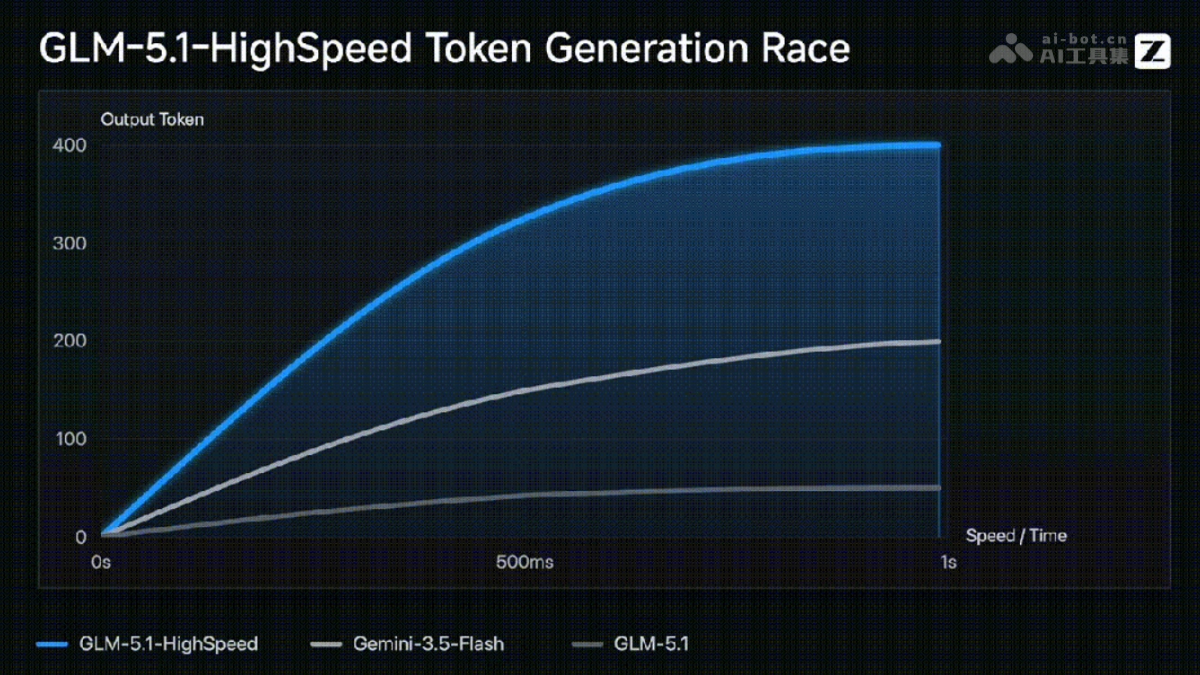
GLM-5.1-HighSpeed is a flagship high-speed large model API launched by Zhipu AI, fully retainingGLM-5.1On the basis of comprehensive capabilities, it achieves an output speed of 400 tokens/s through the TileRT high-performance inference engine, setting a new global upper limit for large model API speed. The model supports a 200K context window and 128K maximum output, and is aimed at low-latency scenarios such as Coding Agent, real-time interaction, and business decision-making. It is currently only available toBigModelselected enterprise customers on the open platform.
Main features of GLM-5.1-highspeed
-
Ultra-fast text generation: The model output speed reaches 400 tokens/s, and it can complete a generation task of about 400 tokens in 1 second.
-
Full flagship capabilities: Fully retains the Coding, reasoning, and general task processing capabilities of GLM-5.1, with no need to sacrifice quality for speed.
-
MCP tool calling: Supports flexible calling of external MCP tools and data sources, expanding the boundaries of model application scenarios.
-
Deep thinking mode: Supports enabling thinking mode, outputting the reasoning process while responding at ultra-high speed.
-
Streaming real-time output: Supports SSE streaming transmission, enabling a real-time interactive experience of returning results while generating.
Technical principles of GLM-5.1-highspeed
-
TileRT persistent engine: At compile time, the computation graph is statically orchestrated into a persistent Engine Kernel resident on the GPU, requiring only one launch to complete inference.
-
Register-level direct data transfer: Intermediate operator results are passed directly through Registers, Shared Memory, and L2 Cache, avoiding the memory access overhead of writing back to Global Memory.
-
Tile-level microtask scheduling: Decomposes computation, asynchronous IO, and communication into Tile-level microtasks, eliminating host dynamic scheduling and cross-operator synchronization latency.
-
Heterogeneous multi-card collaboration: In multi-card scenarios, different GPU ranks are specialized into different workers according to computing density and data dependencies, improving parallel efficiency.
-
System-level full-stack optimization: From inference engine path rewriting, dynamic batching, and KV cache scheduling, to collaborative optimization of cluster networking and load balancing.
How to use GLM-5.1-highspeed
-
Obtain permission: Contact ZhipuBigModelopen platform to apply for enterprise customer qualification and an API Key.
-
Install SDK: Install the zai-sdk or zhipuai Python SDK via pip, or import the Java Maven dependency.
-
Initialize client: Use the API Key to create a ZhipuAiClient or ZhipuAI client instance.
-
Configure request parameters: Set the model to glm-5.1-highspeed, and enable thinking mode and streaming output as needed.
-
Send request call: Send a message list through the chat.completions.create interface and obtain the model's returned result.
Core advantages of GLM-5.1-highspeed
-
Both speed and quality: Breaks the industry convention that high speed must mean lightweight, achieving for the first time among domestic large models flagship capabilities paired with ultra-fast response.
-
Production-grade stability: 400 TPS is not a peak value but a stable, usable production-grade capability, ensuring sustained high performance through full-stack optimization.
-
Real-time collaborative experience: Instant question-and-answer response speed makes the model a partner capable of real-time collaboration, supporting high-frequency human-machine interaction and continuous Agent execution.
-
Long context support: A 200K context window and 128K maximum output meet the needs of large-scale engineering refactoring and long document processing.
GLM-5.1-highspeed project address
- Project official website:https://docs.bigmodel.cn/cn/guide/models/text/glm-5.1-highspeed
Comparison of GLM-5.1-highspeed with similar competing products
| Dimension | GLM-5.1-HighSpeed | Gemini-3.5-Flash |
|---|---|---|
| Output speed | 400 tokens/s | Approximately 200 tokens/s |
| Model positioning | High-speed flagship (full flagship capabilities) | Lightweight and high-speed (sacrificing some capabilities) |
| Context window | 200K | 1M |
| Maximum output | 128K | 8K |
| Deep thinking | Supports thinking mode | Supports |
| Tool calling | Supports MCP | Supports Function Calling |
| Open scope | Targeted access for some enterprise customers | Publicly available |
Application scenarios of GLM-5.1-highspeed
-
AI programming: For Coding Agents and large-scale engineering refactoring, enabling real-time generation and collaborative modification of code, interfaces, and call chains.
-
Real-time interaction: Supports instant modeling in game scenarios, real-time UI construction, and dynamic content feedback, changing system state immediately with user input.
-
Business decision-making: Suitable for real-time data analysis, operational Q&A, and parallel inference by multiple Agents, quickly completing strategy generation and solution comparison.
-
Real-time voice: In voice assistant and real-time customer service scenarios, it quickly completes the closed loop of understanding and generation, delivering a natural and smooth interaction experience.