
What is Fun-ASR1.5
Fun-ASR1.5 is a new-generation version of the end-to-end speech recognition large model launched by the Alibaba Tongyi team. A single model supports high-precision recognition of 30 languages, covering the seven major Chinese dialect systems and more than 20 regional accents, with specialized optimization for the recognition of recitations of classical poetry. The model is based on a MoE architecture to achieve automatic language switching without the need for preset labels. Fun-ASR1.5 enables post-processing to support intelligent punctuation prediction and text normalization, taking speech transcription from usable to easy to use.
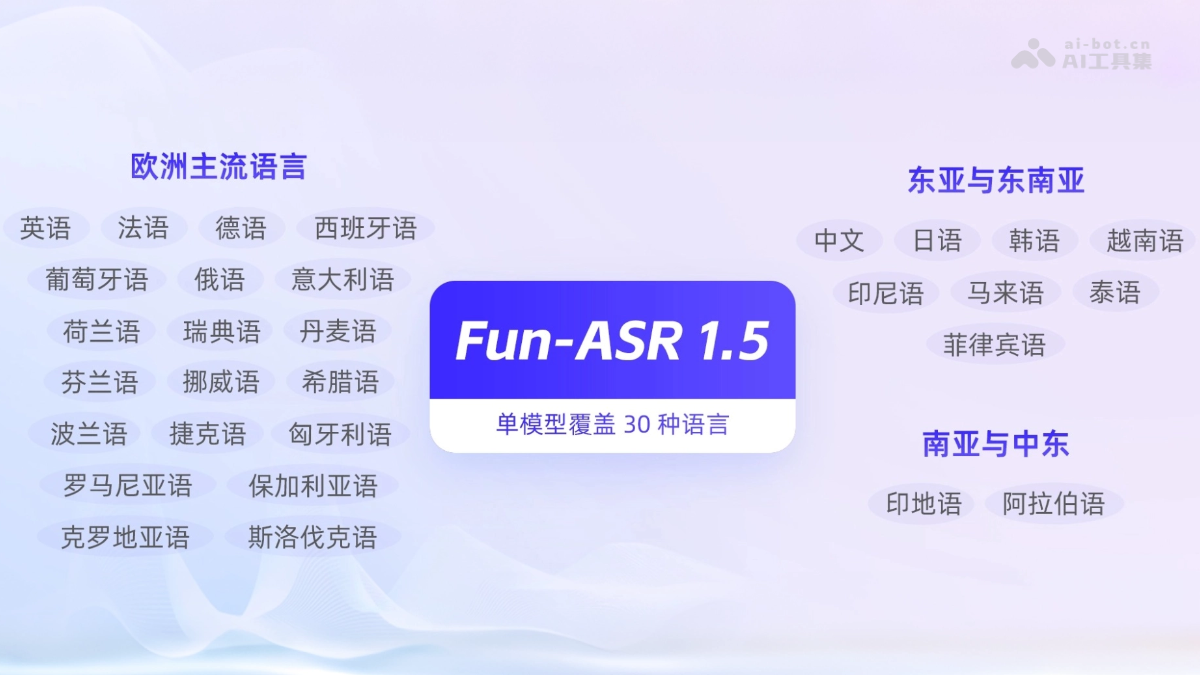
Main features of Fun-ASR1.5
-
Multilingual recognition: A single model covers 30 languages including Chinese, English, Japanese, Korean, French, German, Spanish, Portuguese, Russian, and Arabic.
-
Automatic language switching: No preset language labels are required; it automatically recognizes and switches between multilingual mixed speech in Code-Switching scenarios.
-
Dialect recognition: Covers the seven major dialect systems and more than 20 regional accents, with key optimization for 15 high-demand dialects.
-
Classical poetry recognition: Builds a speech-text alignment corpus of classical poetry from the pre-Qin period to modern times, supporting accurate transcription of classical Chinese recitation.
-
Intelligent punctuation prediction: Automatically inserts punctuation marks such as commas, periods, and question marks based on contextual semantics.
-
Text normalization: Automatically converts numbers, dates, amounts, phone numbers, etc. in spoken language into standard written format.
Technical principles of Fun-ASR1.5
-
MoE architecture: Adopts a mixture-of-experts architecture; when hearing a specific language, only the relevant part is activated for processing, improving the flexibility and efficiency of multilingual processing.
-
Graded and staged training: Uses precise data in a graded and staged manner during training, improving the ability to handle complex real-world speech scenarios.
-
Dialect data-driven: Trained on hundreds of thousands of hours of real dialect speech data, with the average character error rate (CER) reduced by 56.2% compared with the previous version.
-
Classical poetry corpus: Builds a corpus of real-person recitation recordings covering classic texts such as the Book of Songs, the Songs of Chu, the poetry collections of Li Bai and Du Fu, and the ci works of Su Shi and Xin Qiji.
How to use Fun-ASR1.5
-
Alibaba Cloud Bailian Platform: Visit theAlibaba Cloud Bailianofficial website and enter the speech section of the model experience center to call the API.
-
ModelScope Community:Visit https://modelscope.cn/studios/iic/FunAudio-ASR to experience it directly online.
Key information and usage requirements of Fun-ASR1.5
-
Product positioning: End-to-end speech recognition large model.
-
Supported languages: 30 languages (covering major languages of Europe, East Asia, Southeast Asia, South Asia, and the Middle East).
-
Dialect coverage: Seven major dialect systems, with key optimization for 15 high-demand dialects such as Shanghainese, Cantonese, and Sichuanese.
-
Classical poetry accuracy: Character-level accuracy reaches 97% on the internal evaluation set.
-
Usage method: API calls or online experience.
-
No presets required: In multilingual mixed scenarios, there is no need to specify language labels in advance.
Core advantages of Fun-ASR1.5
-
Single-model multilingual: One model seamlessly switches between 30 languages, reducing multi-model deployment and maintenance costs.
-
Leading dialect recognition: Based on hundreds of thousands of hours of dialect data, CER decreased by 56.2% compared with the previous version, supporting authentic dialect text restoration.
-
Automatic Code-Switching: Handles multilingual mixed scenarios within the same conversation without preset configuration.
-
Special optimization for cultural scenarios: Specialized training for classical Chinese poetry recitation, achieving 97% character accuracy and supporting cultural heritage.
-
Intelligent post-processing: Automatic punctuation and text normalization greatly reduce the cost of manual post-editing in scenarios such as meeting minutes and legal transcripts.
Comparison of Fun-ASR1.5 with similar competing products
| Dimension | Fun-ASR1.5 | Seed-ASR | Tencent-ASR |
|---|---|---|---|
| Language coverage | 30 languages, covered by a single model | Multilingual support | Multilingual support |
| Dialect support | Seven major dialect systems, 15 key optimizations, CER reduced by 56.2% | Basic support | Basic support |
| Code-Switching | No preset tags required, automatic recognition and switching | Supported | Supported |
| Classical Chinese poetry recognition | Specialized optimization, 97% character accuracy | Not specified | Not specified |
| Intelligent post-processing | Automatic punctuation + text normalization (numbers/dates/amounts/phone numbers) | Basic punctuation capability | Basic punctuation capability |
| Architecture features | MoE mixture-of-experts architecture | Not disclosed | Not disclosed |
| Open experience | Alibaba Cloud Bailian API + ModelScope Community | Volcano Engine | Tencent Cloud |
Application scenarios of Fun-ASR1.5
-
Multinational meetings: In multinational meeting scenarios, Fun-ASR1.5 can accurately transcribe multilingual mixed dialogue content in real time, without participants needing to preset languages in advance or switch back and forth between multiple translation tools.
-
Smart speakers: In smart home and in-vehicle voice interaction scenarios, Fun-ASR1.5 can accurately recognize commands in various dialects, enabling smart speakers to truly "understand local accents".
-
Online education: In online education scenarios for Chinese studies, Fun-ASR1.5 supports accurate transcription of classical Chinese poetry recitation, helping the digital preservation of traditional culture with 97% character-level accuracy.
-
News interviews: In news interviews and content production scenarios, Fun-ASR1.5 can automatically add punctuation and normalize spoken numbers and dates into standard formats, greatly reducing later manual organizing time.