
What is FullStack Bench
FullStack Bench is a new code evaluation benchmark jointly launched by the ByteDanceDoubao Large Modelteam and the M-A-P community, focusing on full-stack programming and multilingual programming capability evaluation. FullStack Bench covers more than 11 real programming scenarios and contains 3,374 problems involving 16 programming languages, enabling more effective measurement of large models' code development capabilities in the real world. Based on simulating real programming application domains, FullStack Bench provides a comprehensive, multi-domain evaluation platform that helps drive progress in code intelligence technology.
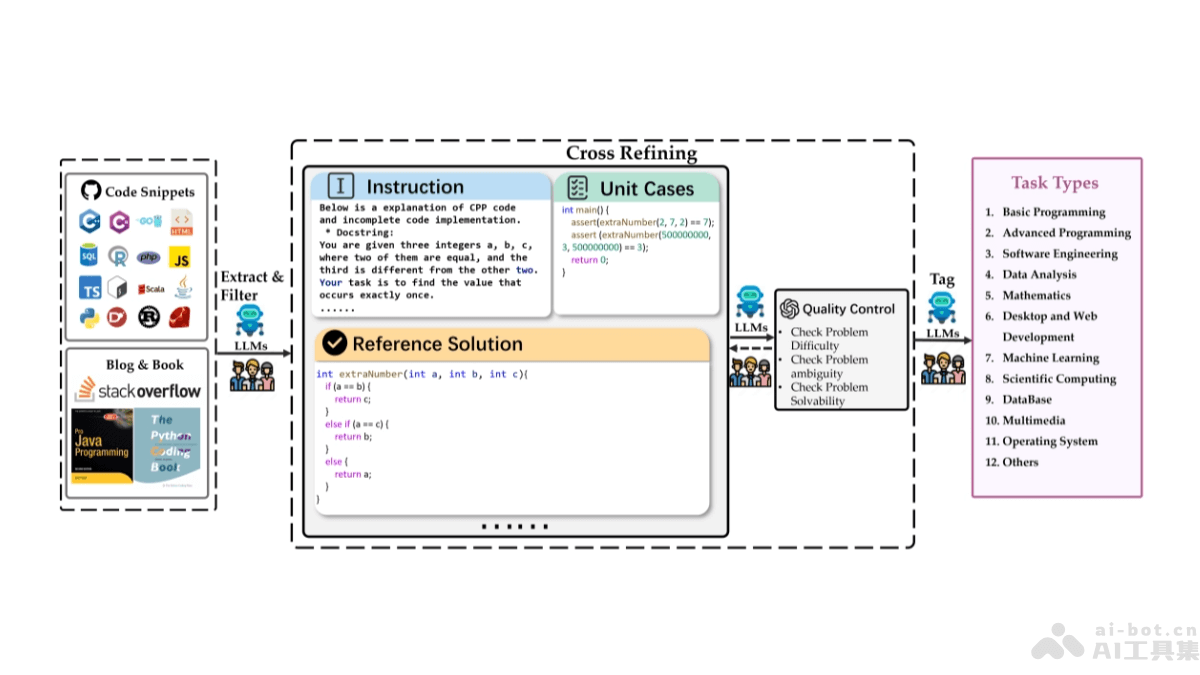
Main features of FullStack Bench
- Comprehensive evaluation: FullStack Bench can evaluate the capabilities of large language models (LLMs) in a variety of real programming scenarios, including basic programming, data science, machine learning, and many other domains.
- Multilingual support: It covers 16 widely used programming languages, making evaluation results more universal and practical.
- Simulation of real application scenarios: It is based on problems extracted from communities such as Stack Overflow to simulate real-world programming problems, ensuring the relevance and practical application value of the evaluation.
- Code quality control: Each problem includes a problem description, reference solution, and unit test cases, ensuring the accuracy and reliability of the evaluation.
Technical principles of FullStack Bench
- Dataset construction: Analyze the distribution of problems in technical communities such as Stack Overflow, extract common real programming application domains, and construct a dataset containing multiple problems.
- Manual annotation and verification: Based on manual annotation and verification processes, ensure the quality of each problem, including the accuracy of the problem description and the correctness of the reference solution.
- Unit test cases: Design unit test cases for each problem to automatically verify whether the code generated by the model meets expectations.
- Multilingual programming capability evaluation: Based on designing real-world instructions and corresponding unit test cases, evaluate the model's performance in different programming languages.
- Sandbox execution environment: It uses the SandboxFusion sandbox execution tool to support multiple programming languages and packages, providing a safe and isolated environment for code execution.
Project address of FullStack Bench
- GitHub repository:https://github.com/bytedance/FullStackBench
- HuggingFace model library:https://huggingface.co/datasets/ByteDance/FullStackBench
- arXiv technical paper:https://arxiv.org/pdf/2412.00535
Application scenarios of FullStack Bench
- Code intelligence evaluation: Use FullStack Bench to test and evaluate the performance of large language models on code generation, understanding, and debugging tasks.
- Education and training: Use real programming problems in the dataset as teaching cases to help students understand programming concepts and practice programming skills.
- Research and development: Provide researchers with a standardized testing platform to experiment with and improve code-related AI technologies.
- Software development testing: Use FullStack Bench in the software development cycle to automatically test code quality and detect potential defects in advance.
- Multilingual programming capability evaluation: Evaluate developers' proficiency in different programming languages as part of technical recruitment and career development.