
What is the Doubao Vision Understanding Model
The Doubao Vision Understanding Model isDoubaoan advanced AI large model launched that has visual recognition and understanding reasoning capabilities. The Doubao Vision Understanding Model has powerful visual grounding capabilities, supports box grounding and point grounding for multiple targets, small targets, and general targets, supports grounding counting, describing grounding content, and 3D grounding, supports recognizing the category, shape, texture, etc. of objects in images, understands the relationships between objects and the meaning of scenes, and performs complex logical calculation tasks. The model has greatly improved video understanding capabilities, such as memory, summary understanding, speed perception, long video understanding, etc., and can delicately describe visual content and create stories. The release of the Doubao model brings visual understanding technology into an era of lower cost and broader application.
Main features of the Doubao Vision Understanding Model
- Content recognition capability: recognizes basic elements such as the category, shape, and texture of objects in images, and understands the relationships between objects, spatial layout, and the overall meaning of the scene.
- Understanding and reasoning capability: the model can recognize image and text information and also perform complex logical calculations, such as solving calculus problems, analyzing paper charts, and diagnosing real code issues.
- Visual description capability: the model has delicate visual description and creation capabilities, and can write blessings based on a product's design or meaning, or create fantasy stories based on a child's doodles.
- Visual grounding: supports multiple targets, small targets, and 3D grounding, and is suitable for complex scenarios.
- Video understanding: supports video semantic search, long video summarization, and speed perception.
- Cost advantage: the Doubao Vision Understanding Model costs only 3 li per thousand tokens for input, that is, 0.003 yuan per thousand tokens, and the cost of processing one 720P image is less than 4 fen. Compared with the industry average, the price is reduced by 85%.
How to use the Doubao Vision Understanding Model
- Visit the official website: visit Doubao'sofficial website. Or visitVolcano Engine API interface。
- Log in to the account: follow the prompts to complete login and registration.
- Upload an image: upload the image you want the model to analyze as needed.
- Enter relevant text: enter a question or description related to the image to help the model better understand the image content.
- Send a request: click the submit or send button to send a request to the Doubao Vision Understanding Model.
- View the result: after the model finishes processing, view the returned result.
Actual test results of the Doubao Vision Understanding Model
- Content recognition capability
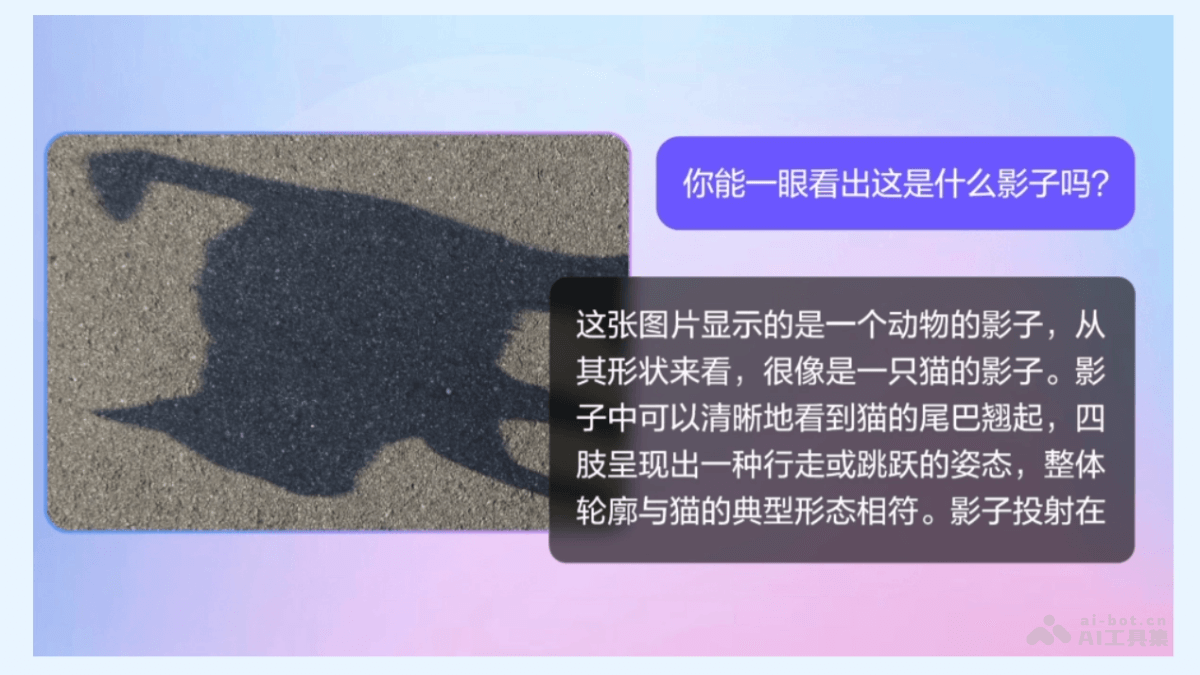
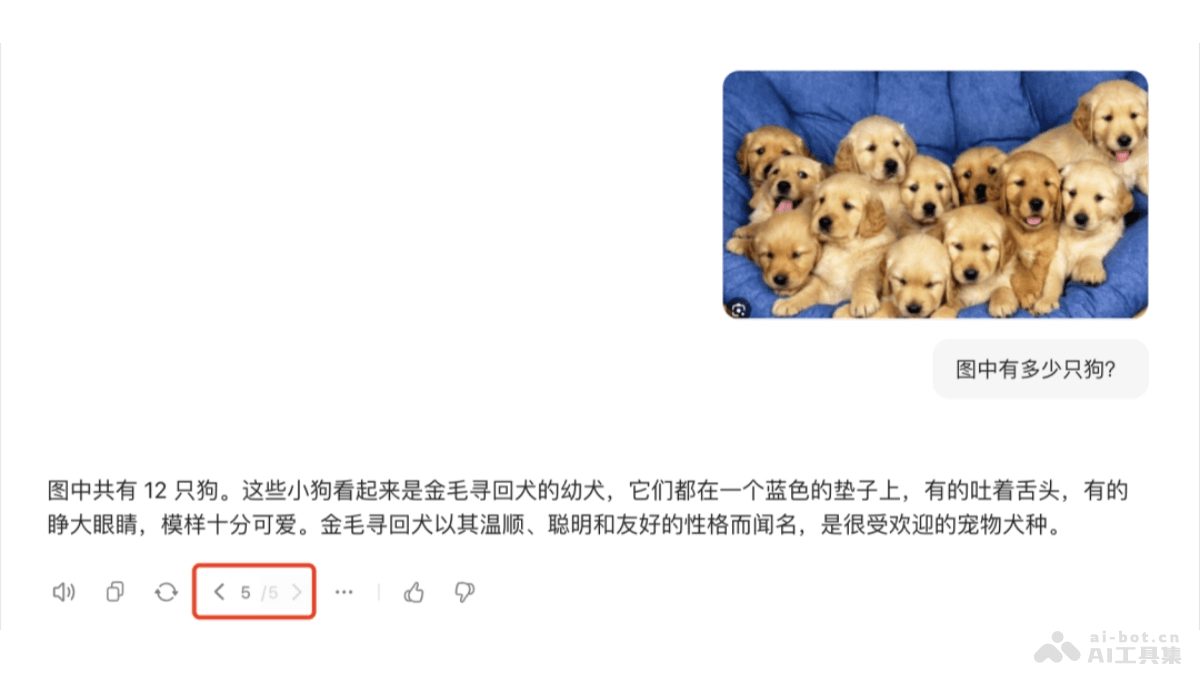
- Understanding and reasoning capability
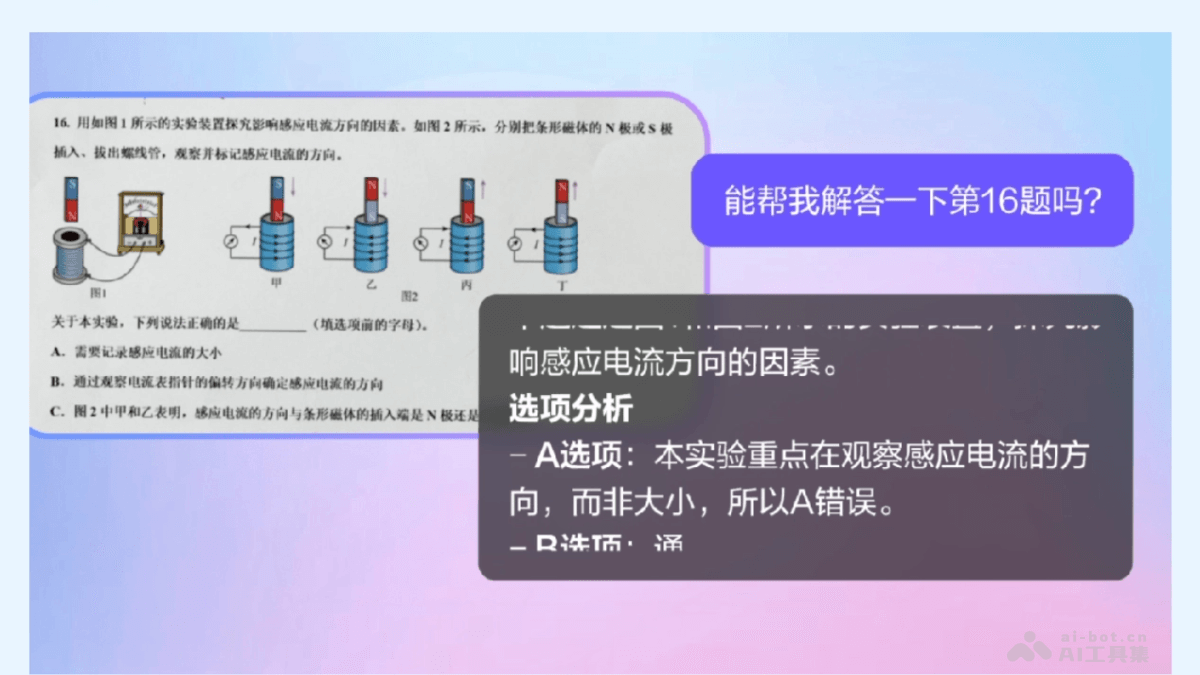
Application scenarios of the Doubao Vision Understanding Model
- Image question answering (QA): users upload images and ask related questions, and the model gives answers based on the image content.
- Medical imaging analysis: in the medical field, the model helps analyze medical images such as X-rays, CT scans, and MRI, assisting doctors in diagnosis.
- Education and scientific research: educators and researchers analyze charts, diagrams, and experimental data to assist teaching and research.
- E-commerce and retail: On e-commerce platforms, used for product image description generation, recommendation systems, and customer service.
- Content moderation: Used to automatically review image content, identify and filter inappropriate content.