
What is DINO-XSeek
DINO-XSeek is a multimodal object detection model launched by IDEA Research Institute, combining visual perception and natural language understanding capabilities. DINO-XSeek precisely locates targets in images based on complex language descriptions, identifying target attributes (such as color, shape, action, etc.), positional relationships, and interaction situations. The model is based on DINO-X unified vision model, using a retrieval-based framework, first detecting all objects in the image, then using a large language model to retrieve the most relevant objects from candidate targets. DINO-XSeek has a wide range of applications in autonomous driving, industrial manufacturing, smart homes, agriculture and food, and other fields, enabling functions such as safety detection, quality control, and dangerous behavior recognition, providing a solution for object detection in complex scenarios that is closer to human understanding capabilities.
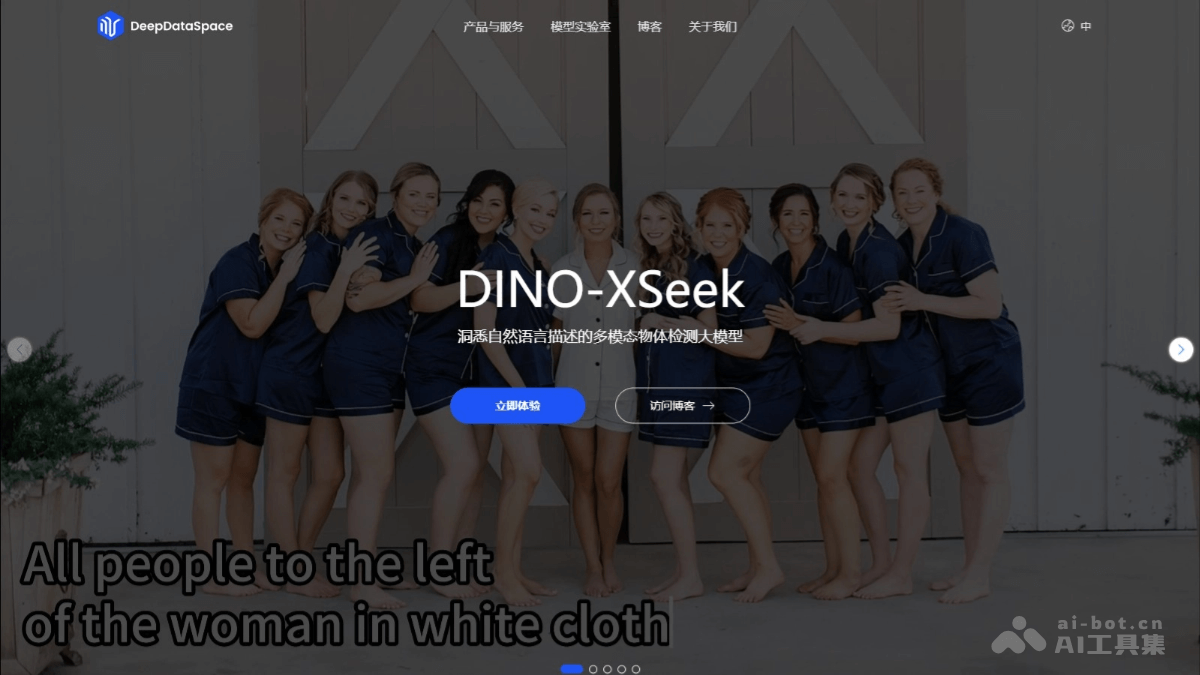
DINO-XSeek's Main Features
- Complex Language Understanding: Precisely locates targets in images based on natural language descriptions, supports detailed descriptions of targets, such as "girl wearing a red top" or "person standing next to a car."
- Attribute Recognition: Supports recognition of target attributes such as color, shape, age, gender, clothing, posture, action, etc.
- Position and Spatial Relationship Recognition: Supports determining the relative positions between targets and the spatial relationships between targets and the environment.
- Interaction Relationship Recognition: Recognizes interactions between targets and interactions between targets and the environment.
- Reasoning and Multi-Instance Processing: Supports complex language reasoning and can handle multi-instance reference tasks.
DINO-XSeek's Technical Principles
- Visual Encoder: Extracts visual information from images, generates visual tokens, used to describe objects and scenes in images.
- Object Detection Model (DINO-X): Based on an open-set object detection model, detects all objects in the image to generate bounding boxes for candidate targets.
- Text Tokenizer: Converts natural language descriptions into text tokens, extracting semantic information from language.
- Retrieval-Based Framework: Inputs visual tokens, object tokens, and text tokens together into a large language model (LLM), and based on the reasoning capabilities of the language model, retrieves the object that best matches the language description from candidate targets, without directly predicting coordinates.
- Multimodal Fusion and Reasoning: Combines visual and language modalities, understands complex language descriptions, and uses the reasoning capabilities of the language model to precisely locate targets, achieving Referring Expression Comprehension (REC).
DINO-XSeek's Project Address
- Project Official Website:https://deepdataspace.com/blog/dino-xseek
DINO-XSeek's Application Scenarios
- Autonomous Driving: Recognizes roads, traffic signs, obstacles, etc., assists autonomous driving decisions, and improves driving safety.
- Industrial Manufacturing: Detects component defects, identifies personnel not complying with safety regulations, and ensures production quality and safety.
- Smart Homes and Daily Life: Recognizes dangerous behaviors at home (such as elderly people falling), and provides interactive support for smart devices.
- Agriculture and Food: Detects crop pests and diseases and food defects, improving planting and production efficiency.
- Security Monitoring: Recognizes abnormal behaviors and targets, provides real-time warnings, and enhances the effectiveness of monitoring systems.