
What is DeepSeek-V4-Flash-Vision-Exp
DeepSeek-V4-Flash-Vision-Exp is an experimental multimodal visual understanding model released by DeepSeek . While maintaining DeepSeek-V4-Flash text capabilities, the model adds visual input, and its multimodal Agent performance is close to Opus-4.8. The model supports three API formats: Chat Completions, Messages, and Responses. Images are billed by token, with a maximum of 384 tokens per image, and the price is on par with V4-Flash. The model is also launched with the Files API, supporting image reuse.
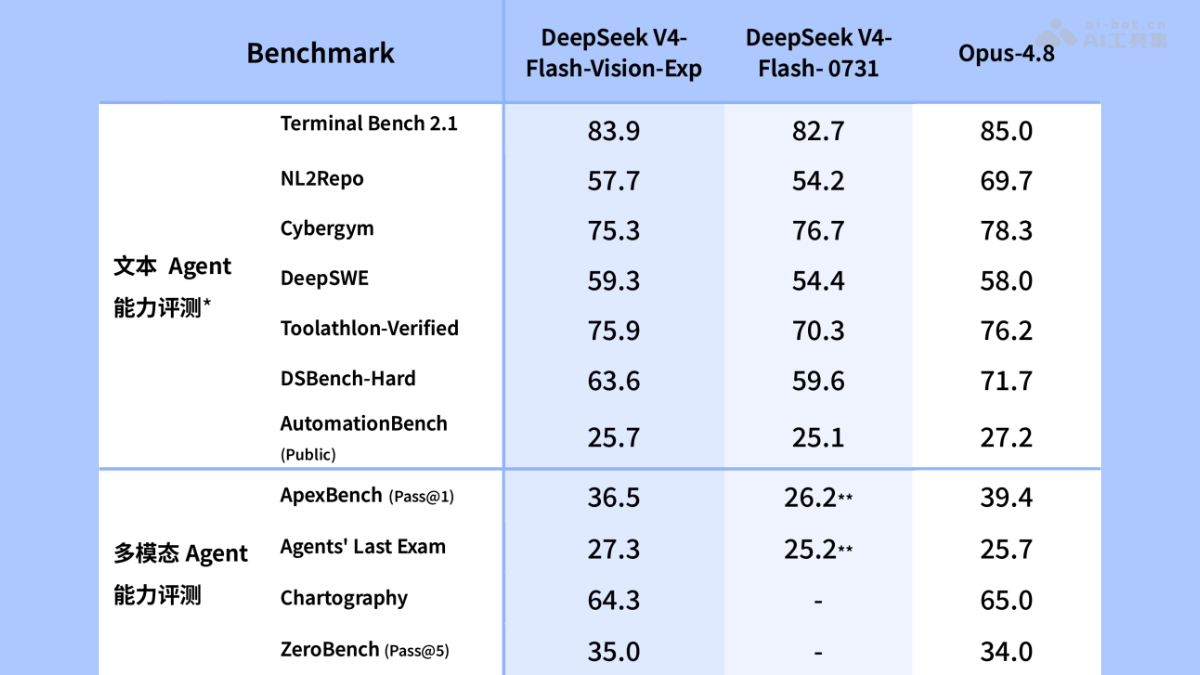
Main features of DeepSeek-V4-Flash-Vision-Exp
-
Visual understanding: Supports image input, can recognize image content, charts, and interface elements and perform semantic understanding.
-
Multimodal Agent: Executes complex tasks requiring visual perception within an Agent framework, such as generating PPTs, refactoring web pages, and analyzing screenshots.
-
Text capability retention: Pure text reasoning, Agent tasks, and world knowledge levels are on par with the official version of V4-Flash, without degradation due to the addition of visual capabilities.
-
Multi-format API: Supports calls in three API formats: Chat Completions, Messages, and Responses, making it easy to integrate into different applications.
-
Flexible image input: Supports three ways to pass in images: base64 inline, external URL, and Files API.
-
Image reuse: Uploading images through the Files API returns a file_id, which can be referenced repeatedly in multi-turn conversations and multiple requests, saving bandwidth.
Technical principles of DeepSeek-V4-Flash-Vision-Exp
- Visual encoding and unified representation: Images are converted by a visual encoder into token sequences aligned with text. A single image can be encoded into up to 384 tokens, which are fed together with text tokens into the language model for joint reasoning, enabling mixed image-text understanding.
- Modular architecture extension: A visual understanding module is added on top of the V4-Flash base model using a modular extension strategy, ensuring that the newly added visual capabilities do not compromise the original text Agent, reasoning, and world knowledge performance, and that text and multimodal capabilities can be optimized independently.
- Long context processing: The model supports a context length of 1M tokens and a maximum output length of 384K, processing long mixed sequences containing multiple images through an efficient attention mechanism to meet the needs of complex Agent tasks.
- Dual-mode reasoning mechanism: Built-in thinking mode and non-thinking mode. The former performs deep chain-of-thought reasoning to improve accuracy on complex tasks, while the latter quickly generates responses to reduce latency. Users can flexibly switch according to task complexity.
How to use DeepSeek-V4-Flash-Vision-Exp
- Account preparation: Visit the DeepSeek open platform,https://platform.deepseek.com/ register an account and complete login.
- Obtain credentials: Go to the "API Keys" page in the console, create an API key, copy it, and save it.
-
API call: Set
model='deepseek-v4-flash-vision-exp'in the request to call this model. -
API formats: Supports integration via three standard formats: Chat Completions, Messages, and Responses.
-
Image input: Images can be provided in three ways: base64 inline encoding, external image URL, or Files API.
-
Files API reuse: First upload the image to the platform to obtain
file_id, subsequent requests can reference it directly, with no need to re-upload. -
Agent Framework Integration: DeepSeek Harness 0.1.1 now supports it natively, so it can be integrated directly into existing Agent workflows.
-
Mode Switching: Supports both thinking mode and non-thinking mode, allowing flexible selection of reasoning depth based on task complexity.
Core Advantages of DeepSeek-V4-Flash-Vision-Exp
-
Zero Loss in Text Capabilities: While adding visual understanding, its text-only Agent, reasoning, and world knowledge capabilities are fully on par with the official V4-Flash release.
-
Leap in Multimodal Agent: Its performance on multimodal Agent benchmarks such as ApexBench and Agents' Last Exam approaches Opus-4.8, achieving a major leap.
-
Extreme Cost-Effectiveness: Continuing V4-Flash's low-price strategy, images are billed by token with a per-image cap of only 384 tokens, making visual invocation costs extremely low.
-
Efficient Image Reuse: The Files API supports uploading and then referencing via
file_idmultiple times, avoiding repeated transmission and reducing bandwidth and request size pressure. -
Full Format Compatibility: Natively supports the Chat Completions, Messages, and Responses API formats, as well as the DeepSeek Harness 0.1.1 framework.
-
Long-Context Support: A 1M token context length and 384K maximum output, easily handling long-sequence complex Agent tasks containing multiple images.
Project Address of DeepSeek-V4-Flash-Vision-Exp
- HuggingFace Model Repository:https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash-Vision-Exp
Comparison of DeepSeek-V4-Flash-Vision-Exp with Similar Competitors
| Comparison Dimension | DeepSeek-V4-Flash-Vision-Exp | Opus-4.8 (Anthropic) |
|---|---|---|
| Developer | DeepSeek | Anthropic |
| Model Positioning | Experimental multimodal visual Agent model | Flagship multimodal large model |
| Text Agent Capabilities | Terminal Bench 2.1 score 83.9, on par with V4-Flash | Terminal Bench 2.1 score 85.0, slightly ahead |
| Multimodal Agent Capabilities | ApexBench 36.5, Agents' Last Exam 27.3, overall close to Opus-4.8 | ApexBench 39.4, Agents' Last Exam 25.7, one of the industry benchmarks |
| Context Length | 1M tokens | 200K tokens |
| Image Billing Method | Converted to tokens by size, per-image cap of 384 tokens | Billed by token |
| Input Price | ¥0.05–3.0 / million tokens (time-based caching strategy) | Flagship pricing, significantly higher than DeepSeek |
| Output Price | ¥4.5–9.0 / million tokens (time-based) | Flagship pricing, significantly higher than DeepSeek |
| Concurrency Limit | 2500 | Lower (usually in the hundreds) |
Application Scenarios of DeepSeek-V4-Flash-Vision-Exp
-
Intelligent E-commerce Operations: Automatically recognizes product images and generates multilingual selling-point copy, detail-page layout suggestions, and marketing materials adapted to different platforms.
-
Educational Courseware Creation: Quickly generates structured courseware based on textbook screenshots or hand-drawn blackboard notes, automatically inserting diagrams and interactive exercises matching the knowledge points.
-
Medical Imaging Assistance: Read screenshots or imaging materials of medical examination reports, assist in extracting key indicators, compare historical data, and generate a preliminary analysis summary.
-
Game Asset Design: Generate character/scene design documents based on concept sketches or reference images, and output style specifications and resource lists that can be used directly by the art team.
-
Intelligent Customer Service Quality Inspection: Analyze screenshots, order pages, or product images in customer service conversations, automatically determine communication accuracy, and provide service quality scores and improvement suggestions.