
What is ChatTTSPlus
ChatTTSPlus isChatTTSan extended version that adds features such as TensorRT acceleration, voice cloning, and mobile model deployment, improving the performance and flexibility of speech synthesis. On the Windows platform, it achieves over 3x acceleration, increasing from 28 tokens/s to 110 tokens/s, greatly improving processing speed. ChatTTSPlus provides a Windows integrated package, making it convenient for users to extract and use with one click. Based on technologies such as LoRA, ChatTTSPlus implements voice cloning, and through techniques such as pruning and knowledge distillation for model compression and acceleration, it creates the ability for personalized voices.
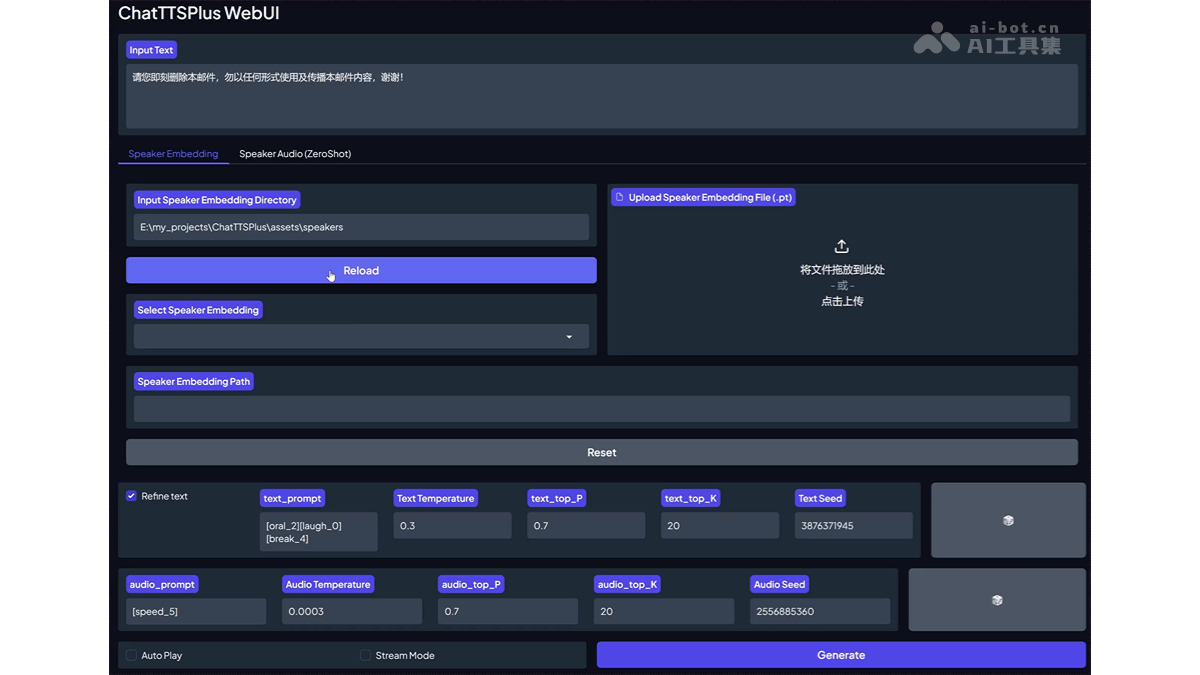
Main features of ChatTTSPlus
- TensorRT acceleration: Based on TensorRT technology, ChatTTSPlus achieves over 3x acceleration on the Windows platform, improving the efficiency of speech synthesis.
- Voice cloning: Using technologies such as LoRA, ChatTTSPlus can implement voice cloning, supporting users in replicating the voice of a specific person.
- Mobile model deployment: The project uses model compression and acceleration to enable speech synthesis models to run on mobile devices.
- One-click extraction and use: Provides a Windows integrated package, allowing users to extract and use with one click, simplifying the installation and configuration process.
- Model compression: Using pruning and knowledge distillation techniques, it reduces model size, improves operating efficiency, and adapts to resource-constrained environments.
- Web UI demo: Provides a web user interface based on TensorRT and PyTorch, making it convenient for users to quickly experience and test speech synthesis features.
Technical principles of ChatTTSPlus
- Deep learning optimization: Optimizes the speech synthesis process based on deep learning technology, improving the naturalness and fluency of synthesized speech.
- High-performance computing: The integration of TensorRT makes speech synthesis tasks running on GPUs more efficient, especially on NVIDIA hardware.
- Cross-platform deployment: The project supports mobile deployment, allowing speech synthesis technology to be applied to a wider range of devices and scenarios.
ChatTTSPlus project address
- GitHub repository:https://github.com/warmshao/ChatTTSPlus
Application scenarios of ChatTTSPlus
- Audiobooks and podcasts: Convert e-books or articles into audio content, providing a high-quality experience for visually impaired people or users who like listening to books.
- Language learning: Assist language learners in imitation and listening practice to improve pronunciation and listening skills, especially using voice cloning technology to imitate native speakers' pronunciation.
- Assistive technology: Provide speech output of text content for visually impaired people or those with reading difficulties, helping them better access information.
- Customer service: Used in automated customer service systems to provide natural-sounding voice replies and improve customer experience.
- Entertainment and gaming: Voice characters in video games or virtual reality applications to enhance immersion.