
Zhipu officially launches the all-new visual reasoning model GLM-4.6V series models, and fully open-sources them!
This release includes 2 versions:
- GLM-4.6V: total parameter count 106B, activated parameters per inference about 12B, visual understanding accuracy reaching that of same-parameterSOTA, suitable for cloud and high-performance scenarios;
- GLM-4.6V-Flash: total parameter count 9B, more lightweight, faster, suitable for local deployment;
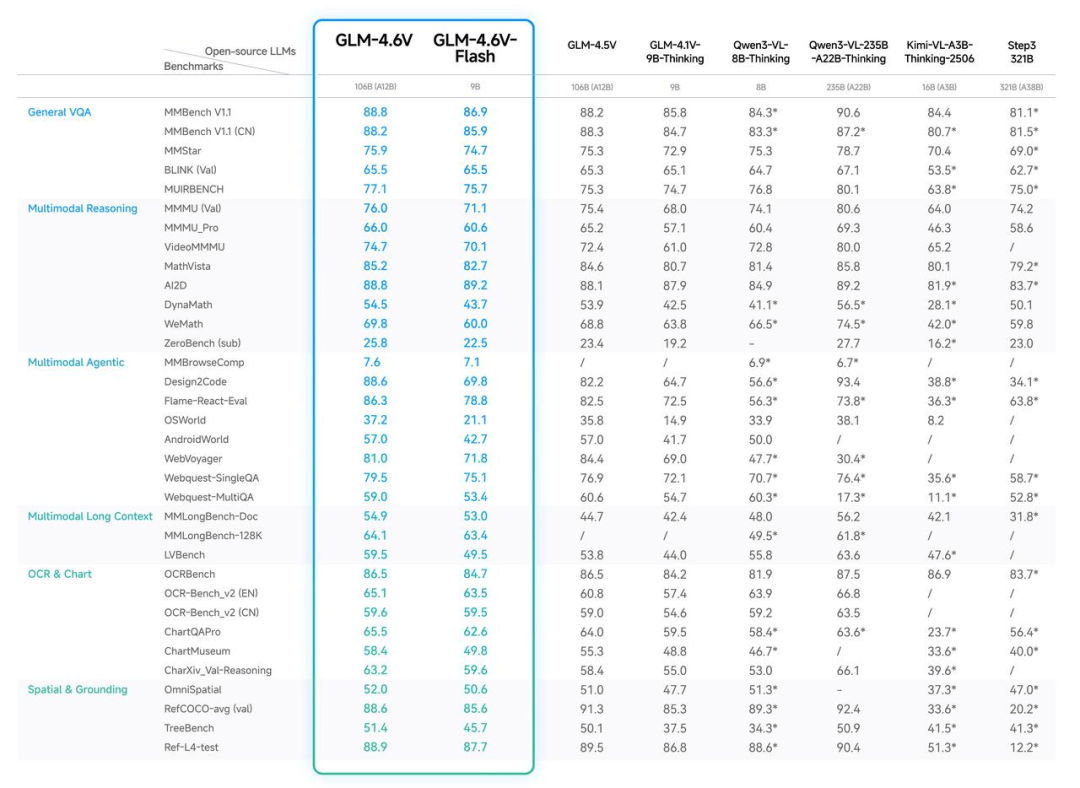
GLM-4.6V is the first to integrate Function Call (tool calling) capability into a vision model, giving the large model both eyes and hands, supporting native handling of complex visual tasks, and being able to proactively call tools based on visual understanding to complete follow-up operations.
For example, GLM-4.6V can directly "understand" papers with complex structures and a large number of charts and diagrams, and reorganize them into an article full of pictures and text that everyone can understand;
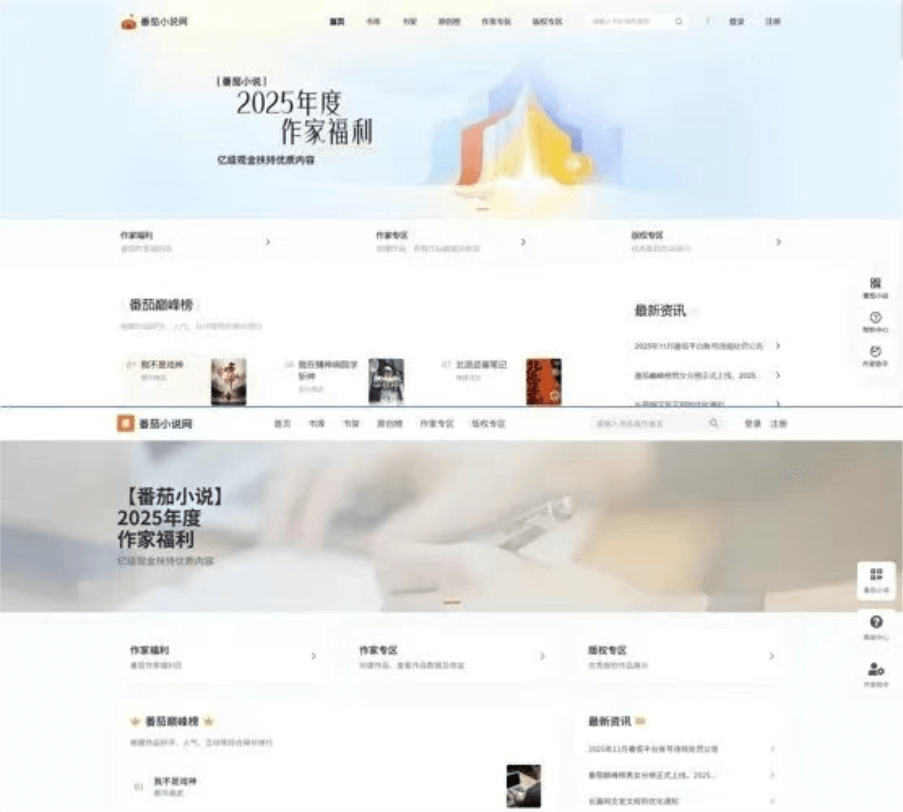
With just a single screenshot, it can break down the page structure and replicate an almost identical front-end page.
01. Hands-on Performance
Open z.ai, and select the model GLM-4.6V in the upper left corner of the page.
Official website:https://chat.z.ai
GitHub:https://github.com/zai-org/GLM-V
Hugging Face:https://huggingface.co/collections/zai-org/glm-46v
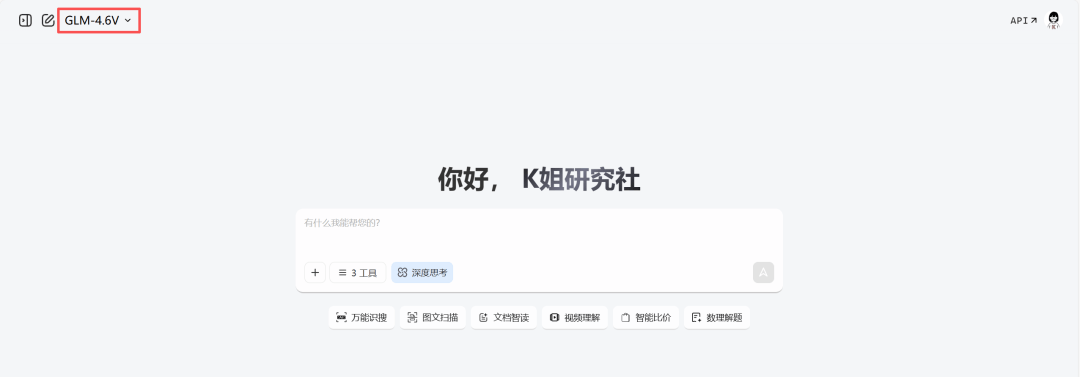
GLM-4.6V can call 4 tools: image recognition, image processing, image search, and shopping search.
Below the input box, the official preset includes a set of typical function examples, including universal recognition and search, image and text scanning, intelligent document reading, video understanding, smart price comparison, and math and science problem solving, etc.Select any function, and GLM-4.6V will automatically call the matching tool.
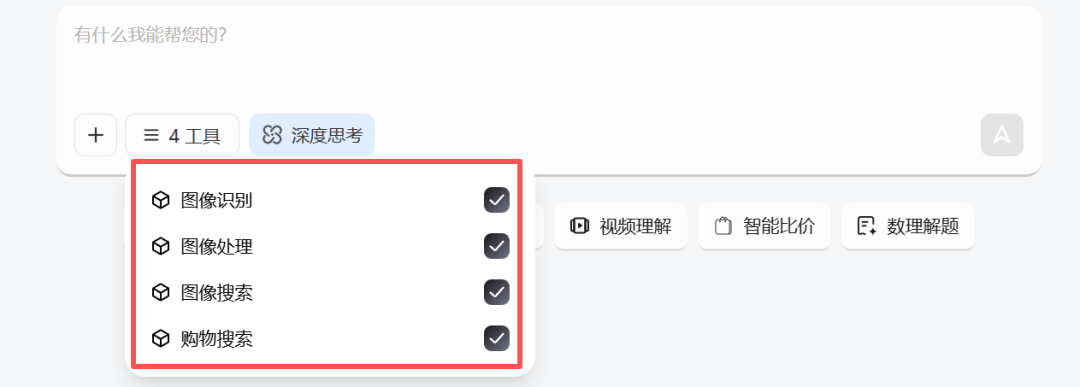
case1 Universal Recognition and Search
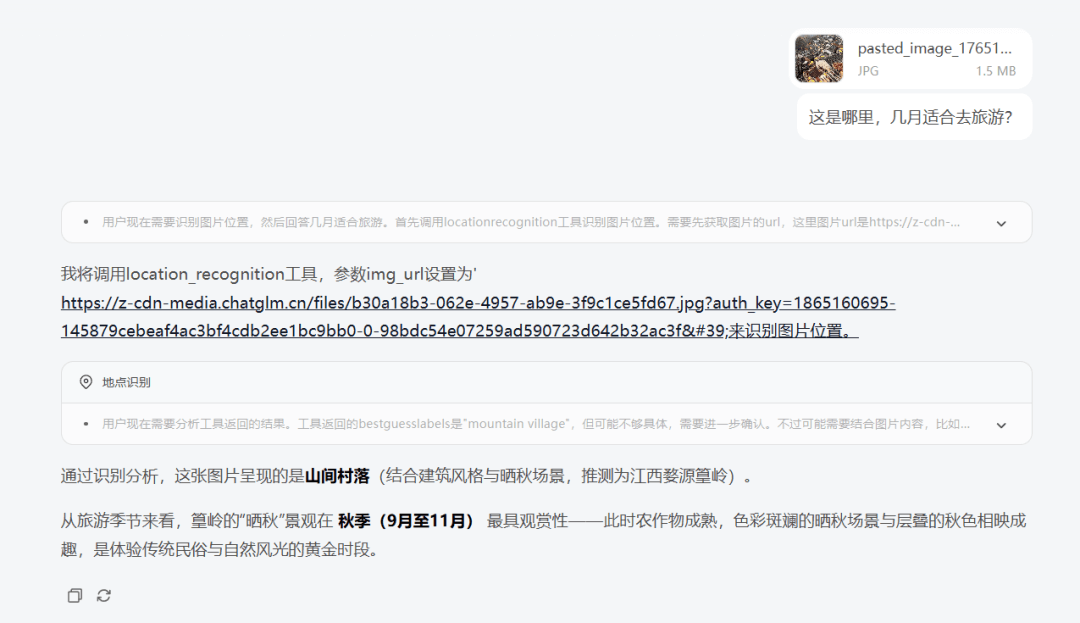
Prompt: Where is this, and which months are suitable for traveling there?
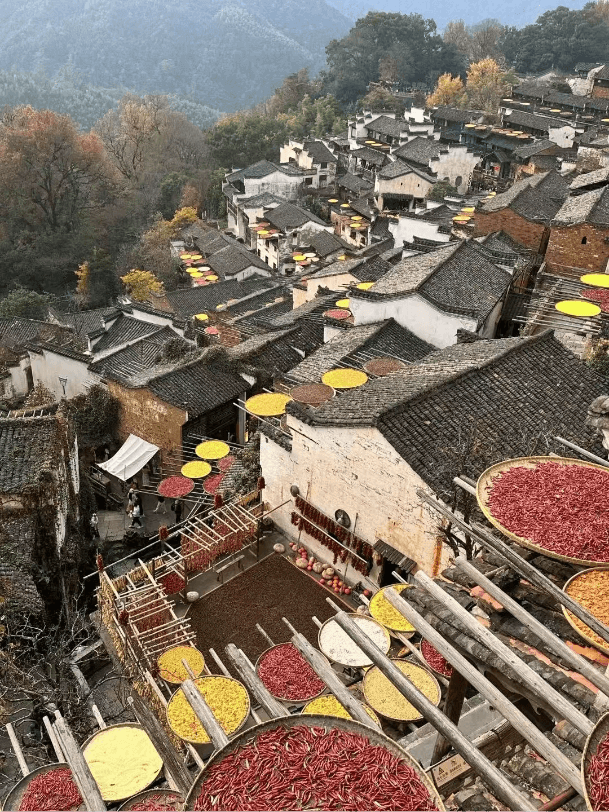
GLM-4.6V has native visual understanding capability, directly calls the image recognition tool to identify the content in the image, and then searches for relevant knowledge to give a reply.
case2 Image and Text Scanning
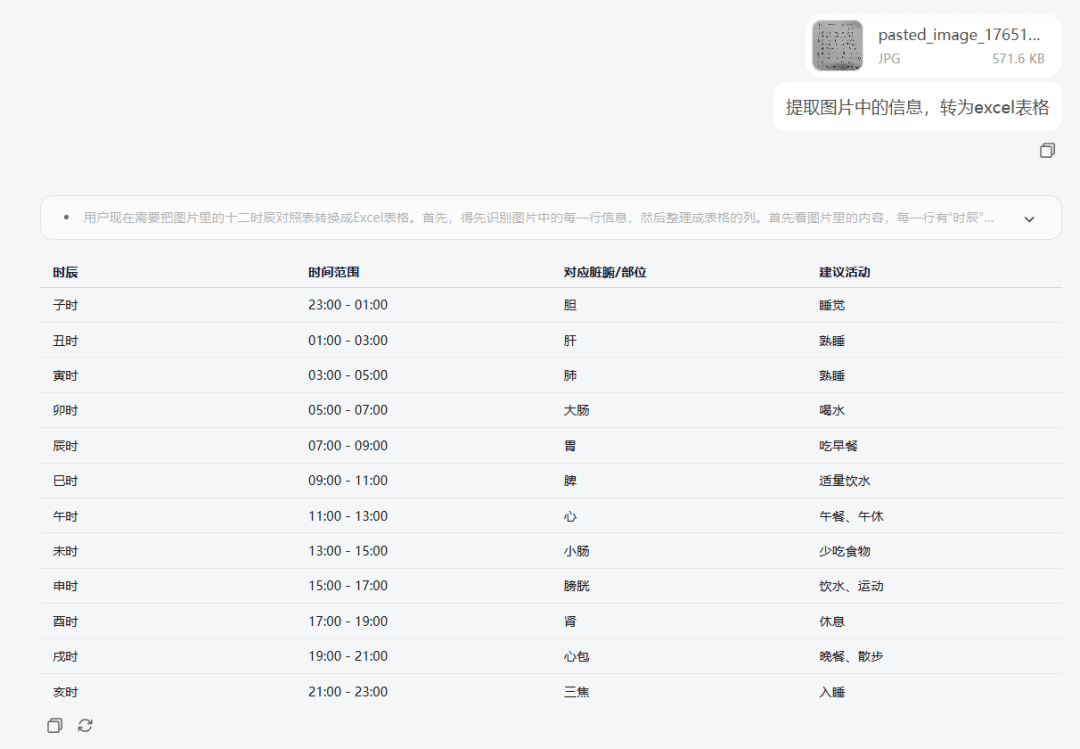
Prompt: Extract the information in the image and convert it into an Excel table.
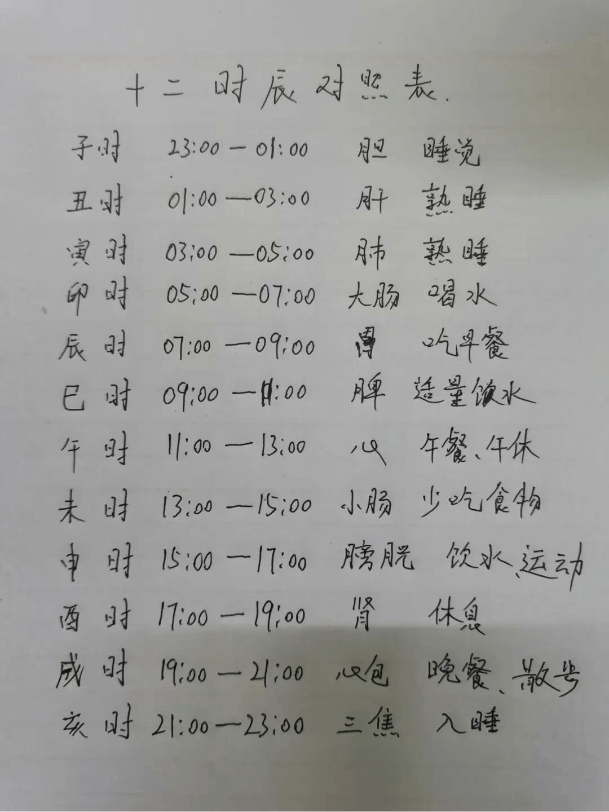
GLM-4.6V's understanding of content and layout is very accurate.
Then try something a bit more complex:
Prompt: Help me scan out the ingredients, composition table, and other instructions of this cat food, and analyze whether it is suitable for a 2-year-old kitten to eat long-term?
GLM-4.6V also accurately identifies the ingredient composition and product components, and analyzes based on these contents.
case3 Intelligent Document Reading
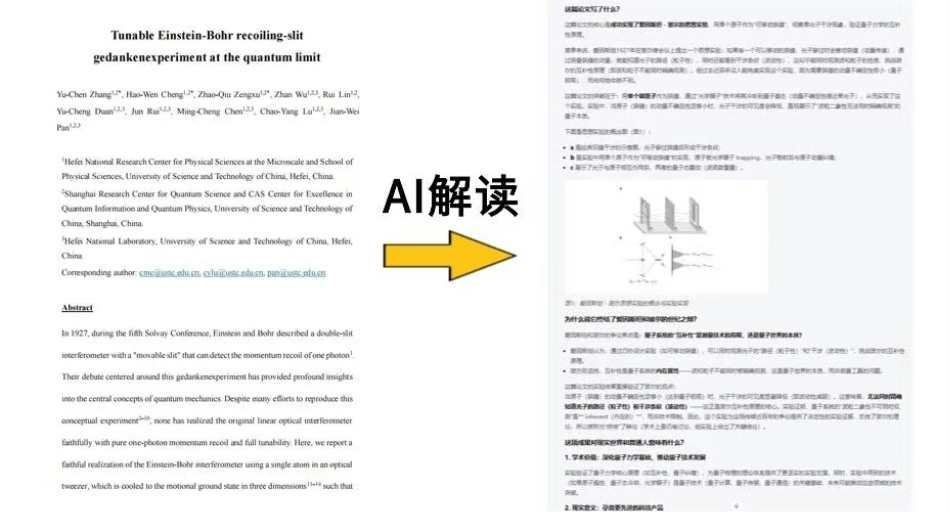
Last week, Professor Pan Jianwei's team at USTC published the latest research results in the international top journalPRL(Physical Review Letters), achieving breakthrough progress in the field of quantum physics and ending the century-long debate between Einstein and Bohr.
I found the original paper and asked GLM-4.6V to help us analyze it.
Prompt: Explain in plain and easy-to-understand words: what this paper writes about, why it is said to have ended the century-long debate between Einstein and Bohr, and what this achievement means for the real world and ordinary people besides its academic value.
GLM-4.6V can not only understand complex chart content, but also reorganize key information and explain it clearly in a way full of pictures and text.
case4 Video Understanding
Prompt: This is a classic clip from The Secret Life of Walter Mitty. What specific cinematographic language does it use, and what are the highlights of the storyboard design?
The interpretation given by GLM-4.6V is very professional: what the entire video tells, what shots are used, what emotions these cinematographic languages express... much deeper than my understanding.
case5 Math and Science Problem Solving
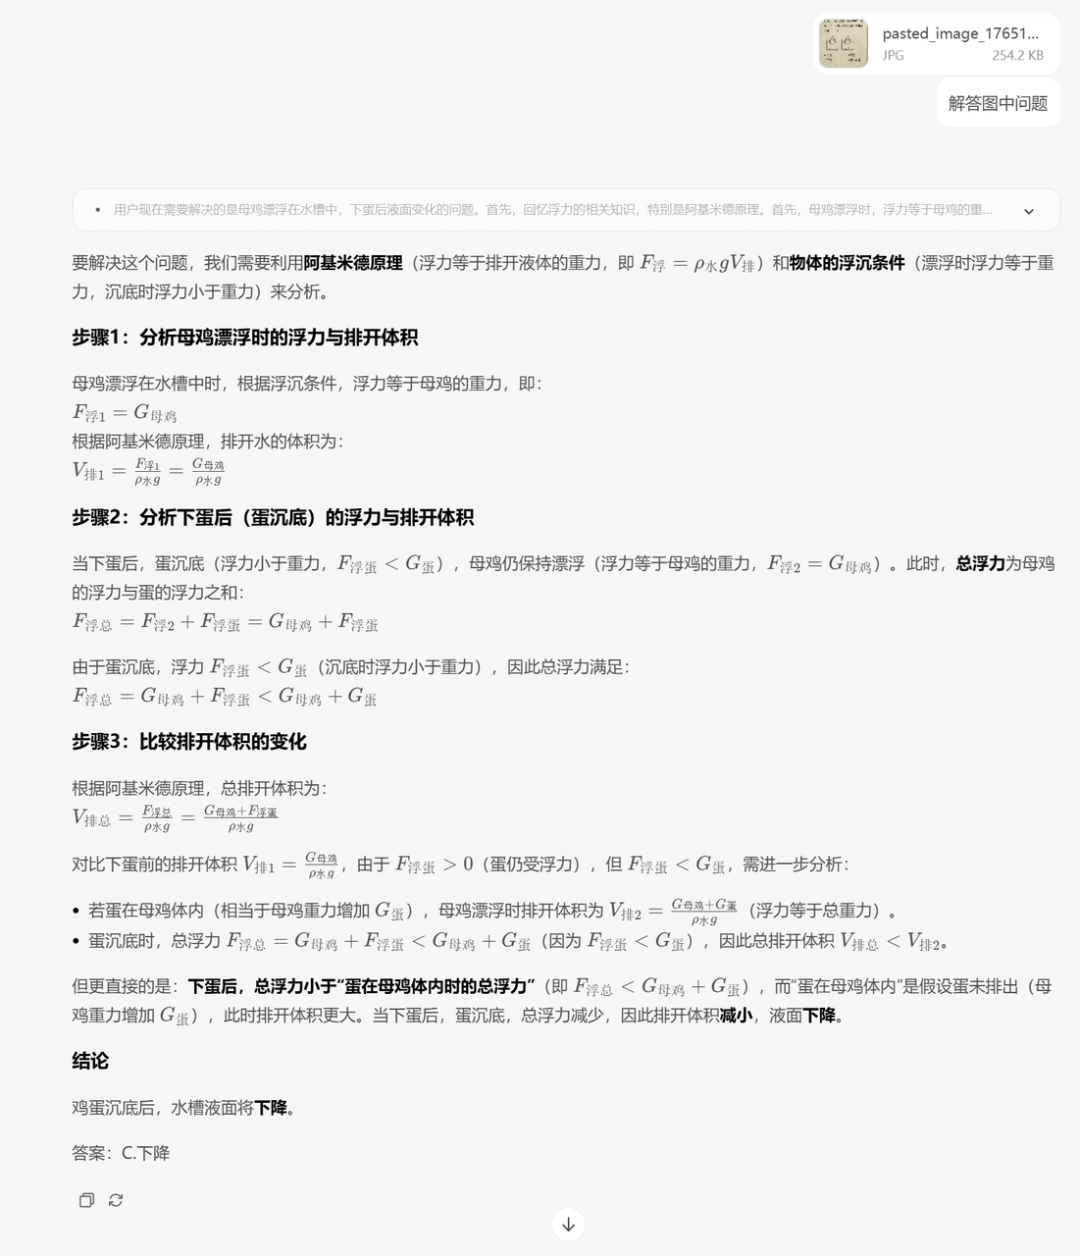
Prompt: Solve the problem in the image.
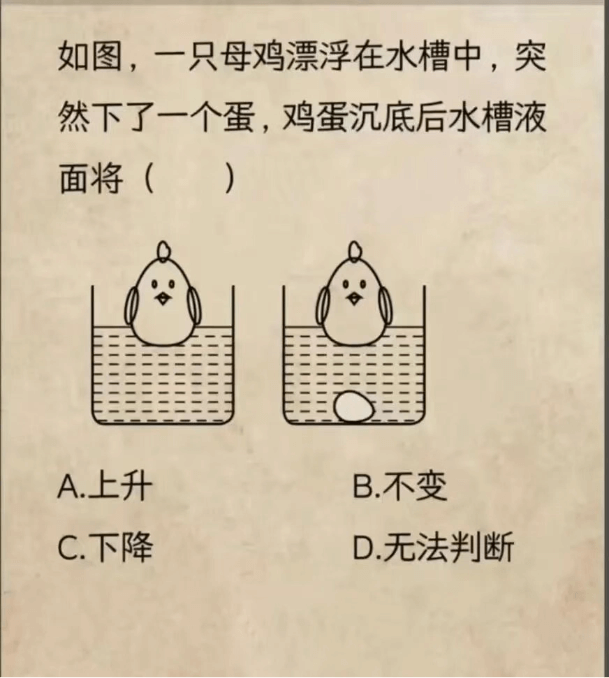
GLM-4.6V can combine visual information with external knowledge for compositional reasoning, and its problem-solving approach is very clear.
case6 Smart Price Comparison
Prompt: Please help me search for affordable similar earrings to the ones Zhao Lusi is wearing in the picture.
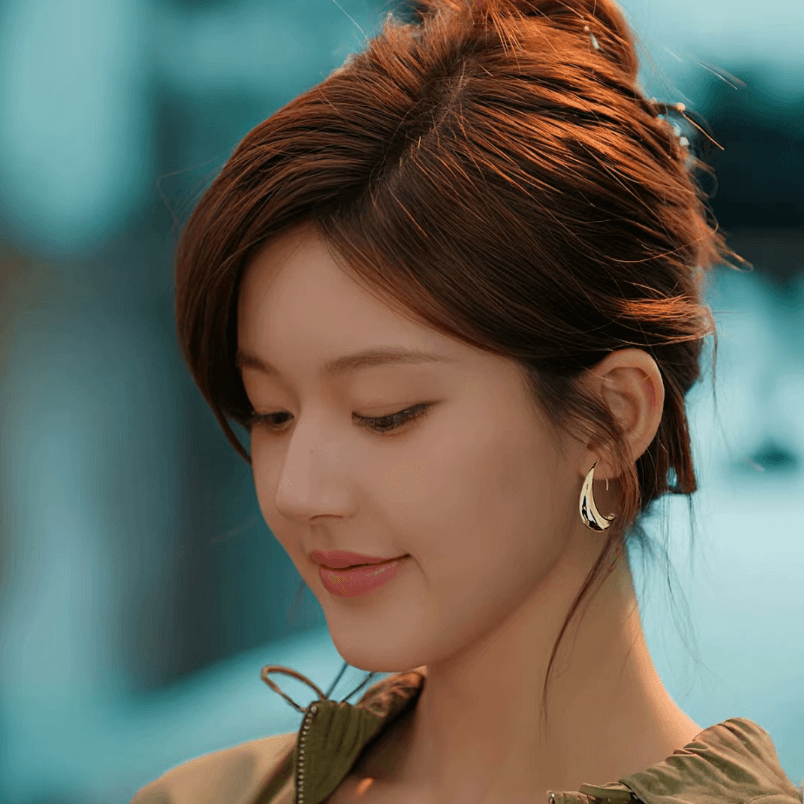
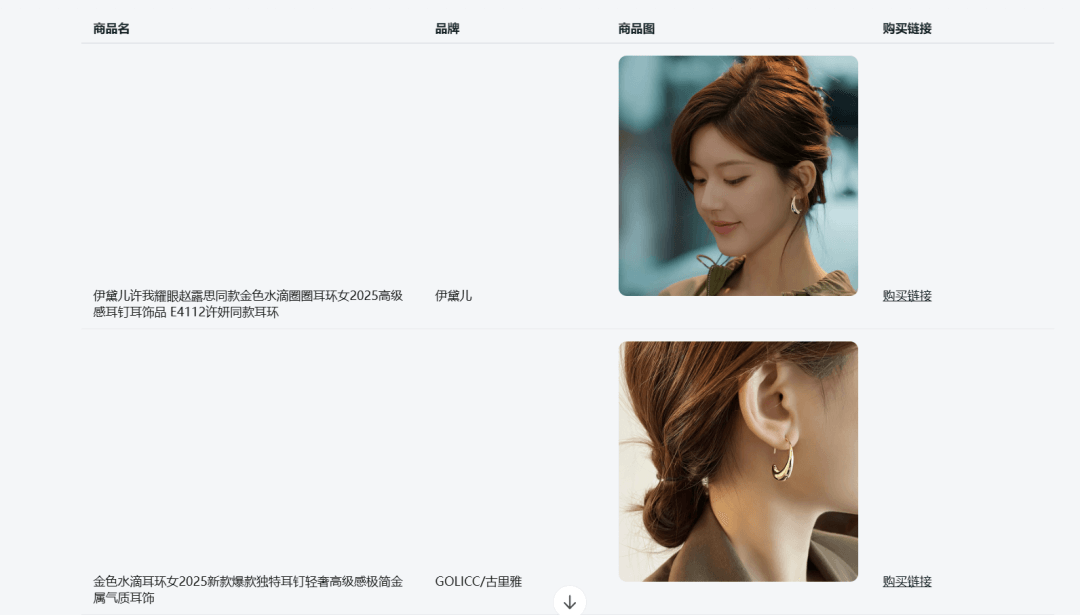
GLM-4.6V directly helped me find several affordable alternatives of the same style. The recognition was quite accurate, and they were available on different platforms~
case7 Image-Text Content Creation
Prompt: Search for the development process of visual models and generate a richly illustrated report.
case 8 Replicating a Front-End Webpage
Prompt: Replicate the webpage in the screenshot. All image assets involved in the page must directly use real images and videos, do not use placeholder or placeholder elements.
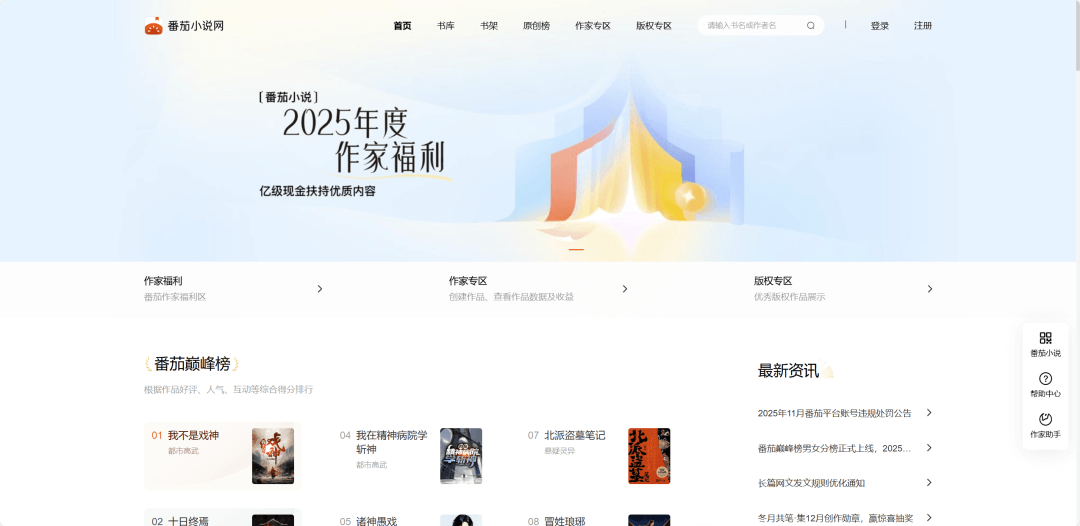
Visual understanding, structural reasoning, and code generation are all done in one step. The generated webpage is basically identical to the original image, and it even recognized and restored the floating window structure in the screenshot! Space for navigation is also reserved for each option in the navigation bar.
02. Some Sharing
Based on hands-on testing, GLM-4.6V can not only recognize details in the image, but also connect the image with the meaning of natural language, understanding what the image is expressing and the relationships between these pieces of information. The whole process is quite smooth.
When using it, it is recommended to keep deep thinking enabled often, as the model's response quality will be higher. When replicating front-end pages, it is recommended to turn off tools. In other cases, customize according to the task or keep the default settings in the official options.
This powerful visual capability will also be integrated into Zhipu's Coding Plan, for as low as only 20 yuan per month, you can directly use the latest model capabilities, which is very cost-effective for daily use.
As this kind of capability gradually matures, visual information will deeply participate in decision-making, planning, and action itself, and scenes from the real world will all become first-class information sources that systems can directly understand and invoke.
The improvement of visual model capabilities is not just giving AI a pair of eyes and a pair of hands, but opening a channel for the next generation of intelligent agents to participate in the real world.
Future robots will no longer need to be precisely programmed to execute a certain action, but will be able to understand natural instructions like "go get the red sweater on the far right side of the wardrobe."
Original link:GLM-4.6V is open-sourced upon release, the strongest domestic multimodal Agent foundation model