
Friends, I recently discoveredthe Qianwen Apphas been updated again.
This time it's a comprehensive upgrade of its creative capabilities, incorporating the latest image model Qwen-Image-Edit 's image generation and editing capabilities,Wan2.5's audio-visual capabilities, with a single image, you can generate high-definition videos where the subject talks, sings, and has precise lip sync.
Ordinary people, who don't know how to edit, can also directly get started and make complete short video content.
01. Hands-on test cases
case 1 Cute pet podcast
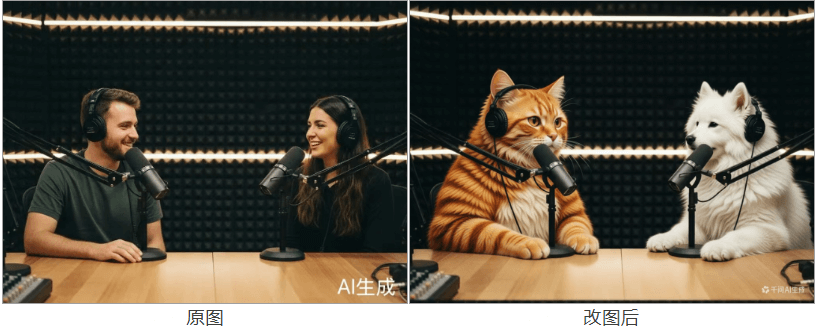
We openthe Qianwen App, upload an image in the chat box, and enter a prompt to directly edit the image. For example, turn the hosts in the image into cute pets.
Prompt: Replace the two hosts in the image with an anthropomorphic orange cat and a white Samoyed, keeping the background unchanged.
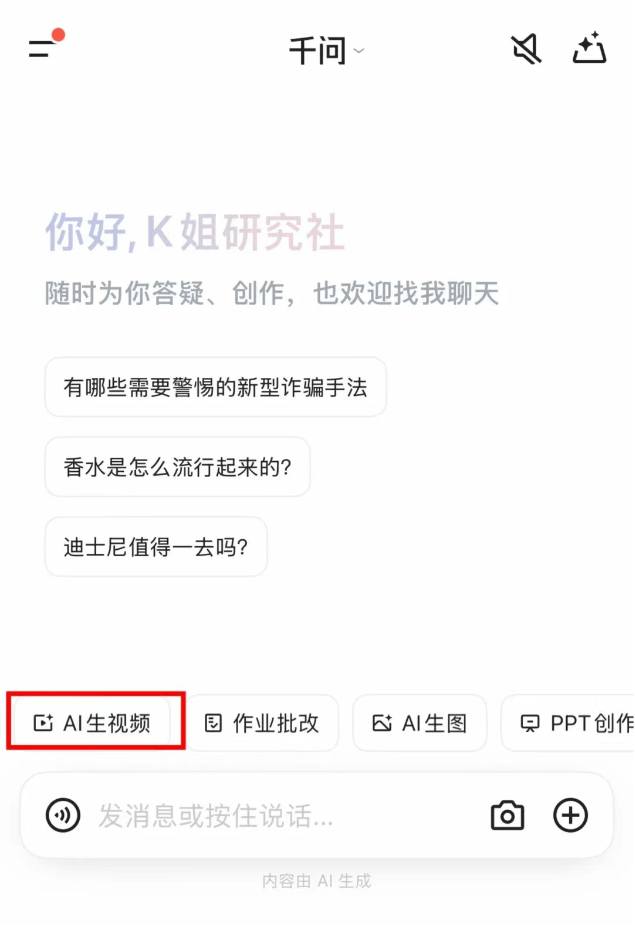
Tap "AI Video Generation" at the bottom, and we can use this image to directly generate an audio-visual synchronized video.
Prompt: A podcast program with an orange cat and a Samoyed. The orange cat gestures excitedly and complains: He says we shed too much hair. The Samoyed thinks and says: We still have hair to shed, he himself is almost bald. After saying this, they look at each other and laugh happily.
Wan2.5 generates different timbres based on the images of the orange cat and the Samoyed respectively, and the lip sync, movements, and expressions are completely synchronized. The subject's lines marked with quotation marks will be generated more accurately.
Let's try again, and the result is also generated in one go:
Prompt: A podcast program with an orange cat and a Samoyed. The Samoyed asks: "Did you hear the owner calling you just now?" The orange cat replies: "I pretended not to hear, so she'll open a can for me." After saying this, the cat and dog laugh together.
In the past, making this kind of short video required first generating the visuals, producing the voiceover, and then matching the lip sync. Videos with multi-subject dialogue were especially troublesome to make. Now, as long as the prompt is clear, a complete video can be generated in one go in less than 5 minutes, and the efficiency improvement is very obvious.
case2 Film and television secondary creation
Prompt: Change the character in image 1 to the pose in image 2.
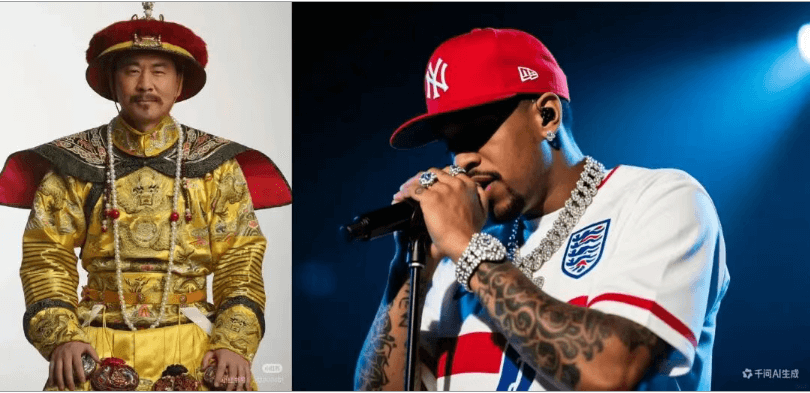
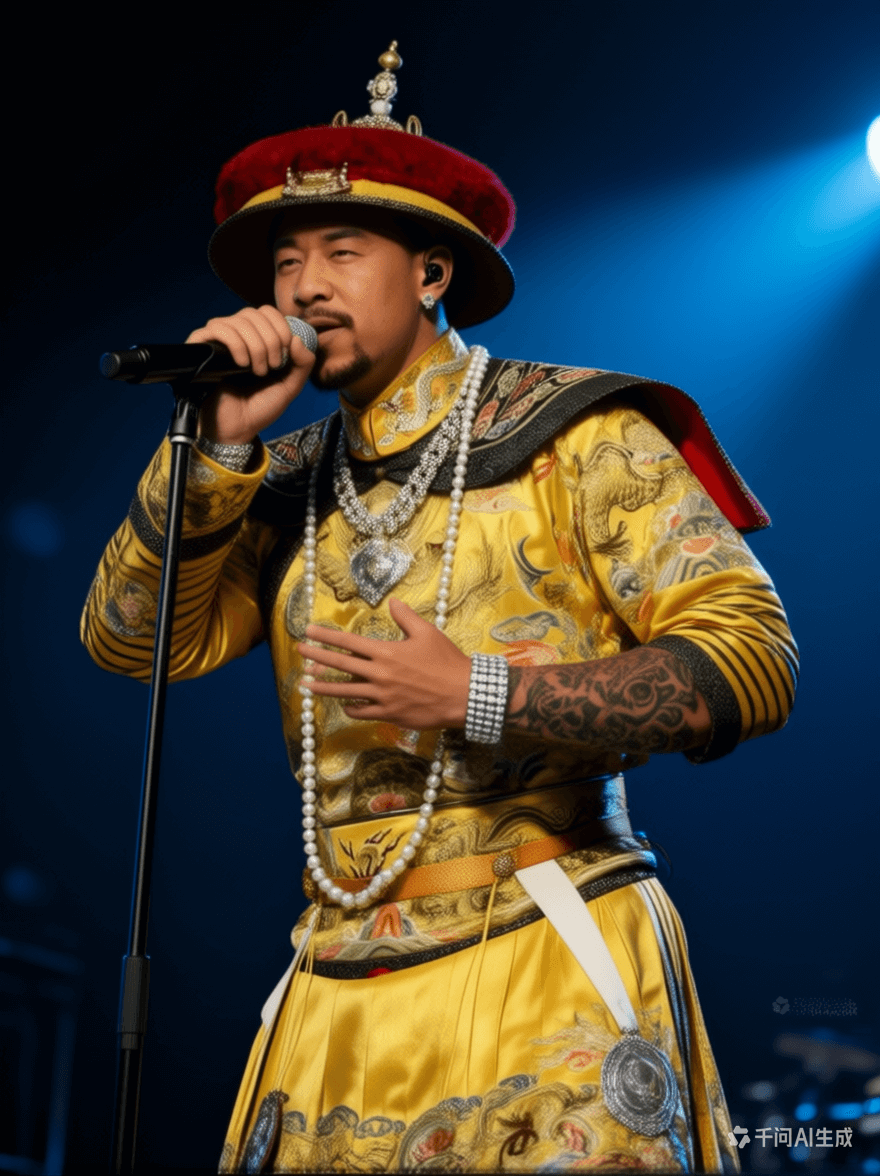
The character consistency is maintained very well. Qwen-Image-Edit not only changed the pose, but also incorporated the character's accessories, tattooed sleeve, and other features from image 2, and the background blends very naturally, with no sense of fragmentation.
Let's continue generating the video:
Prompt: The man in the image performs freestyle in the center of the stage, singing: "The grudges and love-hate affairs of the harem are merely entertainment for me, the emperor, after tea and meals." while dancing to the rhythm.
Wan2.5 has a pretty good understanding of Chinese lyrics and stage performance. The freestyle rap and rhythmic drumbeats are all automatically generated by AI, and the character's lip sync, movements, and rapping tone all match, making the overall performance very coherent.
There is still a small flaw in the microphone stand, but it doesn't affect the overall viewing experience.
case 3 Teaching video
Prompt: The subject in the image explains the English word on the blackboard in the classroom like an English teacher. She says: "This word on the blackboard is Rabbit. It means: rabbit. Read along with me, Rabbit."
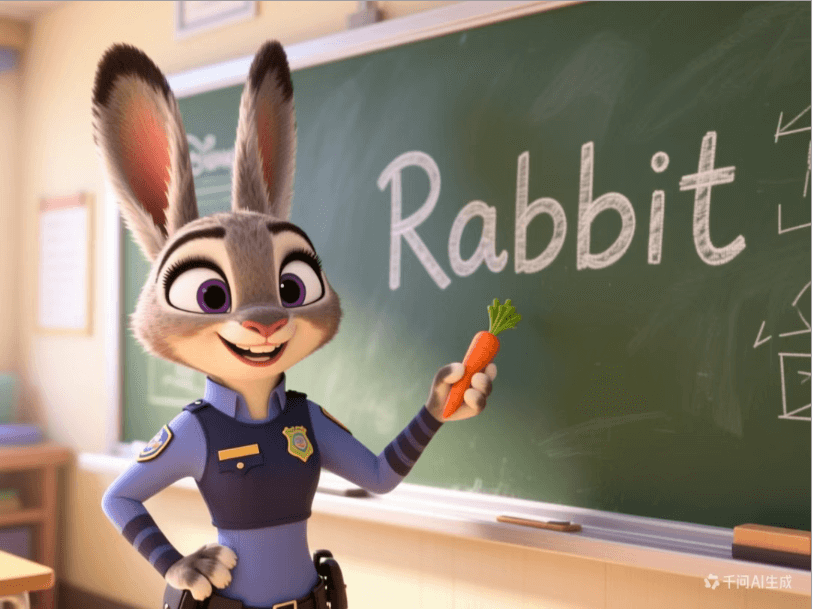
The subject's explaining movements and spoken rhythm are completely synchronized, and the pronunciation is also very standard, so it can be directly used as teaching material.
It can also be adapted into a children's song and sung:
Prompt: The subject in the image is teaching everyone to sing the Little White Rabbit children's song in a classroom like an English teacher. The song content is: "Rabbit, Rabbit, little white rabbit, long long ears and red red eyes, white white fur and soft soft belly."
When the subject sings, the body and ears sway naturally, and the expression is very natural.
case 4 Singing and dancing
Prompt: The kitten spins and jumps, and sings the melody of a children's song: I am the most magical cat.
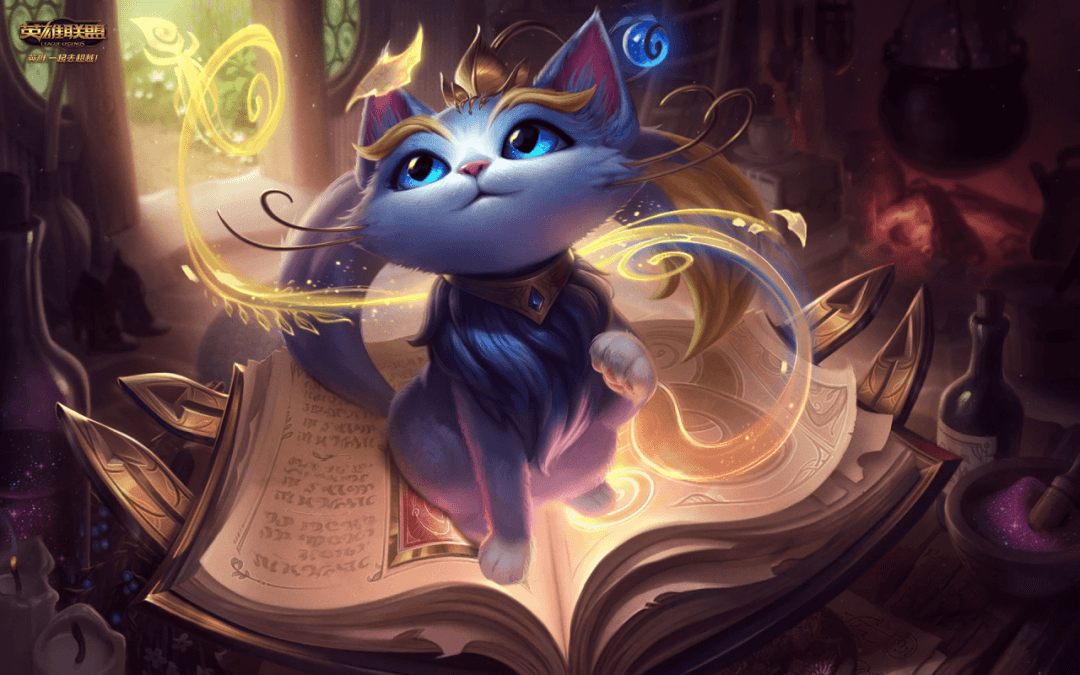
The model recognizes cartoon characters quite accurately~ The timbre is a relatively childish voice, and the children's song melody is purely inferred by the model itself. It sounds a bit "unpleasant," but it really does look fun.
case 5 Absurd meme video
Prompt: The kitten in the image continuously dances repeated dance steps with a mechanical frame-skipping feel, tapping its feet on the ground at high speed. The movements are jerky and mesmerizing, matched with a highly rhythmic dance, while singing in a melodized chanting plus light rap style: "Originally it should have been calm and unhurried, with ease and plenty to spare, but unexpectedly it was hurried and flustered, scrambling and rolling, lying with eyes wide open, what are you choking up about, what are you crying for, useless." The overall style is absurd, bizarre, and brainwashing.
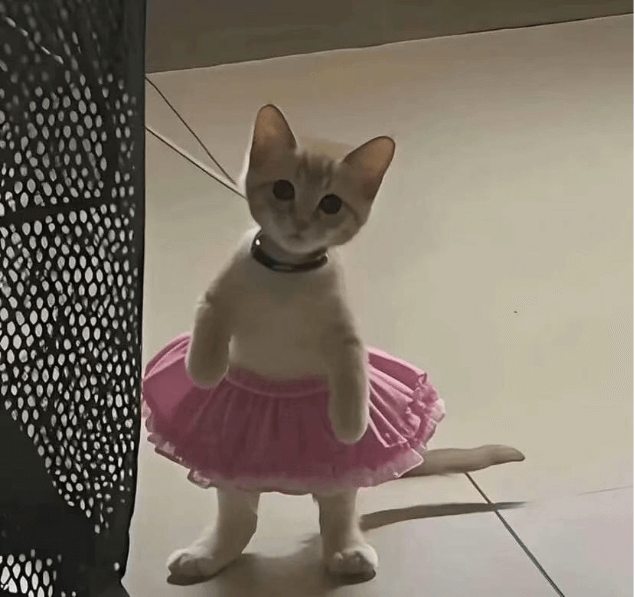
The kitten's movement rhythm is very good. Even the string worn around its neck sways in sync with the rhythm. The details are a big plus. However, Wan2.5 still cannot recognize the original song's melody, but it will infer the melody on its own based on rhythm and style. It is very good at generating abstract, absurd, and funny videos.
case 6 Terracotta Army group dance
Prompt: All the characters in the image sing a children's song while neatly doing campus radio calisthenics.
The lyrics are: "One two three four, stretch out your hands, two two three four, bend at the waist, exercise every day for good health, let's do morning exercises together!"
The song is in a nursery-rhyme style, with a simple and catchy melody and a not-too-high vocal range, suitable for group singing in unison; the rhythm is medium-slow 4/4 time, with clear and steady drumbeats, leaning toward a march rhythm; each line naturally aligns with the movement commands.
The movements include: raising hands, stretching, swinging arms left and right, bending at the waist, and chest expansion exercises. The range is standard and has mechanical consistency, presenting the overall sense of order of campus radio calisthenics. All characters' movements are slow in rhythm and synchronized, giving the feel of campus radio calisthenics.
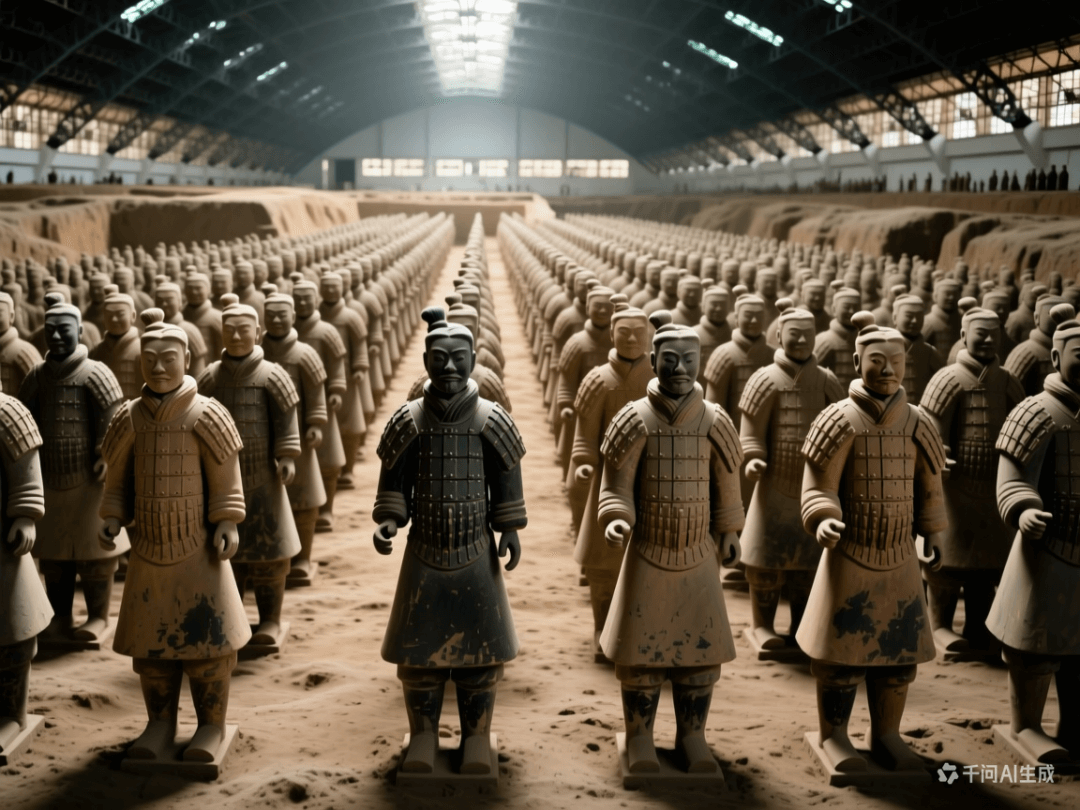
The group movements are very neat, and at the same time they can correspond to the rhythm in the children's song. The overall performance is very stable.
After I added clear style and rhythm prompts, the sense of rhythm improved noticeably, and the generated music also fit the current scene setting better. Controllability is still quite good.
02. Some sharing
The core upgrade of the Qianwen App this time lies in: stronger understanding of prompts and better maintenance of group consistency.
The generated songs are not simply applying templates, but rather the AI's understanding of music, inferring and generating the tune, accompaniment, and timbre on its own, consistent with the rhythm of the subject in the image, making the video overall more harmonious and complete, without the need for secondary processing.
From what we can see so far, the Qianwen App's integrated audio-video generation capability is already relatively mature.
The melody generated by AI is not a tune we are familiar with, but precisely because of this deviation, it instead appears cuter, and it also fits the current content trend of playing with abstraction and memes.
Judging by the speed of AI iteration, today it is only doing abstraction. After a while, the Qianwen App may really become a music master.
More importantly, this upgrade of the Qianwen App brings the core capability of content creation from the web version to the mobile end.
Previously, image-to-video and audio-video synchronization often required working on a computer, but now, pick up your phone, see an interesting scene or come up with an idea, and you can immediately turn it into a highly polished video in the Qianwen App.
This means creation is becoming closer to everyday scenarios: commuting, fragmented time, and moments when inspiration is casually recorded can all become direct entry points for creation.
The core value of creators is also further shifting from production ability to the creativity itself.
Original link:You can now make audio-video synchronized videos on your phone too; this is the tool ordinary people should use.