
What is Yume1.5
Yume1.5 is an interactive world generation model launched by Shanghai Artificial Intelligence Laboratory and Fudan University, among others. It can generate realistic, continuous, and explorable virtual worlds from a single image or text prompt. Through Joint Spatiotemporal Channel Modeling (TSCM) and real-time acceleration strategies, the model addresses the shortcomings of existing models in generality, latency, and text control capability. Yume1.5 supports three modes: Text-to-World, Image-to-World, and text-based event editing, and allows users to control character and camera movement via keyboard. Yume1.5 achieves real-time rendering at 12 FPS on a single GPU, significantly improving interactive performance and offering new possibilities for virtual environments and simulation systems.
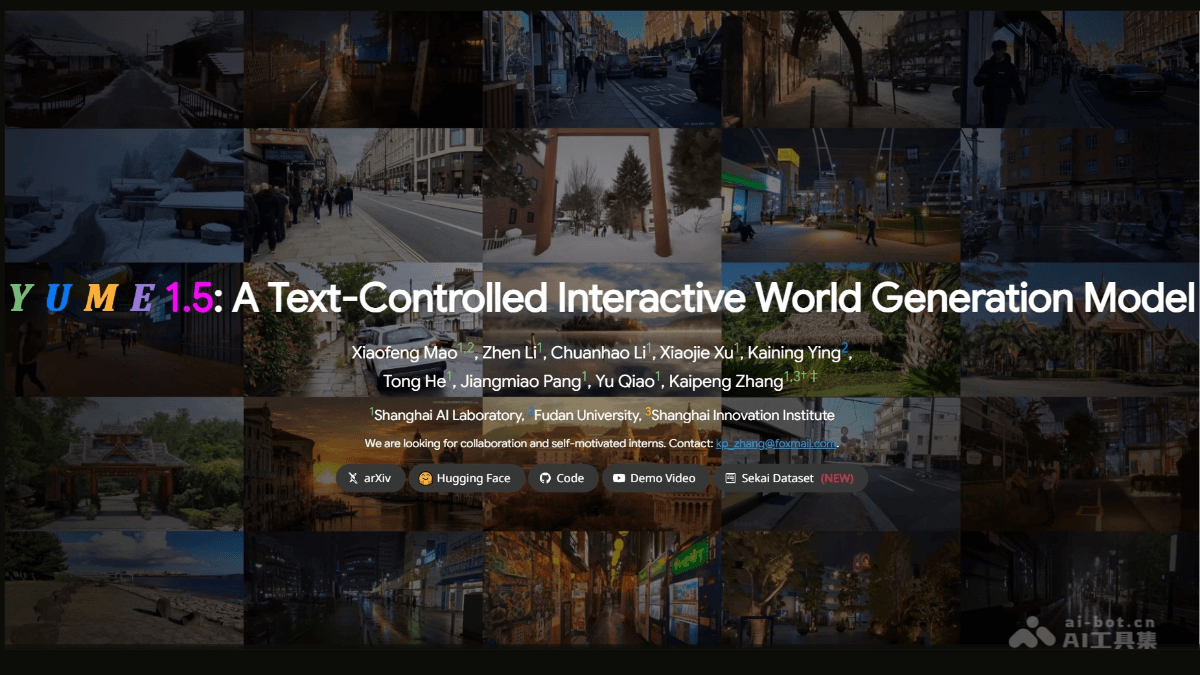
Main features of Yume1.5
- Text-to-World: Supports users in generating corresponding virtual worlds by inputting text descriptions.
- Image-to-World: Based on a single static image, generates a dynamic, explorable virtual world.
- Text-based event editing: Users can trigger specific events through text instructions, such as "a ghost suddenly appears" or "a heavy rainstorm starts," and observe the events occurring in the virtual world in real time.
- Real-time interaction and control: Supports real-time exploration of the virtual world through keyboard input (e.g., WASD keys to control character movement, arrow keys to control camera direction). Users can move freely in the generated world, observe scene changes from different viewpoints, and achieve an immersive experience.
- Long video generation and coherence: The model supports generating infinitely long video content while maintaining temporal and visual coherence. Through Joint Spatiotemporal Channel Modeling (TSCM) and Self-Forcing technology, it addresses the common quality degradation issue in long-sequence generation, ensuring that videos remain stable during long-duration generation.
Technical principles of Yume1.5
-
Joint Spatiotemporal Channel Modeling (TSCM): Yume1.5 adopts Joint Spatiotemporal Channel Modeling technology, reducing the VRAM usage of historical frames through spatiotemporal compression and channel compression. The model downsamples historical frames in the temporal and spatial dimensions, while compressing the channel dimension, and then performs feature fusion through linear attention. This method significantly reduces computational cost while maintaining generation quality, making long video generation more efficient.
-
Real-time acceleration strategy: Yume1.5 combines bidirectional attention distillation (Self-Forcing) and an enhanced text embedding scheme to reduce error accumulation during inference. The model uses its own generated historical frames as conditions for prediction, improving robustness to errors, and by optimizing the training process, achieves fast inference and significantly improves real-time interaction performance.
-
Text-controlled event generation: Yume1.5 decomposes text prompts into "event descriptions" and "action descriptions," processing them separately to reduce computational overhead. Through a mixed dataset training strategy, the model can trigger specific events according to text instructions, enabling text-based event generation capability and enhancing the interactivity and dynamism of the virtual world.
-
System optimization and alternating training paradigm: Yume1.5 adopts a mixed dataset training strategy, combined with an alternating training paradigm, to simultaneously achieve world generation and editing capabilities. During training, the model alternates between processing text-to-video and image-to-video tasks, improving comprehensive performance on different tasks and providing stronger support for generating complex real-world scenarios.
Project address for Yume1.5
- Project Website:https://stdstu12.github.io/YUME-Project/
- GitHub Repository:https://github.com/stdstu12/YUME
- HuggingFace Model Hub:https://huggingface.co/stdstu123/Yume-5B-720P
- arXiv Technical Paper:https://arxiv.org/pdf/2512.22096
Application Scenarios of Yume1.5
- Virtual Reality and Augmented Reality (VR/AR): Yume1.5 can generate immersive virtual worlds, supporting users to freely explore and interact through VR/AR devices, suitable for virtual tourism, education, and entertainment experiences.
- Game Development: Yume1.5 can generate and edit dynamic game scenes in real time for game developers, supporting text instructions to trigger specific events, enhancing the diversity and playability of games.
- Film and Television Production: The model can be used for rapid generation of virtual scenes and special effects in film and television post-production, generating specific environments through text descriptions, reducing production costs and time.
- Architectural Design and Urban Planning: Yume1.5 can generate dynamic urban environments based on design drawings or text descriptions, helping architects and planners conduct virtual walkthroughs and scheme evaluations.
- Education: Yume1.5 can generate virtual content such as historical scenes and scientific experiment environments, providing students with immersive learning experiences.