
What is Yuan 2.0-M32
Yuan 2.0-M32 is a Mixture of Experts (MoE) model with 32 experts launched by Inspur. It adopts the innovative "Attention Router" technology, improving the efficiency and accuracy of the model's expert selection. The model has a total parameter count of 4 billion, while its training computation consumption is only 1/16 that of dense models of the same scale. Yuan 2.0-M32 demonstrates outstanding performance in multiple fields such as code generation, mathematical problem solving, and scientific reasoning, surpassing other models on the ARC-C and MATH benchmarks.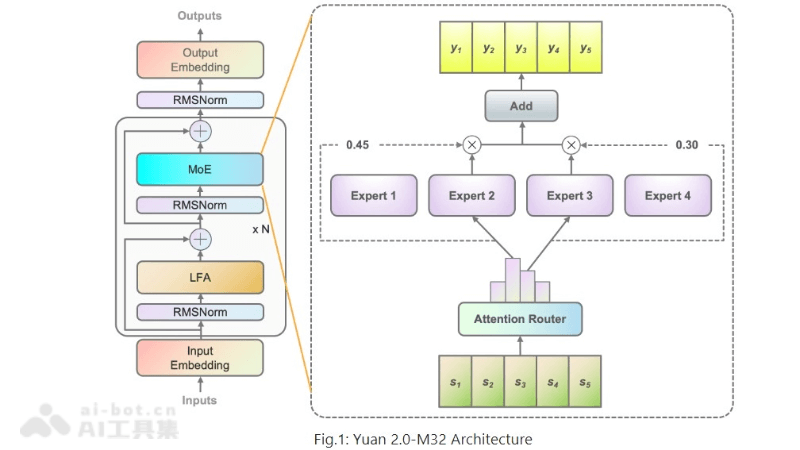
Main features of Yuan 2.0-M32
- Mixture of Experts (MoE) architecture: It uses 32 experts, activating 2 at a time, effectively improving the model's computational efficiency and accuracy.
- Attention Router: A novel routing network that improves the model's accuracy by considering the correlations between experts.
- Multi-domain capabilities: It demonstrates a high level of competitiveness in multiple fields such as programming, mathematical problem solving, scientific reasoning, and multi-task language understanding.
- Efficient computation: Despite the model's large scale, the active parameters and computational consumption are low, ensuring the efficiency of model operation.
Technical principles of Yuan 2.0-M32
- Attention Router: Unlike traditional routing algorithms, Attention Router introduces an attention mechanism to consider the collaborative relationships between different experts, optimizes the expert selection process, and improves the model's accuracy.
- Localized Filtering-based Attention (LFA): LFA enhances the model's ability to understand local and global features of natural language by learning the local dependencies between input tokens.
- Efficient training strategy: It combines data parallelism and pipeline parallelism training methods, avoiding the use of tensor parallelism or optimizer parallelism, and reducing communication overhead during training.
- Refined fine-tuning method: During the fine-tuning stage, the model supports longer sequence lengths and adjusts the base frequency value of RoPE (Rotary Position Embedding) as needed to adapt to longer contexts.
Project addresses of Yuan 2.0-M32
- GitHub repository:https://github.com/IEIT-Yuan/Yuan2.0-M32
- HuggingFace model library:https://huggingface.co/IEITYuan
- arXiv technical paper:https://arxiv.org/pdf/2405.17976
How to use Yuan 2.0-M32
- Environment preparation:Ensure a hardware environment suitable for running large language models, such as high-performance GPUs.
- Obtain the model:Visit the open-source GitHub link provided by Inspur, and download the "Yuan 2.0-M32" model and related code.
- Install dependencies:Install all dependency libraries required to run the model, such as PyTorch, Transformers, etc.
- Model loading:Use the appropriate API or script to load the pre-trained "Yuan 2.0-M32" model into memory.
- Data preparation:Prepare input data according to the application scenario, which may include text, code, or other forms of data.
- Model invocation:Pass the input data to the model, and call the model's prediction or generation function.
- Result processing:Receive the results output by the model, and perform post-processing or analysis as needed.
Application scenarios of Yuan 2.0-M32
- Code generation and understanding: Help developers quickly generate code through natural language descriptions, or understand the functionality of existing code.
- Mathematical problem solving: Automatically solve complex mathematical problems, providing detailed solution steps and answers.
- Scientific knowledge reasoning: Perform knowledge reasoning within the scientific domain, helping analyze and solve scientific problems.
- Multilingual translation and understanding: Supports translation work between Chinese and English, helping with cross-language communication and content understanding.