
What is XVerse
XVerse is a new type of multi-subject controlledimage generationmodel launched by ByteDance's Intelligent Creation team. In the field of text-to-image generation, the model achieves fine-grained control over multiple subject identities and semantic attributes (such as pose, style, and lighting) while maintaining the high quality and consistency of the generated images. XVerse converts reference images into token-specific text stream modulation offsets, achieving precise and independent control over specific subjects without interfering with image latent variables or features. The model introduces a VAE-encoded image feature module and regularization techniques to enhance detail preservation capability and generation quality. XVerse provides high fidelity and editability in multi-subject controlled image synthesis, and can perform powerful control over individual subject features and semantic attributes.
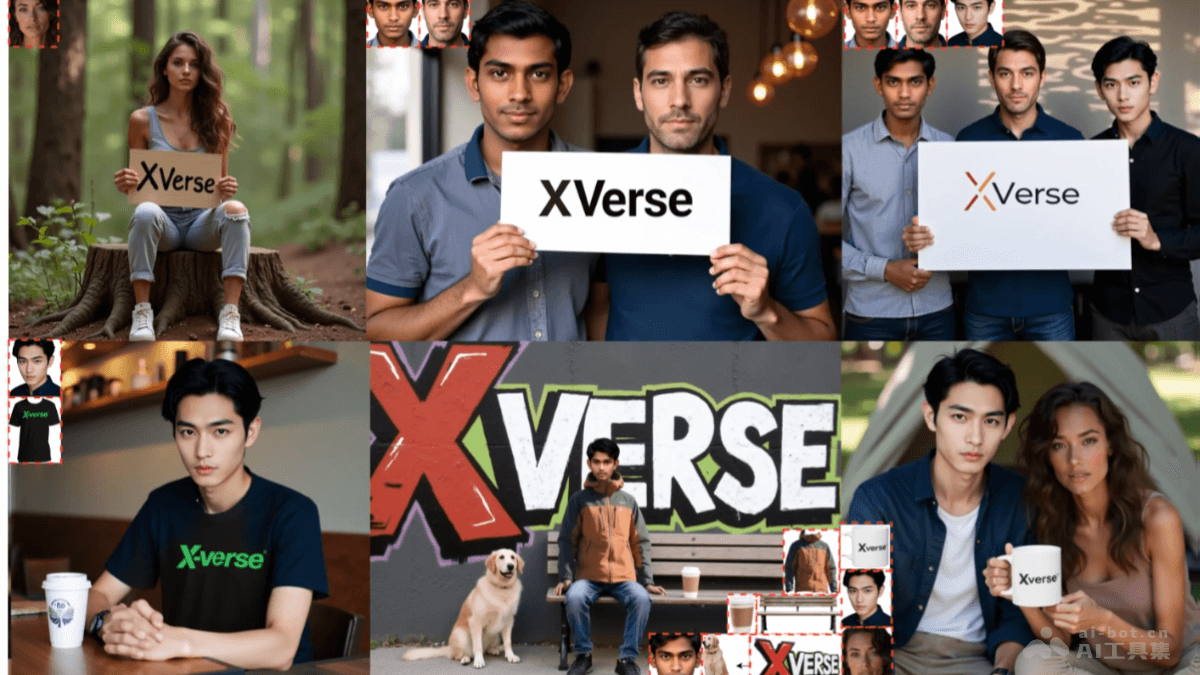
Main features of XVerse
- Multi-subject control: XVerse can simultaneously control the identities and semantic attributes of multiple subjects, for example, simultaneously controlling the identities, poses, styles, etc. of multiple characters in one image, enabling complex scene generation.
- High-fidelity image synthesis: The generated images have high fidelity, accurately reflecting the details and semantic information in the text description while maintaining the overall quality and consistency of the image.
- Semantic attribute control: Supports fine-grained control over semantic attributes (such as pose, style, and lighting), enabling flexible adjustment of image style and atmosphere.
- Powerful editability: Users can edit and adjust the generated images based on simple text prompts, enabling personalized image creation.
- Reduce artifacts and distortion: By introducing a VAE-encoded image feature module and regularization techniques, XVerse can significantly reduce artifacts and distortion in generated images, improving the naturalness and visual effect of the images.
Technical principles of XVerse
- Text-stream Modulation Mechanism: Converts reference images into token-specific text stream modulation offsets to achieve precise control over specific subjects. The offsets are added to the model's text embeddings, enabling fine-grained control over the generated image without interfering with image latent variables or features.
- VAE-encoded image feature module: To enhance the detail preservation capability of generated images, XVerse introduces a VAE-encoded image feature module. The image feature module serves as an auxiliary module, helping the model retain more detailed information during the generation process and reduce artifacts and distortion.
- Regularization techniques: Based on randomly preserving modulation injection on one side, it forces the model to maintain consistency in non-modulated regions. It regularizes subject-specific features as a data augmentation strategy for multi-subject datasets, improving the model's ability to distinguish and preserve subject features in multi-subject scenarios. Based on the L2 loss between the computed modulation model and the text-image cross-attention maps of the reference T2I branch, it ensures that the modulation model retains attention patterns consistent with the T2I branch, maintaining consistency and editability of semantic interactions.
- Training data: XVerse is trained with a high-quality multi-subject controlled training dataset. The dataset uses Florence2 for image captioning and phrase grounding, and SAM2 for precise face extraction, constructing high-quality training data containing multiple subjects and scenes. The training data covers a variety of scenarios, including human-object interactions, human-animal combinations, and complex multi-person scenes, enhancing the model's generalization ability.
XVerse's project address
- Project Website:https://bytedance.github.io/XVerse/
- GitHub Repository:https://github.com/bytedance/XVerse
- HuggingFace Model Library:https://huggingface.co/ByteDance/XVerse
- arXiv Technical Paper:https://arxiv.org/pdf/2506.21416
XVerse Application Scenarios
- E-commerce Advertising Generation: Quickly generate advertising images of different people using the same product for e-commerce promotional campaigns, meeting brand personalization needs.
- Game Character Design: Generate multiple character concept art with unique appearances and skills based on game designers' descriptions, accelerating the character design process.
- Medical Education Illustration: Generate detailed human anatomy and physiology diagrams to help medical students better understand human body structure and function.
- Personal Avatar Customization for Virtual Social Platforms: Users input descriptions to generate personalized virtual avatars, used as profile pictures on virtual social platforms or personal avatars in virtual reality.
- Urban Planning Scheme Presentation: Generate virtual renderings of urban parks to help citizens better understand urban planners' design schemes.