
What is xGen-MM
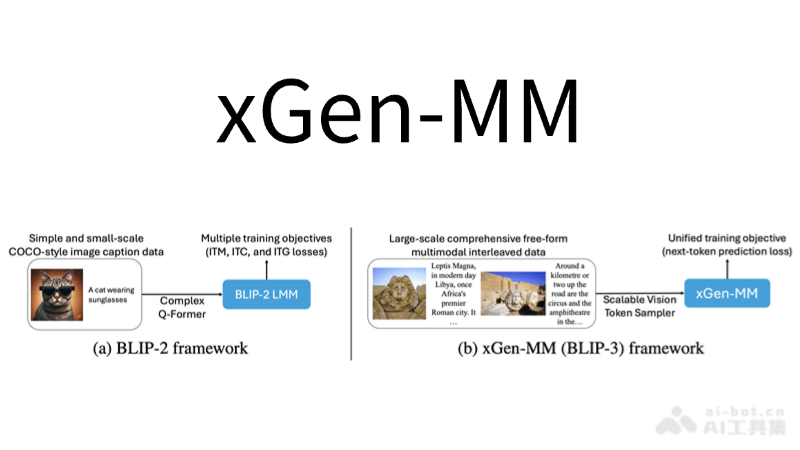
xGen-MM is an open-source multimodal AI model released by Salesforce, capable of processing interleaved data and simultaneously understanding and generating multiple data types such as text and images. By learning from large amounts of image and text information, xGen-MM not only demonstrates strong performance on visual-language tasks, but also promotes continuous improvement of model capabilities through open-source models, datasets, and fine-tuning codebases.
Main Features of xGen-MM
- Multimodal Understanding: xGen-MM can simultaneously process and understand image and text information, and supports answering questions about visual content.
- Large-Scale Data Learning: Trained on large amounts of diverse data, xGen-MM can capture rich visual and language patterns.
- High-Performance Generation: xGen-MM can not only understand input information, but also generate text, such as writing descriptions or answers based on an image.
- Open-Source and Accessible: xGen-MM's models, datasets, and code are open source, allowing researchers and developers to freely access and use these resources to build their own applications.
- Fine-Tuning Capability: Users can fine-tune xGen-MM according to their specific needs to adapt to different application scenarios.
xGen-MM Project Addresses
- GitHub Repository:https://github.com/salesforce/LAVIS/tree/xgen-mm
- Hugging Face Model Library:https://huggingface.co/Salesforce/xgen-mm-phi3-mini-instruct-interleave-r-v1.5
- arXiv Technical Paper:https://arxiv.org/pdf/2408.08872
Technical Principles of xGen-MM
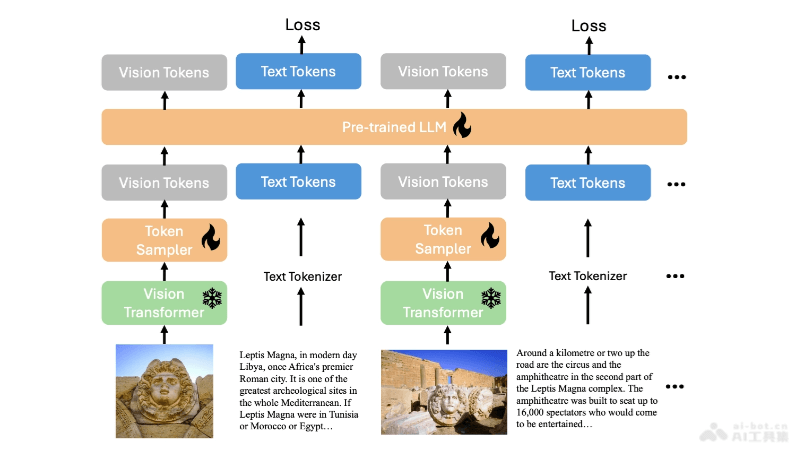
- Multimodal Learning: xGen-MM is trained to simultaneously understand image and text data, achieving fusion of visual and language information.
- Large-Scale Datasets: The model is trained on large-scale, diverse datasets containing rich images and corresponding descriptions.
- Visual Token Sampler: xGen-MM uses an efficient visual token sampler (such as the Perceiver architecture) to process image data, enabling the model to handle images of different resolutions in a scalable way.
- Pre-Trained Language Model: It combines a pre-trained large language model (such as the Phi-3 model), which has already been trained on large amounts of text data and has strong language understanding capabilities.
- Unified Training Objective: It simplifies the training process by training the model with a single autoregressive loss function, focusing on predicting text tokens in multimodal contexts.
- Instruction Fine-Tuning: The model can better understand and execute user queries through instruction fine-tuning, with additional training on the pre-trained model for specific tasks.
- Post-Training Optimization: This includes Direct Preference Optimization (DPO) and safety fine-tuning to improve the model's usefulness, reduce hallucination effects, and improve safety.
- Open Source and Customizability: xGen-MM's code, models, and datasets are all open source, allowing community members to customize and further develop them according to their needs.
Application Scenarios of xGen-MM
- Image Caption Generation: Automatically generates descriptive text for images, suitable for social media, photo album management, and more.
- Visual Question Answering: Answers questions about image content, such as providing product information in education or e-commerce.
- Document Understanding: Parses and understands images and text in documents, suitable for automated document processing and information retrieval.
- Content Creation: Assists users during the creation process, such as automatically generating storyboards, designing concept art, etc.
- Information Retrieval: Through the combination of images and text, improves the relevance and accuracy of search results.