
What is xbench
xbench is a brand-new AI benchmarking tool launched by Sequoia China. Based on a dual-track evaluation system, it builds multi-dimensional evaluation datasets to track the theoretical capability ceiling of models and the actual deployment value of Agents. xbench uses an evergreen evaluation mechanism to dynamically update test content, ensuring timeliness and relevance. The first two core evaluation sets launched by xbench are the science question answering evaluation set and the Chinese internet deep search evaluation set. xbench is committed to providing scientific, long-term evaluation guidance for AI technology breakthroughs and product iteration, and promoting the improvement of the utility value of AI systems in real-world scenarios.
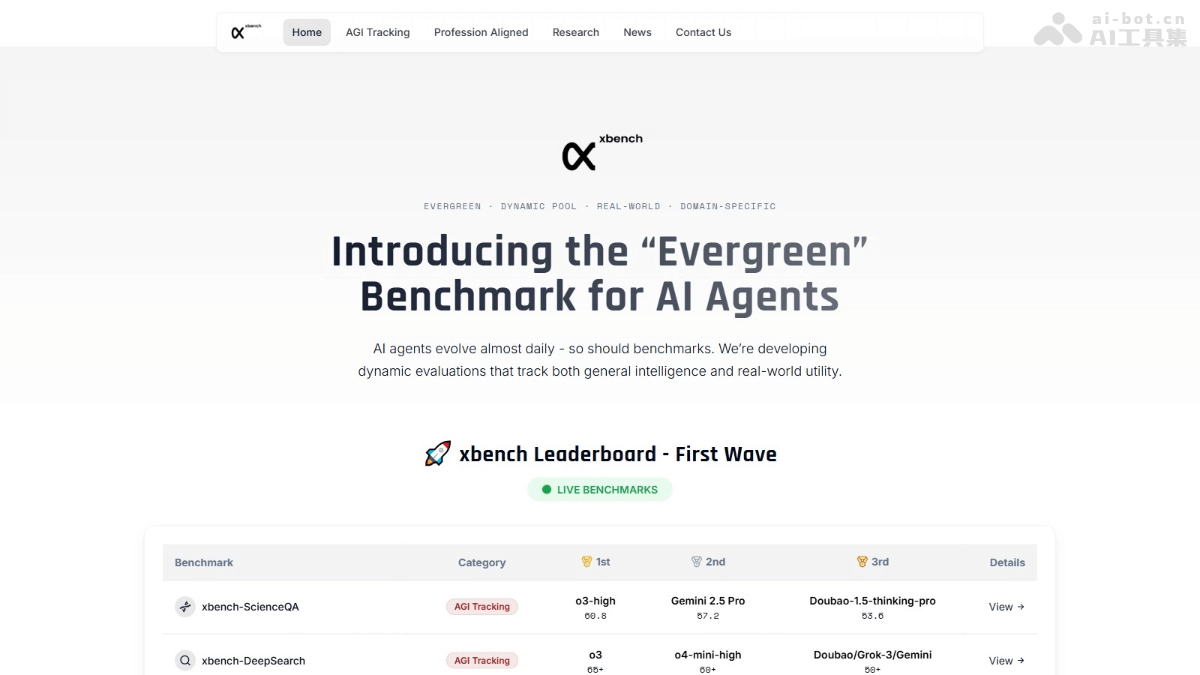
Main features of xbench
- Dual-track evaluation: On one hand, it evaluates the capability ceiling and technical boundaries of AI systems; on the other hand, it quantifies the utility value of AI systems in real-world scenarios.
- Evergreen evaluation mechanism: Dynamically updates test content to ensure the timeliness and relevance of evaluation, avoid overfitting and evaluation failure caused by question leakage, track the evolution of model capabilities, and capture key breakthroughs in Agent product iteration.
- Core evaluation sets: Launches two core evaluation sets, xbench-ScienceQA (testing subject knowledge and reasoning ability) and xbench-DeepSearch (examining deep search capability), with questions updated quarterly or monthly.
- Vertical domain agent evaluation: Builds tasks, execution environments, and validation methods aligned with expert behavior, such as in recruitment and marketing, annotates the economic value of tasks, and presets technology-market fit targets.
- Real-time updates and LeaderBoard: Updates evaluation results in real time, displays the performance of different Agent products on each evaluation set, and provides reference for developers and researchers.
xbench official website address
- Project address:https://xbench.org/
- GitHub repository:https://github.com/xbench-ai/xbench-evals
- HuggingFace model library:
- https://huggingface.co/datasets/xbench/ScienceQA
- https://huggingface.co/datasets/xbench/DeepSearch
Application scenarios of xbench
- Model capability evaluation: Helps developers of foundation models and Agents evaluate the theoretical capability ceiling and technical boundaries of products, explore the intelligence boundaries of models, and provide guidance for technical iteration.
- Real-world utility quantification: Quantifies the utility value of AI systems in real-world scenarios, such as the practical application value in marketing, recruitment, and other fields, helping enterprises evaluate the commercial potential of AI tools.
- Product iteration guidance: Tracks key breakthroughs in Agent products and provides real-time feedback and directional guidance for continuous product iteration and optimization.
- Industry standard establishment: Collaborates with industry experts to build dynamic evaluation sets for specific industries, promotes the deployment and application of Agents in more vertical domains, and establishes evaluation standards for AI applications across industries.
- Technology-market fit: Analyzes the cost-effectiveness of Agents, predicts technology-market fit points, provides forward-looking guidance for the market and developers, and accelerates the commercialization process of AI technology.