
What is X-Prompt
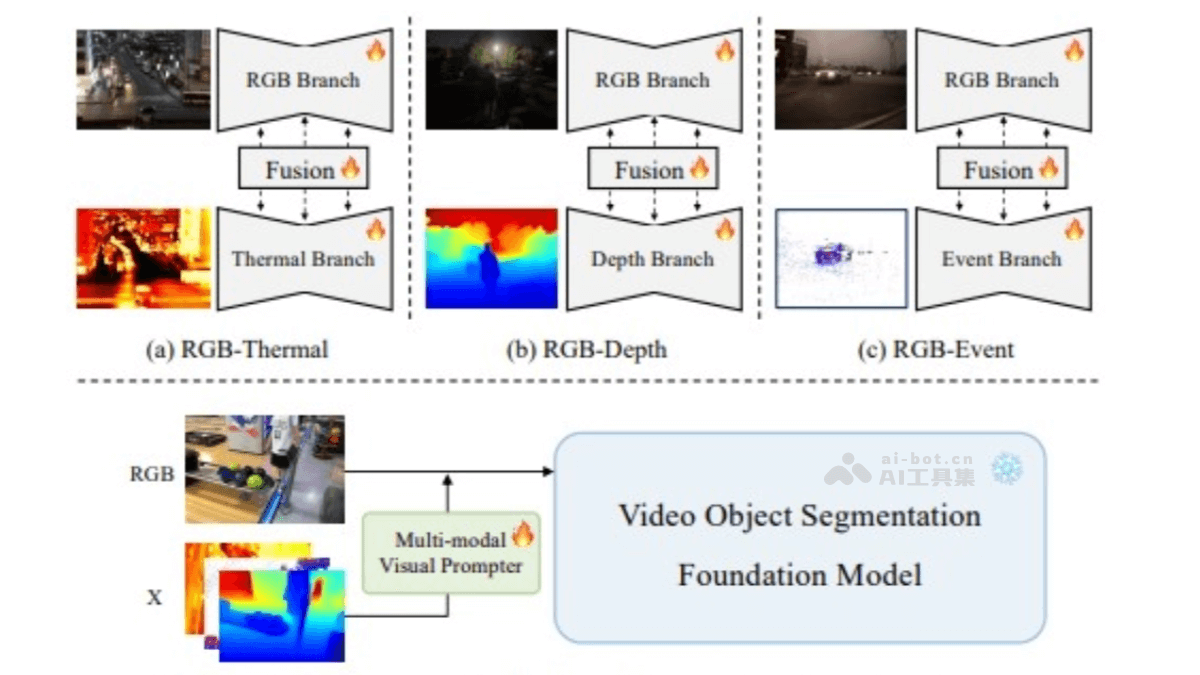
X-Prompt is a general framework for multimodal video object segmentation that addresses the limitations of traditional methods in complex scenarios such as extreme lighting, fast motion, and background interference. By pretraining a video object segmentation foundation model based on RGB data, it uses additional modal information (such as thermal imaging, depth, or event camera data) as visual prompts to adapt the foundation model to downstream multimodal tasks.
Main Features of X-Prompt
- Multimodal Adaptation: X-Prompt uses a Multimodal Visual Prompter (MVP) to encode additional modal information into visual prompts, which are combined with RGB data to enhance the foundation model's segmentation capability in multimodal tasks.
- Preserving Generalization Ability: Through Multimodal Adaptation Experts (MAEs), X-Prompt provides modality-specific knowledge for each modality without compromising the foundation model's generalization ability, avoiding the model collapse that can result from full-parameter fine-tuning.
- Efficient Task Transfer: It can quickly adapt to new downstream tasks with limited multimodal annotated data, reducing the research effort and hardware cost of designing and training a separate model for each task.
- Multi-Task Integration: X-Prompt supports multiple multimodal tasks (such as RGB-T, RGB-D, and RGB-E), achieving task integration through a unified framework and significantly improving model performance in complex scenarios.
Technical Principles of X-Prompt
- Foundation Model Pretraining: X-Prompt's foundation model is a video object segmentation model based on Vision Transformer, pretrained on a large number of RGB video sequences to acquire strong segmentation and generalization capabilities. The goal of the pretraining stage is to enable the model to segment the target object in the current frame based on the reference frame and its segmentation mask.
- Multimodal Visual Prompter (MVP): The role of MVP is to encode information from additional modalities (such as thermal imaging, depth, or event camera data) into visual prompts and integrate them into the foundation model. Through a multi-scale convolutional embedding layer, MVP embeds RGB and X-modality image patches into multi-scale prompts, which are used to guide the foundation model in object segmentation.
- Multimodal Adaptation Experts (MAE): MAE provides modality-specific knowledge for each modality through a low-rank adaptation mechanism while preserving the foundation model's general capabilities.The design of MAE supports fine-tuning the model to adapt to specific multimodal tasks without compromising the foundation model's generalization ability.
Project Address of X-Prompt
- arXiv Technical Paper:https://arxiv.org/pdf/2409.19342
Application Scenarios of X-Prompt
- Autonomous Driving: By combining thermal imaging and depth information, X-Prompt can more accurately identify and segment targets on the road, improving the safety of autonomous driving systems.
- Robot Vision: In complex environments, multimodal information can help robots more accurately recognize and manipulate target objects.
- Video Surveillance: In surveillance scenarios with low light or complex backgrounds, X-Prompt can use multimodal data to improve the accuracy of target detection and segmentation.