
What is X-Dancer
X-Dancer is a music-driven portrait dancevideo generationframework jointly introduced by researchers from ByteDance, the University of California San Diego, and the University of Southern California. It supports the generation of diverse and realistic full-body dance videos from a single static image. X-Dancer combines autoregressive Transformers and diffusion models, uses 2D human pose modeling, and captures the complex alignment between dance movements and music rhythm based on widely available monocular video data. X-Dancer uses a multi-part 2D pose representation and a confidence-aware quantization method to generate dance pose sequences synchronized with music, and based on a diffusion model, transforms the pose sequences into coherent video frames. X-Dancer outperforms existing methods in motion diversity, music alignment, and video quality, can adapt to reference images of different body types and styles, and supports zero-shot generation and fine-tuning for specific choreography.
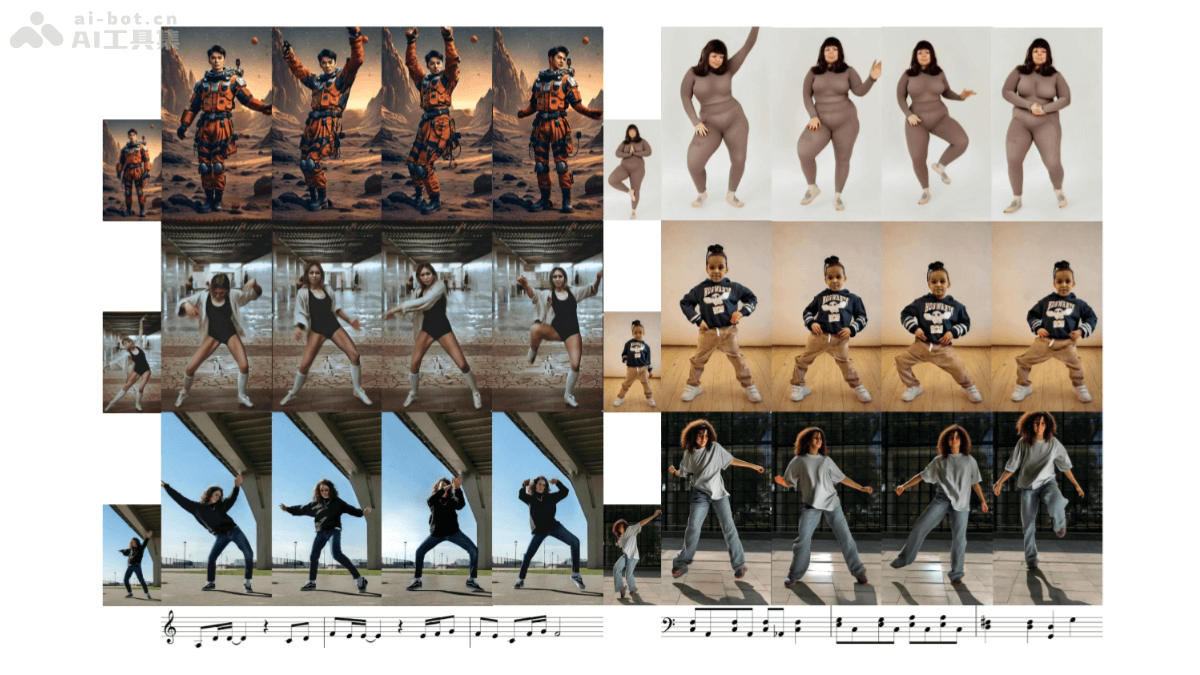
X-Dancer's Main Features
- Generate Dance Videos from a Single Static Image: Use one person image and a piece of music to generate a full-body dance video synchronized with the music rhythm.
- Diverse and Personalized Dance Movements: Support the generation of multiple styles and complex movements, including detailed movements such as the head and hands, and support animation of people with different body types and styles.
- Music Rhythm Alignment: Dance movements are closely synchronized with the music rhythm, capturing the beat and style of the music.
- Zero-Shot Generation and Customization: Support zero-shot generation and fine-tuning for specific choreography styles to adapt to different dance needs.
- High-Quality Video Synthesis: The generated dance videos have high resolution and realistic visual effects while maintaining consistency with the reference image.
X-Dancer's Technical Principles
- Pose Modeling: Extract dance movements from monocular videos based on 2D human pose estimation, avoiding the complexity and data limitations of 3D pose estimation.
- Multi-Part Pose Quantization: Divide the human body into multiple parts (such as upper body, lower body, head, and hands), separately encode and quantize them into pose tokens, and combine them into a complete pose based on a shared decoder.
- Autoregressive Transformer: Use a GPT-like autoregressive model to predict future pose token sequences based on music features and historical pose information, achieving synchronization with the music.
- Diffusion Model Synthesis: Convert the generated pose tokens into spatial guidance signals using a trainable motion decoder, and combined with reference image features, generate coherent dance videos based on a diffusion model.
- AdaIN and Spatiotemporal Modules: Use adaptive instance normalization (AdaIN) and spatiotemporal modules to ensure the spatiotemporal coherence and identity consistency of the generated videos.
X-Dancer's Project Address
- arXiv Technical Paper:https://arxiv.org/pdf/2502.17414
X-Dancer's Application Scenarios
- Social Media Sharing: Users transform photos and music into personalized dance videos, increasing the fun of content on social platforms.
- Virtual Character Animation: Generate synchronized dance movements for characters in virtual reality and the metaverse, enhancing expressiveness.
- Music Game Interaction: Generate dance movements in real time, enhancing the visual effects and interactivity of music rhythm games.
- Advertising: Combine brand music to generate dance videos, use them in advertising and promotion, and attract user attention.
- Dance education: Generate dance videos in different styles to assist dance teaching or showcase cultural characteristics.