
What is X-AnyLabeling
X-AnyLabeling is an image annotation software that integrates multiple deep learning algorithms, focusing on improving annotation efficiency and accuracy. X-AnyLabeling supports diverse annotation styles for images and videos, adapts to various AI training scenarios, and provides image-level and object-level label classification. The software supports importing and exporting data formats from mainstream deep learning frameworks, offers cross-platform compatibility, and supports CPU and GPU inference. The new version X-AnyLabeling v2.5.0 especially strengthens small object screening functionality and introduces interactive detection and segmentation annotation algorithms based on visual-text prompts, making it suitable for various visual tasks in academia and industry and a powerful tool in the field of image annotation.
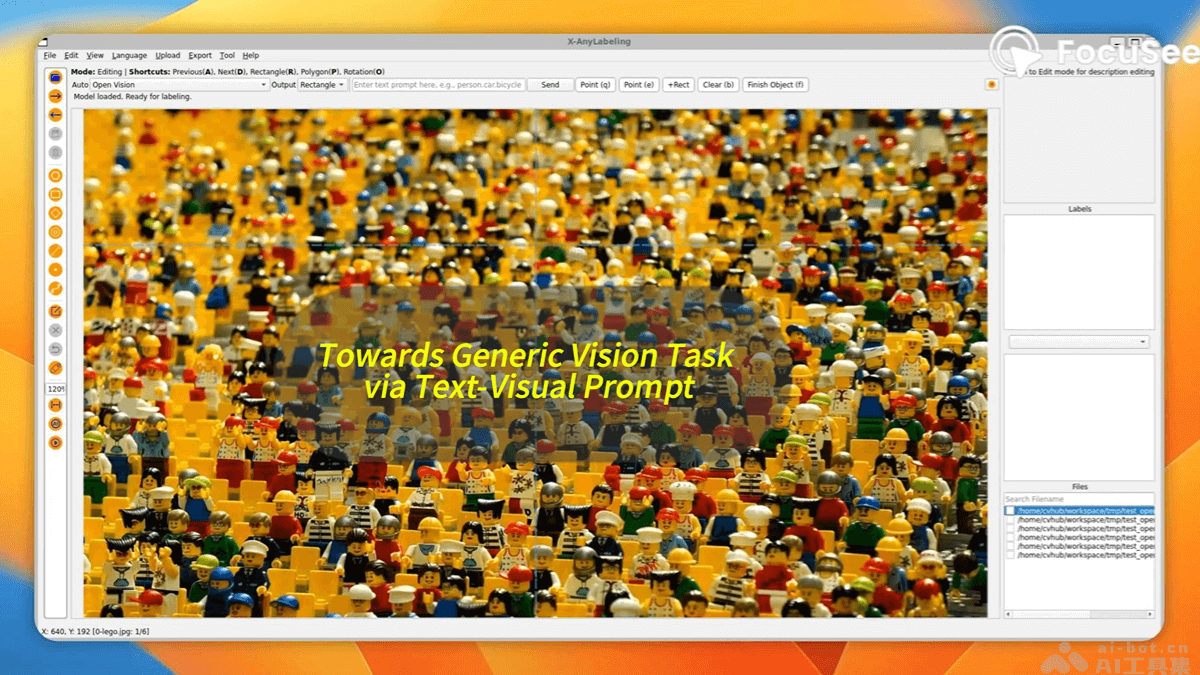
Main features of X-AnyLabeling
- Diverse annotation styles: Supports multiple annotation styles such as rectangles, polygons, rotated boxes, points, line segments, polylines, and circles, suitable for different scenarios such as object detection and image segmentation.
- Image-level and object-level label classification: Suitable for subtasks such as image classification, image captioning, and image tagging.
- Multi-format data conversion: Supports importing and exporting data formats for deep learning frameworks such as YOLO, OpenMMLab, and PaddlePaddle.
- Cross-platform and multi-hardware support: Runs on Windows, Linux, and MacOS operating systems, and supports CPU and GPU inference.
- Object screening functionality: Provides a screening function that iterates through sub-images, improving the quality and efficiency of small object annotation.
- Interactive detection and segmentation annotation based on visual-text prompts: The new algorithm Open Vision combines the advantages of Visual-Text Grounding and Segment-Anything.
Technical principles of X-AnyLabeling
- Deep learning algorithm integration: Integrates multiple deep learning models, such as the YOLO series and RT-DETR series, to perform tasks such as object detection and image segmentation.
- Visual-text prompt fusion: Based on algorithms such as Open Vision, combines natural language prompts with visual input to improve the intelligence and intuitiveness of task processing.
- Multimodal foundation models: Uses models such as Florence 2 to achieve unified architecture processing of visual and language understanding.
- Interactive segmentation technology: Based on the Segment Anything 2 algorithm, enables interactive image segmentation.
- Cross-platform framework adaptation: Adapts to data formats of different deep learning frameworks to achieve cross-platform data compatibility and use.
- Hardware-accelerated inference: Based on GPU-accelerated inference, improves model operation efficiency.
Project address of X-AnyLabeling
- GitHub repository:https://github.com/CVHub520/X-AnyLabeling
Application scenarios of X-AnyLabeling
- Autonomous driving: Used in tasks such as vehicle detection, pedestrian detection, lane line detection, and traffic sign recognition in autonomous driving systems to improve system safety and accuracy.
- Security monitoring: Performs object detection and multi-object tracking in video surveillance, used for abnormal behavior analysis, crowd counting, and more.
- Medical imaging analysis: Based on image segmentation technology, assists doctors in identifying and analyzing lesion areas, improving diagnostic accuracy.
- Industrial inspection: In manufacturing, used for product quality inspection, such as defect detection and foreign object detection.
- Agricultural automation: In precision agriculture, used for crop disease detection, yield assessment, etc.