
What is WhisperLiveKit
WhisperLiveKit is an open-source real-timespeech recognitiontool that can transcribe speech into text in real time and supports speaker recognition. The tool is based on advanced technologies such as SimulStreaming and WhisperStreaming, providing ultra-low-latency transcription capabilities. The tool processes speech data entirely locally, ensuring privacy and security. WhisperLiveKit supports multiple languages and can be started quickly with a simple command, providing a web interface and Python API for the convenience of developers and ordinary users. WhisperLiveKit is suitable for scenarios such as meetings, subtitle generation, and accessibility assistance, making it an ideal choice for real-time speech recognition.
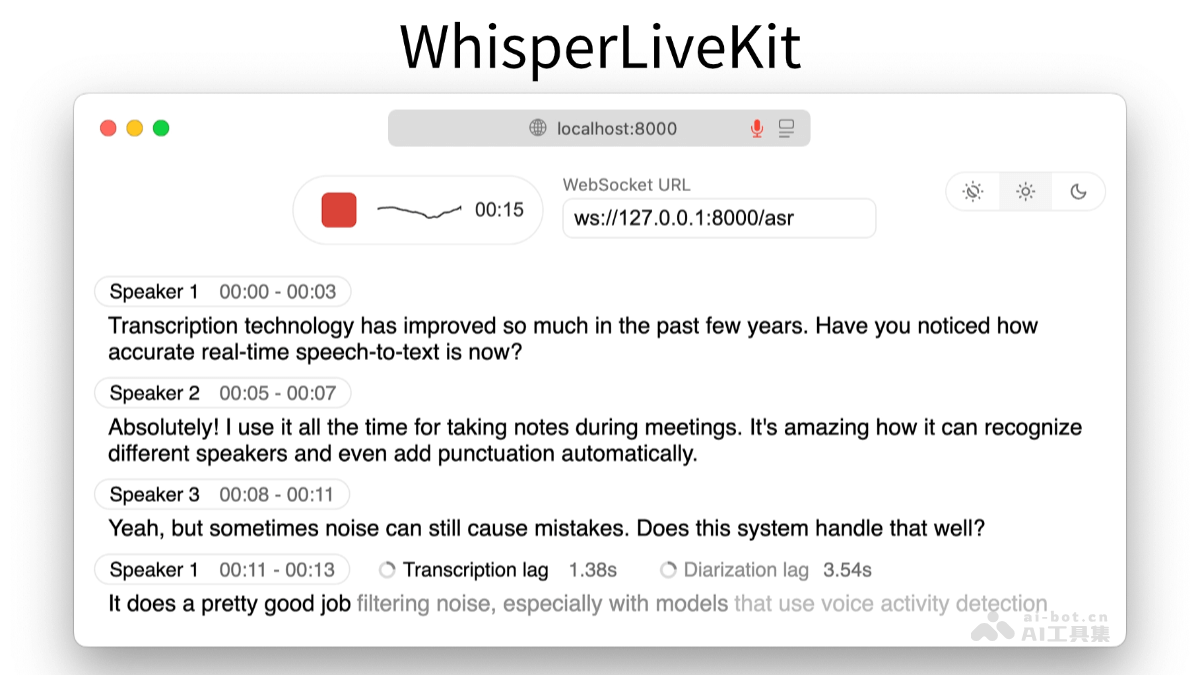
Main features of WhisperLiveKit
- Real-time speech-to-text: Supports multiple languages and can transcribe speech into text in real time, suitable for scenarios such as meetings and lectures.
- Speaker recognition: Automatically distinguishes different speakers, suitable for multi-person meetings, ensuring accurate records.
- Fully local processing: Speech data is processed locally, protecting privacy and suitable for discussions involving sensitive information.
- Low-latency streaming processing: Based on advanced algorithms, ensuring low-latency real-time transcription and a smooth experience.
- Multiple usage methods: Provides a web interface and Python API, making it convenient for users and developers, and supports Docker deployment.
Technical principles of WhisperLiveKit
- SimulStreaming: An ultra-low-latency transcription algorithm based on the AlignAtt strategy, capable of generating text in real time while speech is being input. Based on intelligent buffering and incremental processing, it avoids the problems of context loss and inaccurate transcription caused by overly small speech segments in traditional methods.
- WhisperStreaming: A low-latency transcription algorithm based on the LocalAgreement strategy, suitable for scenarios requiring rapid response. The tool provides higher transcription efficiency and better real-time performance, suitable for applications such as real-time subtitle generation.
- Speaker recognition (Diarization): Uses advanced speaker recognition technologies such as Streaming Sortformer and Diart to distinguish different speakers' speech in real time. Combined with voice activity detection (VAD) and speaker embedding models, it ensures the accuracy and real-time performance of speaker recognition.
- Voice activity detection (VAD): Uses enterprise-grade voice activity detection technologies such as Silero VAD to accurately detect valid speech segments in speech signals and reduce unnecessary processing overhead. Automatically pauses processing when there is no speech input, saving computing resources.
WhisperLiveKit project address
- GitHub repository:https://github.com/QuentinFuxa/WhisperLiveKit
Application scenarios of WhisperLiveKit
- Meeting records: In corporate meetings or academic seminars, transcribes meeting content in real time and accurately distinguishes the identities of different speakers, making it convenient to quickly organize meeting minutes afterward and improving work efficiency.
- Online education: For online courses and remote teaching, generates real-time subtitles for online classes, helping students better understand and absorb knowledge.
- Live subtitles: In live events, generates real-time subtitles for live content, supports multiple languages, and improves the viewing experience for audiences.
- Accessibility assistance: In public places or media playback, provides real-time subtitles for people with hearing impairments, helping users better obtain speech information and promoting equal access to information.
- Customer service centers: Transcribe conversation content in real time during customer service calls, facilitating subsequent quality monitoring and data analysis, and improving customer service efficiency and service quality.