
What is WBench
WBench is the first systematic multi-turn evaluation benchmark for interactive video world models, launched by Meituan's LongCat team. It includes 289 test cases and 1,058 interaction rounds, covering 6 scene categories such as nature, city, and fantasy, and 7 art styles. The benchmark performs a CT scan on 20 frontier models through a unified interaction interface, precisely locating the capability boundaries of models from passive viewing to active interaction, and revealing the core shortcomings of current world models in dimensions such as multi-turn interaction, navigation control, and viewpoint switching.
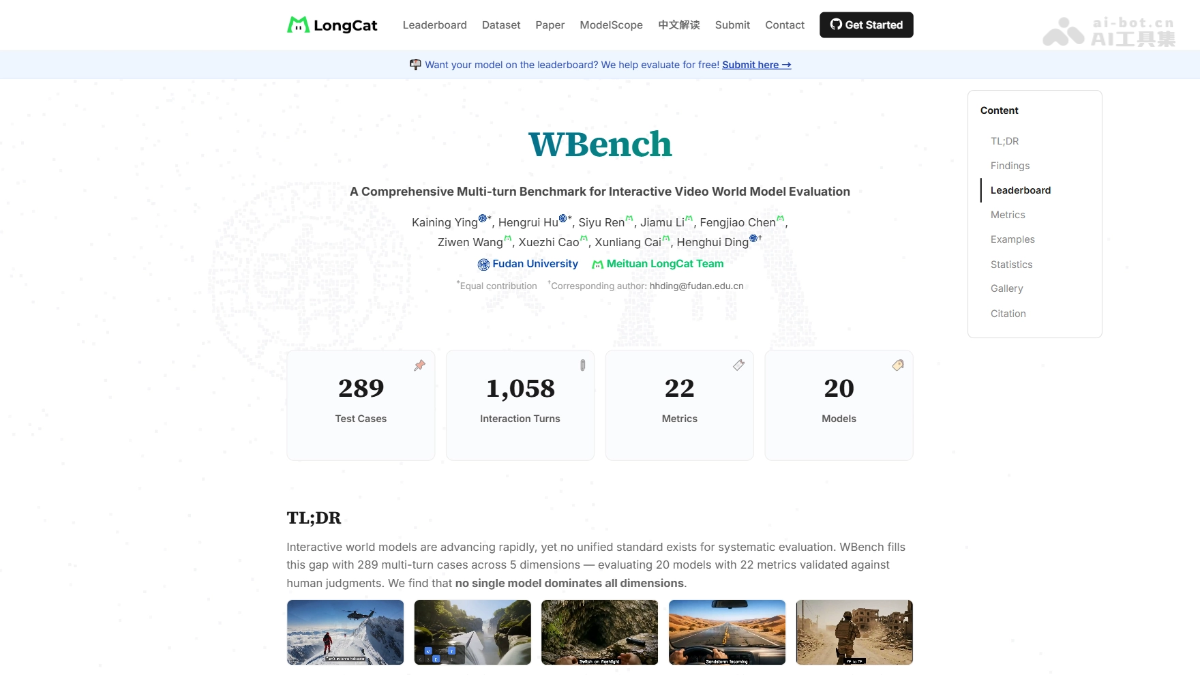
WBench's Main Features
-
Multi-dimensional World Definition: Supports 6 scene categories (nature, city, indoor, workspace, fantasy, sports), 7 art styles (realistic, anime, cartoon, oil painting, ink wash, flat, sketch), and 3 viewpoints including first-person/third-person/embodied first-person).
-
Four Core Interaction Types: Provides four interaction modes: navigation, subject action, event editing, and viewpoint switching.
-
Unified Interaction Interface: Through the Action Router, text instructions, 6DoF coordinates, and keyboard actions are uniformly mapped to standardized inputs, adapting to the native interfaces of different models.
-
Five-dimensional Evaluation Suite: Performs quantitative scoring from five dimensions: video quality, setting adherence, interaction adherence, consistency, and physical realism, including hardcore metrics such as NavScore and Gated Spatial Consistency.
-
Multi-turn Long-horizon Evaluation: Supports continuous multi-turn interaction testing, measuring the performance degradation of models after long-term interaction.
WBench's Technical Principles
- Four Core Element Architecture: WBench's design follows the framework of world definition + instruction set + unified interaction interface + evaluation suite. World definition is responsible for building diverse test environments; the instruction set provides standardized action descriptions; the unified interaction interface converts heterogeneous inputs into signals understandable by models through the Action Router; and the evaluation suite outputs quantitative metrics from five dimensions, forming a complete evaluation loop.
- Decoupled Design of Scenes and Interactions: Adopts the design philosophy of separating stage and script: scenes and interactions are configured independently and can be freely combined. This decoupling enables the evaluation to precisely locate the root cause of problems.
- Multi-turn Autoregressive Feedback Mechanism: The evaluation process adopts an autoregressive approach: the output frames of each round serve as the input for the next round, simulating real interaction scenarios. In this way, WBench can detect the error accumulation effect of models in long-horizon interaction, such as navigation ability declining by an average of 33 points after multiple rounds.
How to Use WBench
- Clone the Repository: Visit the GitHub repository and clone the WBench code locally, and install the Python dependency environment.
- Download the Dataset: Pull the evaluation dataset containing 289 test cases and 1,058 interaction rounds from HuggingFace.
- Connect the Model: Connect the model to be tested to WBench's unified interaction interface through the Action Router, adapting to text or action input protocols.
- Define the Scene: Select the scene type, art style, subject object, and observation viewpoint in the configuration file.
- Select Interactions: Combine test actions from the four interaction types: navigation, subject action, event editing, and viewpoint switching.
- Set Dimensions: Enable five-dimensional evaluation metrics: video quality, instruction following, interaction following, consistency, and physical realism.
- Single-round test: Run initial frame generation and single-round interaction to obtain the model's basic capability score.
- Multi-round test: Start autoregressive mode, using the previous round's output as the next round's input, to measure long-horizon performance degradation.
- Batch comparison: Configure multiple models to run the same test cases in parallel and generate side-by-side comparison data.
- View report: After evaluation ends, automatically generate a radar chart and score table to intuitively display the strength and weakness distribution across each dimension.
WBench's core advantages
-
The first multi-round interaction evaluation benchmark: Unlike traditional single-round video generation evaluation, WBench is the first to systematically evaluate model performance in continuous interaction, filling an industry gap.
-
Comprehensive and decoupled coverage: 289 cases cover 6 major scenarios, 7 styles, and 5 subject types, and scenarios and interactions are configured independently, enabling precise identification of model weaknesses.
-
Unified interface compatible with heterogeneous models: Through Action Router, it adapts text-driven models (such as Kling 3.0) and specialized world models (such as HY-World 1.5), enabling fair comparison.
-
Reveals key industry insights: Text-driven models excel at understanding, specialized world models excel at navigation; video quality is basically unrelated to navigation capability; multi-round interaction is the core difficulty.
WBench project address
- Project official website:https://meituan-longcat.github.io/WBench/
- GitHub repository:https://github.com/meituan-longcat/WBench
- HuggingFace model library:https://huggingface.co/datasets/meituan-longcat/WBench
- Technical paper:https://huggingface.co/papers/2605.25874
Comparison of WBench with similar competitors
| Dimension | WBench | WorldScore |
|---|---|---|
| Positioning | Multi-round interactive video world model evaluation | Unified evaluation benchmark for world generation |
| Release time | 2026-05 | 2025 |
| Case scale | 289 cases, 1058 interaction rounds | 3000 cases |
| Interaction type | Navigation, subject actions, event editing, viewpoint switching | Trajectory-conditioned control, no free interaction |
| Multi-round support | Native multi-round autoregressive evaluation, supports long-horizon degradation analysis | Single-scenario/multi-scenario sequences, non-interactive |
| Unified interface | Action Router (text/6DoF/discrete actions) | Unified world specification (layout + semantics) |
| Evaluation dimensions | Video quality, instruction following, interaction following, consistency, physical realism | Controllability, quality, dynamics |
| Core features | Multi-round interaction degradation diagnosis, decoupling of scenarios and interactions | Unified evaluation across 3D/4D/I2V/T2V |
| Online platform | Offline evaluation suite + HuggingFace dataset | Offline leaderboard |
WBench application scenarios
-
World model R&D: Provide standardized evaluation tools for video world models (such as Genie, Kling, Wan, etc.) to guide model iterative optimization.
-
Navigation and embodied intelligence evaluation: Specifically evaluates a model's navigation and control capabilities in virtual environments, suitable for embodied intelligence directions such as robotics and autonomous driving.
-
Multi-turn interactive product testing: Helps AI video/game products evaluate long-horizon interactive experiences, such as virtual world exploration, AI game engines, etc.
-
Academic research benchmark: Serves as a foundational evaluation framework for academic research on world models and interactive video generation, promoting standardization in the field.
-
Open-source vs closed-source model selection: Provides objective data for enterprises and developers to assist in selecting model solutions suitable for specific interactive tasks (such as navigation/editing).