
What is Tongyi Wanxiang Wan2.2
Tongyi Wanxiang 2.2 (Wan2.2) is Alibaba's open-source advancedAI video generationmodel. A total of three models have been open-sourced: text-to-video (Wan2.2-T2V-A14B), image-to-video (Wan2.2-I2V-A14B), and unified video generation (Wan2.2-IT2V-5B), with a total parameter count of 27 billion. The model introduces a Mixture of Experts (MoE) architecture for the first time, effectively improving generation quality and computational efficiency, while also pioneering a cinematic aesthetic control system that can precisely control aesthetic effects such as lighting, color, and composition. This open-sourced 5B parameter compact video generation model supports text and image to video generation and can run on consumer-grade graphics cards. Based on an efficient 3D VAE architecture, it achieves high compression rates and the ability to quickly generate high-definition videos. Currently, developers can obtain the model and code through platforms such as GitHub and HuggingFace, and enterprises can useAlibaba Cloud Bailianto call APIs for application development, and users canTongyi Wanxiangon the official website andTongyi APPexperience it directly.
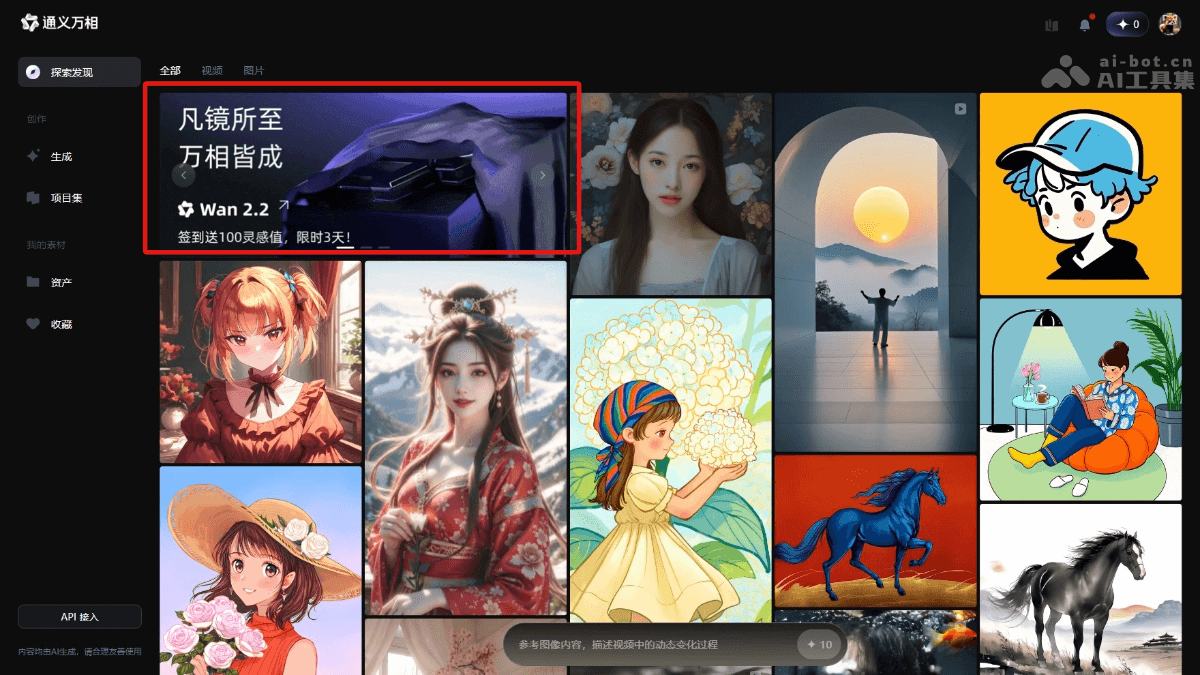
Main Features of Tongyi Wanxiang Wan2.2
- Text-to-Video: Generate corresponding video content based on the input text description. For example, input "a cat running on the grass," and the model can generate a video that matches the description.
- Image-to-Video: Generate video based on the input image. The model generates a dynamic scene based on the image content, making the image "come alive."
- Unified Video Generation (Text-Image-to-Video): Generate video by combining text and images, using both text descriptions and image information to generate more accurate video content.
- Cinematic Aesthetic Control: Through control of lighting, color, composition, micro-expressions, and more, generate videos with a professional cinematic quality. Users can customize the aesthetic style of the video by inputting relevant keywords (such as "warm tones" or "central composition").
- Complex Motion Generation: Can generate complex motion scenes and character interactions, enhancing the dynamic expressiveness and realism of videos.
Technical Principles of Tongyi Wanxiang Wan2.2
- Mixture of Experts (MoE) Architecture: Introduces the MoE architecture, dividing the model into a high-noise expert and a low-noise expert. The high-noise expert is responsible for the overall layout of the video, while the low-noise expert is responsible for refining details. While keeping computational costs unchanged, it greatly increases the model's parameter count and generation quality.
- Diffusion Model: Based on the diffusion model as the foundational architecture, generating high-quality video content by gradually removing noise. The combination of the MoE architecture and the diffusion model can further optimize the generation effect.
- High-Compression 3D VAE: To improve model efficiency, Tongyi Wanxiang 2.2 is based on a high-compression 3D variational autoencoder (VAE). The architecture achieves high compression ratios in time and space, enabling the model to quickly generate high-definition videos on consumer-grade graphics cards.
- Large-Scale Data Training: The model is trained on large-scale datasets, including more image and video data, improving the model's generalization ability and generation quality across various scenarios.
- Aesthetic Data Annotation: Based on carefully annotated aesthetic data (such as lighting, color, and composition), the model can generate video content with a professional cinematic quality, meeting users' customization needs for video aesthetics.
Project address for Tongyi Wanxiang Wan2.2
- GitHub repository:https://github.com/Wan-Video/Wan2.2
- HuggingFace model library:https://huggingface.co/Wan-AI/models
How to use Tongyi Wanxiang Wan2.2
- Visit the official website: VisitTongyi Wanxiang's official website or downloadTongyi APPto experience it。
- Select a model: Select Tongyi Wanxiang 2.2 from the model selection dropdown.
- Select an experience mode:
- Text-to-Video: Enter a text description, for example, "a cat running on the grass," and click the generate button to see the generated video.
- Image-to-Video: Upload an image, and the model generates a dynamic video based on the image content.
- Unified Video Generation (Text-Image-to-Video): Combine a text description with an uploaded image to generate more precise video content.
- Adjust parameters (optional): Users can adjust parameters such as video resolution and frame rate as needed. Use the cinematic aesthetic control system to customize the video's aesthetic style by entering keywords such as "warm tones" or "centered composition."
- View the generation results: The generated video is displayed directly on the web page, and users can download or share the generated video.
Application scenarios of Tongyi Wanxiang Wan2.2
- Short video creation: Creators can quickly generate engaging short video content for social media platforms, saving creation time and cost.
- Advertising and marketing: Advertising agencies and brands can generate high-quality advertising videos to improve advertising effectiveness and brand influence.
- Education and training: Educational institutions and enterprises can generate vivid educational videos and training materials to improve learning outcomes and training quality.
- Film and television production: Film and television production teams can quickly generate scene designs and animated clips, improving creative efficiency and reducing production costs.
- News and media: News organizations and media can generate animations and visual effects to enhance the visual impact of news reports and audience engagement.