
What is Wan-Streamer
Wan-Streamer is an end-to-end real-time full-duplex multimodal foundation model open-sourced by Alibaba DAMO Academy. Through a unified causal Transformer architecture, it integrates the input and output tokens of text, audio, and video into a single causal sequence, enabling sub-second real-time bidirectional video interaction. The model response latency is only 200ms, the end-to-end total latency is 550ms, and it stably outputs 25FPS synchronized audio and video.
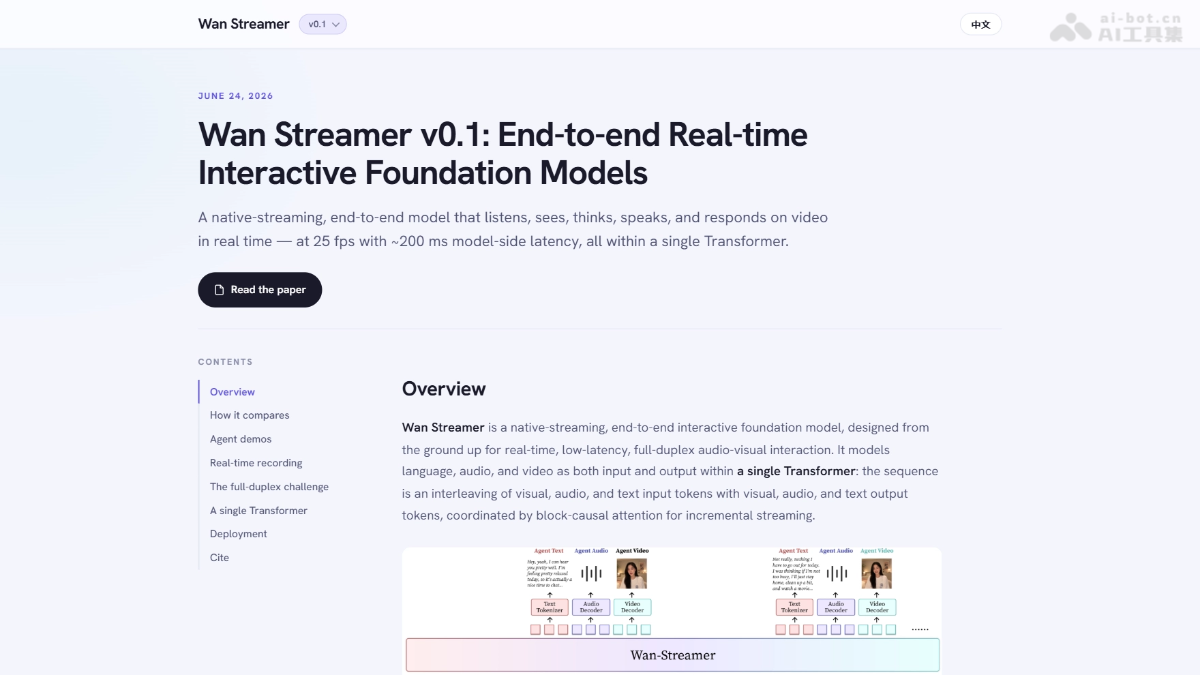
Wan-Streamer's Main Features
- Real-Time Audio-Video Conversation: Supports bidirectional video calls between users and AI digital humans, with the AI able to synchronously output voice and facial expressions.
- Full-Duplex Interaction: Supports real-time user interruption and proactive AI questioning, enabling natural and fluent human-machine conversation.
- Multimodal Input Understanding: Simultaneously receives and understands the user's video images, voice, and text input.
- Streaming Chunked Generation: Adopts 160ms short-time streaming chunks, generating feedback while receiving information, without waiting for full frames.
- Long-Term Temporal Consistency: Global KV context caching ensures stable and consistent character appearance and tone throughout long conversations.
Wan-Streamer's Technical Principles
- Unified Single Transformer Streaming Architecture: Interleaves the user's video images, voice, and text input with the AI's voice, expressions, and subtitle output into a single causal token stream, with autoregressive text prediction and joint generation of audio-video via conditional flow matching.
- Fully Causal Technology Stack Design: From encoder and decoder to VAE and attention layers, all follow causal constraints, using only historical temporal information to predict the next unit, with core block causal attention restricting future tokens from being visible.
- Three-Stage Training Process: Multi-task pretraining mixes image-text-speech dialogue data, full-duplex fine-tuning learns listening, interruption, and pause behaviors, and streaming distillation lightweights the large teacher model and adopts a rolling self-forcing strategy.
- Thinker-Performer Dual-GPU Inference: The Thinker handles user audio-video encoding and context updates, while the Performer executes flow-matching audio-video denoising generation, with both sharing context and executing in parallel.
How to Use Wan-Streamer
Currently, Wan-Streamer has only released a paper and a project official website demo. The complete code and model weights have not yet been open-sourced, so local deployment is not possible at this time.
Wan-Streamer's Core Advantages
-
Ultra-Low Latency: 200ms response on the model side, only 550ms end-to-end, far below the industry level of over 1 second.
-
End-to-End Integration: A single model completes the entire process of perception, understanding, and generation, without the need for ASR, LLM, TTS, and rendering multi-module stitching.
-
Full-Duplex Real-Time Interaction: Supports responding while listening and interrupting mid-conversation, with naturalness comparable to real people.
-
Audio-Video Synchronization: Voice and facial movements are generated under synchronized constraints, without the need for post-alignment fixes, with zero lip-sync misalignment.
-
Long Conversation Stability: Global KV context ensures that character appearance and tone do not drift over long periods.
Wan-Streamer's Project Address
- Project Official Website:https://wan-streamer.com/
- arXiv Technical Paper:https://arxiv.org/pdf/2606.25041
Wan-Streamer's Comparison with Similar Competing Products
| Comparison Dimension | Wan-Streamer | GPT-4o Realtime |
|---|---|---|
| Developer | Alibaba DAMO Academy | OpenAI |
| Video Input | ✅ Supported | ✅ Supported |
| Synchronized video output | ✅ Digital human video | ❌ Audio only |
| Full-duplex interaction | ✅ Real-time interruption/interjection | ⚠️ Partially supported |
| End-to-end architecture | ✅ Single Transformer | ❌ ASR+LLM+TTS concatenation |
| Model response latency | 200ms | 230ms |
| End-to-end total latency | ~0.55s | ~0.8s |
| Rendering latency | Included in end-to-end | Not included (audio only) |
| Lip sync | ✅ Natively synchronized generation | ❌ No video output |
| Long-term temporal consistency | ✅ Global KV cache | ⚠️ Depends on external systems |
| Current resolution | 192p (prototype) | No video output |
Wan-Streamer Application Scenarios
-
Virtual customer service: Provides face-to-face real-time video consultation services for scenarios such as banking and e-commerce.
-
Live streaming interaction: AI streamers respond in real time to viewers' bullet comments and voice questions, enhancing the interactive experience in live streaming rooms.
-
AI companionship: Emotional companionship digital humans support real-time video chat, providing an immersive companionship experience.
-
Game NPCs: Interactive game characters engage in real-time video dialogue with players, enhancing game immersion.
-
Online education: AI virtual teachers provide real-time video Q&A and personalized tutoring.