
What is Voxtral
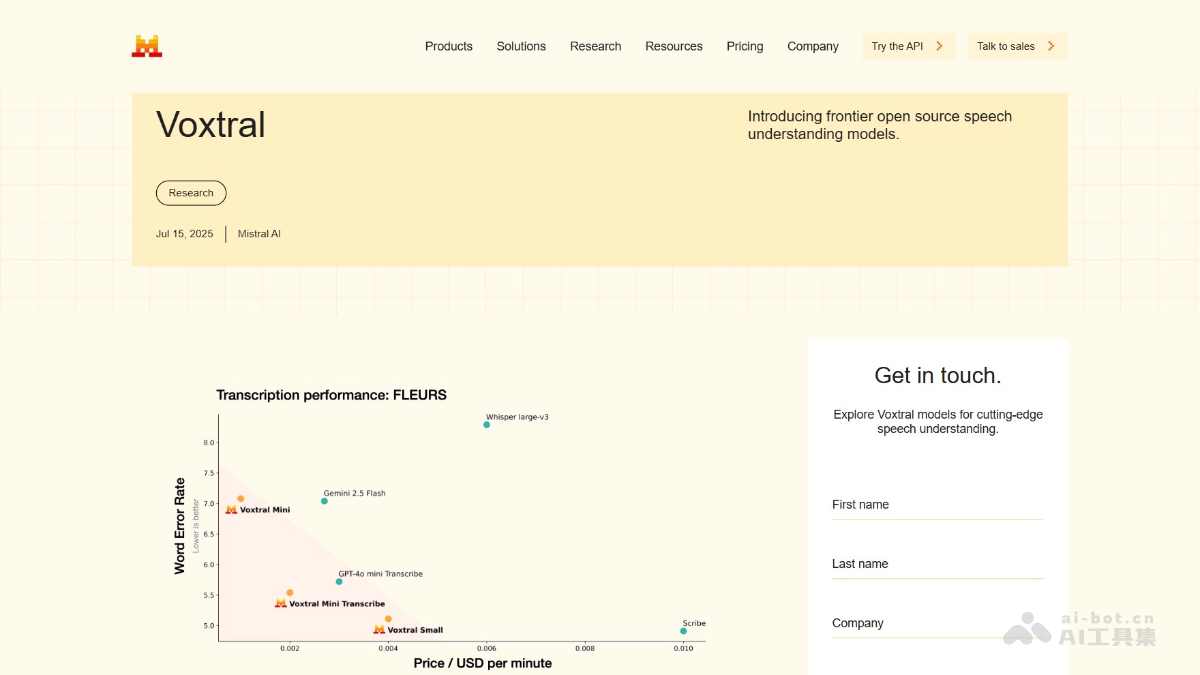
Voxtral is an advanced audio model introduced by Mistral AI. Built on excellent speech transcription and deep understanding capabilities, it promotes voice as a natural way of human-computer interaction. Voxtral offers two versions, 24B and 3B, suitable for production scale and local deployment respectively. Voxtral supports multiple languages, long-text context, built-in question answering and summarization, and can directly trigger backend function calls. Voxtral's performance surpasses existing open-source models and proprietary APIs in multiple benchmarks, while costing less, and is widely used in various scenarios, helping to popularize voice interaction.
Voxtral's main features
- Long-text context processing: Supports audio transcription of up to 30 minutes and audio understanding of up to 40 minutes, and can handle complex long-form content.
- Built-in question answering and summarization: Ask questions directly about audio content, or generate structured summaries, without the need for additional ASR and language models.
- Multilingual support: Automatic language detection, supporting multiple common languages (such as English, Spanish, French, Portuguese, Hindi, German, etc.), meeting the needs of global users.
- Voice-triggered function calling: Directly trigger backend functions, workflows, or API calls based on the user's voice intent, without intermediate parsing steps.
- Text understanding capability: Retains Mistral Small 3.1 text understanding capability, supporting text input and processing.
- Optimized transcription performance: Provides a highly optimized transcription endpoint, cost-effective, and suitable for large-scale applications.
Voxtral's technical principles
- Speech recognition based on deep learning: Voxtral uses advanced deep learning technologies, such as the Transformer architecture, to process and understand speech signals. The model is trained on large amounts of speech data and can accurately recognize and transcribe speech content.
- Multilingual model architecture: Based on a shared model architecture and multilingual training data, Voxtral achieves automatic recognition and understanding of different languages.
- Context-aware capability: With long-text context (32k token context length), the model can understand the semantics and logical relationships of speech content, providing more accurate transcription and understanding results.
- End-to-end speech understanding: Voxtral combines speech recognition (ASR) and natural language understanding (NLU) in one model, directly generating text, answering questions, or performing related operations from speech input, reducing the complexity and error rate of multi-step processing in traditional systems.
Voxtral's project address
- Project official website:https://mistral.ai/news/voxtral
- HuggingFace model library:
- https://huggingface.co/mistralai/Voxtral-Small-24B-2507
- https://huggingface.co/mistralai/Voxtral-Mini-3B-2507
Voxtral's application scenarios
- Meeting transcription and summarization: Transcribe meeting content in real time and generate structured summaries, making it convenient to quickly review and extract key information after the meeting.
- Customer service: Voxtral can transcribe conversations between customers and customer service, quickly understand customer needs and trigger backend operations, significantly improving service efficiency.
- Content creation: Efficiently transcribe audio content into text transcripts, widely used in news interviews, podcast production, and video subtitle generation, helping content creators produce quickly.
- Education: Transcribe online courses or lecture content and provide real-time question answering, effectively enhancing the learning experience.
- Intelligent assistant: As the core of voice interaction, it understands user instructions and executes operations, and is applied in scenarios such as smart homes and office equipment.