
What is VoxInstruct
VoxInstruct is an open-source speech synthesis technology from Tsinghua University that can generate speech highly aligned with user needs based on human language instructions. The system adopts a unified multilingual codec language modeling framework, extending the traditional text-to-speech task to the broader human instruction-to-speech task. VoxInstruct introduces speech semantic tokens and multiple classifier-free guidance strategies to improve the naturalness and expressiveness of speech synthesis. It supports multilingual and cross-lingual synthesis and is suitable for various scenarios such as intelligent voice assistants, audiobooks, and education and training.
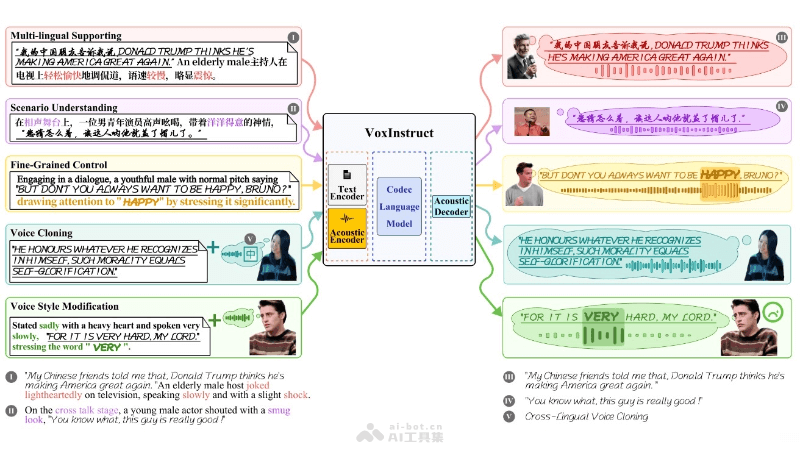
Main Features of VoxInstruct
- Multilingual support: VoxInstruct can process and generate speech in multiple languages and supports cross-lingual speech synthesis.
- Instruction-to-speech generation: Directly converts human language instructions into speech without complex preprocessing or instruction segmentation.
- Speech semantic tokens: Introduces Speech Semantic Tokens as an intermediate representation to help the model understand and extract the speech content in instructions.
- Classifier-free guidance strategies: Adopts multiple Classifier-Free Guidance (CFG) strategies to enhance the model's understanding of human instructions and the controllability of speech generation.
- Emotion and style control: VoxInstruct can generate speech with corresponding emotions and styles based on the emotion and style descriptions in instructions.
Technical Principles of VoxInstruct
- Unified multilingual codec language model framework: VoxInstruct uses a codec framework to process and understand instructions in multiple languages and convert instructions into corresponding speech output.
- Pretrained text encoder: VoxInstruct is based on a pretrained text encoder (such as MT5) to understand and process input natural language instructions and capture the semantic information of the language.
- Speech Semantic Tokens: An intermediate representation that maps text instructions to speech content. It helps the model extract key information from the original text and guides speech generation.
- Classifier-Free Guidance (CFG) strategies: VoxInstruct combines CFG strategies to enhance the model's responsiveness to human instructions and improve the naturalness and accuracy of speech synthesis.
- Neural codec model: Encodec serves as the acoustic encoder to extract acoustic features as an intermediate representation, which is then used to generate speech waveforms.
VoxInstruct Project Address
- Project official website:voxinstruct.github.io
- GitHub repository:https://github.com/thuhcsi/VoxInstruct
Application Scenarios of VoxInstruct
- Personalized voice feedback: Intelligent assistants set different voice styles according to user preferences, such as gender, age, accent, etc., and use VoxInstruct to generate personalized voice feedback.
- Emotional interaction: By analyzing user instructions and context, VoxInstruct generates speech with emotional coloring, such as happy, sad, or neutral, making interaction more natural and expressive.
- Multilingual support: For multilingual environments, VoxInstruct supports speech synthesis in multiple languages, helping intelligent assistants better serve users from different language backgrounds.
- Voice navigation system: In intelligent navigation systems, VoxInstruct generates clear voice instructions, providing real-time route guidance and traffic information.