
What is VITRON
VITRON is a pixel-level visual large language model (LLM) jointly launched by Skywork AI, the National University of Singapore, and Nanyang Technological University. It can comprehensively understand and process static images and dynamic videos, and perform understanding, generation, segmentation, and editing on images and videos. VITRON combines a front-end visual encoder and a back-end visual expert system, supporting a variety of tasks from visual understanding to visual generation. VITRON transmits information based on a hybrid approach, combining discrete text instructions and continuous signal embeddings to achieve precise function invocation, and designs cross-task collaboration modules to enhance the synergistic effects among different visual tasks.
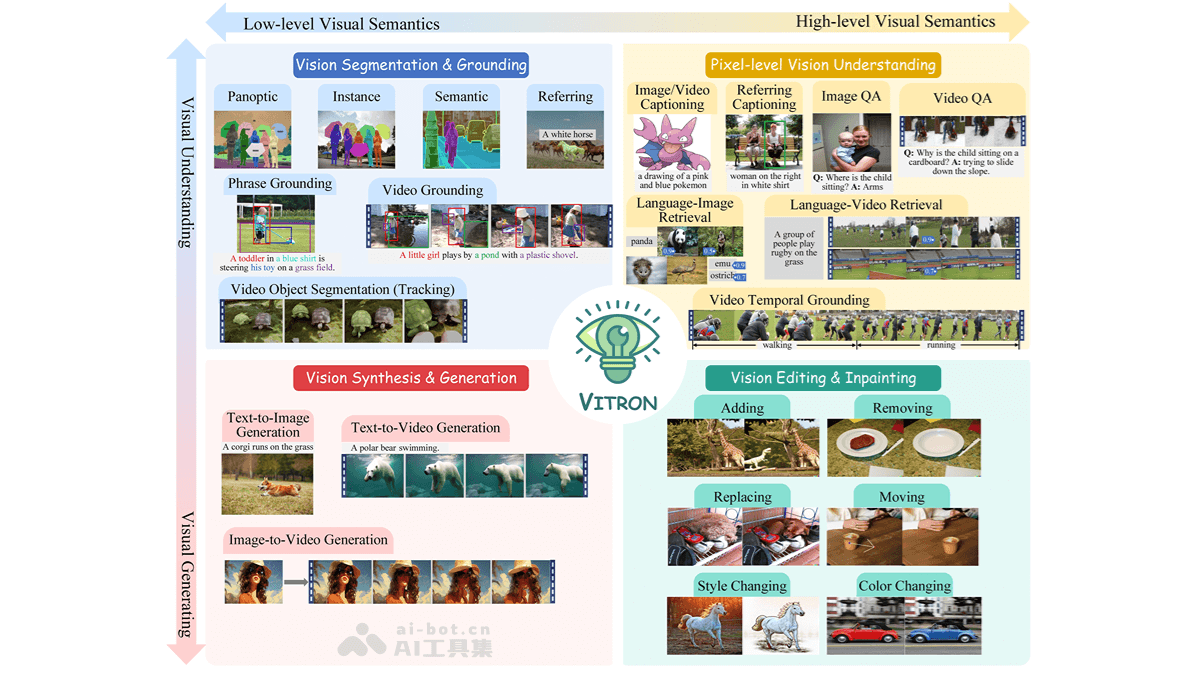
VITRON's main features
- Visual understanding: Includes question answering (QA) for images and videos, referring expression, and visual reasoning.
- Visual generation: Text-to-Image and Text-to-Video.
- Visual segmentation: Includes segmentation tasks for images and videos, such as instance segmentation, panoptic segmentation, etc.
- Visual editing: Edits images and videos, such as adding, replacing, removing, and changing colors.
- Interactive user input: Handles interactive user input such as clicks, drawn boxes or polygons, and scribbles.
VITRON's technical principles
- Encoder-LLM-Decoder architecture: Based on the common encoder-large language model (LLM)-decoder architecture, where the encoder is responsible for processing image and video input, the LLM is responsible for semantic understanding and decision-making, and the decoder is responsible for executing specific visual tasks.
- Front-end vision-language encoding: Uses CLIP ViT-L/14@336px as the encoder for images and videos, processes each video frame and performs average pooling to obtain an overall temporal representation feature. Uses a region pixel-aware visual extractor as the sketch encoder to process user interactive input.
- Core LLM: Uses Vicuna (7B, version 1.5) as the LLM to process input from language and visual modalities, perform semantic understanding and reasoning, and generate decisions.
- Back-end visual experts: Integrates a series of single visual experts, such as GLIGEN for image generation and editing, SEEM for image and video segmentation, ZeroScope and I2VGen-XL for text-to-video and image-to-video tasks, and StableVideo for video editing.
- Hybrid approach instruction transmission: Introduces a novel hybrid approach that ensures the LLM's decisions can be accurately transmitted to the back-end modules based on discrete text instructions and continuous signal feature embeddings.
VITRON's project addresses
- Project official website:vitron-llm.github.io
- GitHub repository:https://github.com/SkyworkAI/Vitron
- arXiv technical paper:https://arxiv.org/pdf/2412.19806
VITRON's application scenarios
- Image editing assistance: Repairs and beautifies photos, such as removing unnecessary objects or enhancing image colors.
- Video content creation: Generates video content from script text, including scene construction and character animation.
- Online education platforms: Automatically generates teaching videos and images on education platforms according to teaching syllabi to assist teaching.
- E-commerce visual marketing: Automatically generates product display videos for e-commerce platforms to enhance product appeal.
- News media content production: Help news organizations quickly generate visual coverage of news events, including images and videos.