
What is VITA
VITA is the world's first open-source multimodal large language model (MLLM) launched by Tencent Youtu Lab. It can understand and process video, images, text, and audio. Based on the Mixtral 8×7B model, it has expanded its Chinese vocabulary and undergone bilingual instruction fine-tuning. It supports natural human-computer interaction and can respond without a wake word. VITA's open-source nature provides important resources for academia and industry, driving the development of multimodal understanding and interaction technologies.
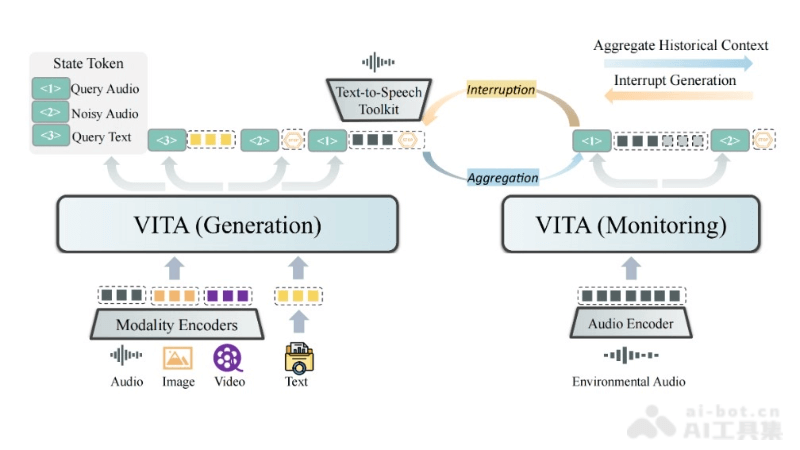
VITA's Main Features
- Multimodal Understanding: VITA can understand and process data from multiple modalities such as video, images, text, and audio, providing rich information processing capabilities.
- Bilingual Capability: After bilingual instruction fine-tuning, it is proficient in English and Chinese, and has enhanced recognition and processing capabilities for Chinese dialects.
- Natural Interaction: Users do not need a specific wake word when communicating with VITA. The model can determine the user's communication intent based on context, enabling natural conversation.
- Audio Interruption Feature: VITA can accurately identify and respond to user commands when the user is talking with others or in other sound environments, enhancing the naturalness of interaction.
- Duplex Deployment Framework: It adopts a deployment scheme with two models, one responsible for generating responses and the other continuously tracking environmental input, ensuring the accuracy and timeliness of interaction.
How to Use VITA
- Environment Preparation:Ensure the hardware and software environment required for using VITA, including servers, storage devices, and network connections.
- Obtain the Model:Visit VITA's open-source repository and download or clone its codebase and pre-trained model.
- Install Dependencies:Install the dependency libraries and tools required to run VITA, such as Python, deep learning frameworks (e.g., PyTorch or TensorFlow), etc.
- Model Loading:Load the pre-trained VITA model into the working environment, ready for interaction or further training.
- Data Preparation:Prepare the data you want VITA to process, including text, image, video, or audio files, and ensure they meet the model's input requirements.
VITA's Project Address
- Project Official Website:https://vita-home.github.io/
- GitHub Repository:https://github.com/VITA-MLLM/VITA
- arXiv Technical Paper:https://arxiv.org/pdf/2408.05211
VITA's Application Scenarios
- Smart Home Control: VITA can understand voice commands and control smart devices at home, such as lights, temperature, security systems, etc.
- Personal Assistant: Provides assistant functions such as schedule management, information search, email filtering, and reading summaries to improve personal efficiency.
- Language Translation and Learning: Supports multilingual interaction, helping users overcome language barriers, promoting international communication, and assisting language learning.
- Medical Consultation: Analyzes medical records and symptom descriptions, provides preliminary medical consultation and suggestions, and assists doctors in diagnosis.
- Legal Services: Interprets legal documents, provides legal consultation, and helps users understand complex legal clauses.