
What is ViLAMP
ViLAMP (VIdeo-LAnguage Model with Mixed Precision) is a vision-language model jointly launched by Ant Group and Renmin University of China, specifically designed for efficiently processing long video content. Based on a mixed-precision strategy, it maintains high-precision analysis of key frames in videos, significantly reducing computational costs and improving processing efficiency. ViLAMP performs excellently on multiple video understanding benchmarks and shows significant advantages in long video understanding tasks. ViLAMP can process videos up to 10,000 frames (about 3 hours) on a single A100 GPU while maintaining stable understanding accuracy, providing a new solution for long video analysis.
Main Features of ViLAMP
- Long Video Understanding: Supports processing videos lasting several hours.
- Key Information Extraction: Accurately extracts key information from videos while compressing redundant information.
- Efficient Computing: Processes videos up to 10,000 frames (about 3 hours) on a single A100 GPU, significantly reducing memory and computational costs and improving processing efficiency.
- Multi-task Processing: Supports various video understanding tasks, such as video content question answering, action recognition, scene understanding, etc.
Technical Principles of ViLAMP
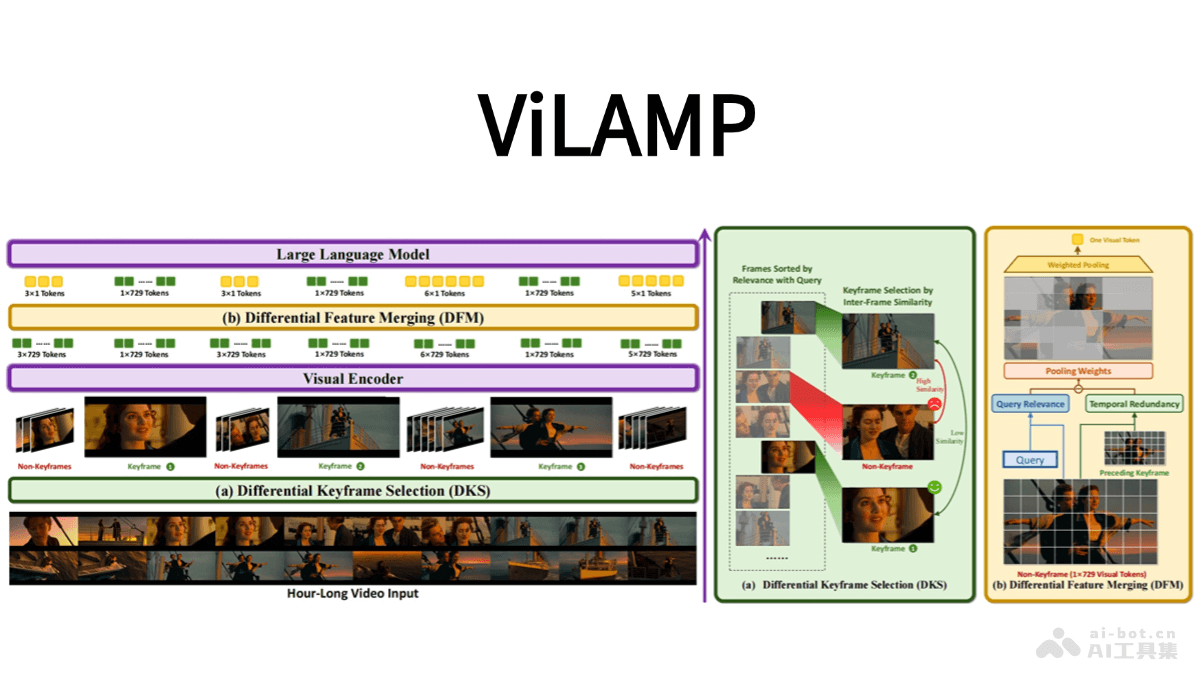
- Differential Key Frame Selection: Selects key frames highly relevant to the user query and temporally diverse based on a greedy algorithm. Ensures that the selected key frames can capture important information while avoiding redundancy.
- Differential Feature Merging: Compresses non-key frames by merging multiple patches of each non-key frame into a single token. Based on differential weighted pooling, it gives higher weights to patches that are relevant to the user query and unique, while reducing the weights of patches that duplicate key frames. It preserves key information while significantly reducing computation.
Project Address of ViLAMP
- GitHub Repository:https://github.com/steven-ccq/ViLAMP
- arXiv Technical Paper:https://arxiv.org/pdf/2504.02438
Application Scenarios of ViLAMP
- Online Education: Quickly extracts key content from educational videos, generates summaries, or answers student questions.
- Video Surveillance: Analyzes surveillance videos in real time, detects abnormal events, and issues timely alerts.
- Live Stream Analysis: Processes live stream content in real time, extracts highlights, or answers audience questions.
- Film and Television Production: Helps editors and directors screen materials, extract key scenes, and improve production efficiency.
- Intelligent Customer Service: Automatically answers user questions about video content, improving user experience.