
What is ViiTorVoice
ViiTorVoice is the world's first model launched by Yunshang Qulv that supports local editing for AI speech synthesis, topping the authoritative Seed-TTS benchmark. It adopts a NAR non-autoregressive architecture to achieve "edit speech like editing Word"—it can replace a specific word or segment in the audio in a targeted way, while the rest of the timbre, rhythm, and emotion remain completely unchanged. It supports zero-text cross-lingual cloning, precise emotion control, and 60ms ultra-low-latency inference. The 1B parameter model has been open-sourced.
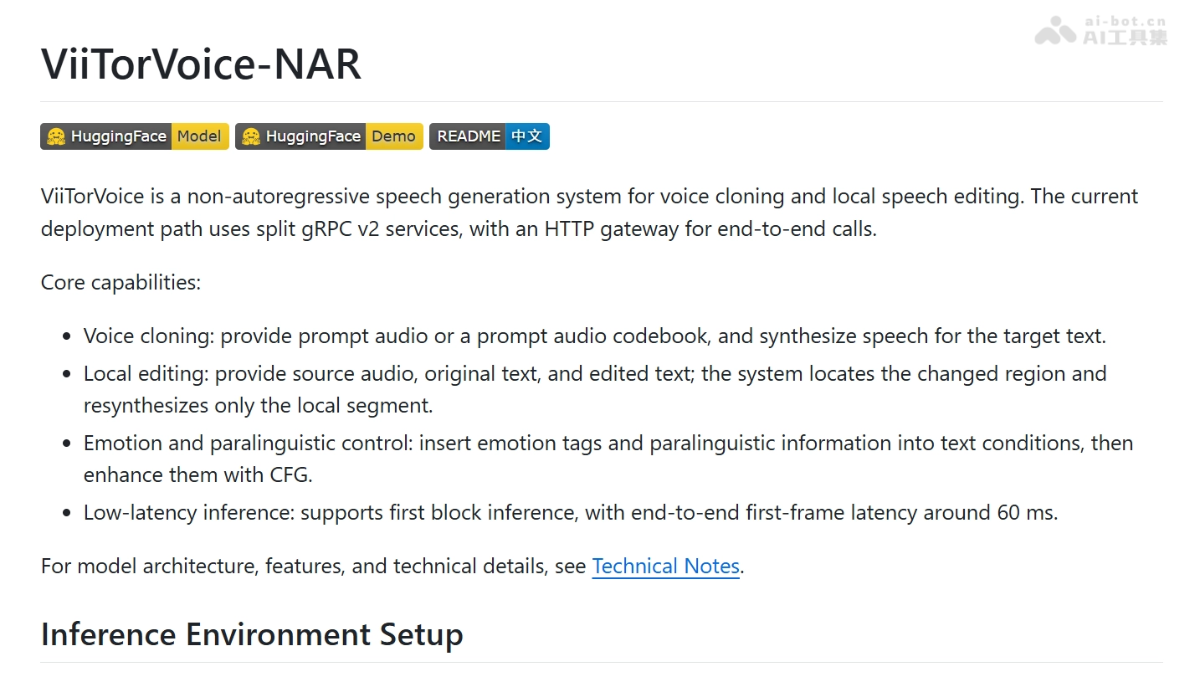
ViiTorVoice's Main Features
-
Segment-level local editing: You can specify a word or segment in the audio to replace, while the rest remains completely unchanged.
-
Voice cloning: Supports zero-shot cross-lingual cloning with no reference text; just upload pure audio to extract the timbre.
-
Emotion and paralinguistic control: Achieves precise word-level control by inserting special tokens, and introduces CFG technology to strengthen emotional expression.
-
Low-latency inference: End-to-end first frame generation time is under 60ms, supporting first-chunk inference.
-
Multilingual support: Generates content in multiple languages including Chinese, English, Japanese, and Korean.

Follow WeChat and reply with "open source" to join theAI Open Source Project Communication Group
How to Use ViiTorVoice
-
Visit the Demo page: Open the Hugging Face online experience address (https://huggingface.co/spaces/ZzWater/ViiTorVoice)。
-
Select the feature mode: Switch between the "Voice Edit" (local editing) or "Voice Clone" (voice cloning) tabs at the top of the interface.
-
Upload the source audio: Drag the original audio file to be edited or cloned into the "Source Audio" upload area on the left.
-
Enter text instructions: Fill in the original transcription text and the modified target text in the edit box, and the system will automatically locate the differing segments.
-
Insert emotion tags: If you need to control emotion, insert special tokens (such as
<laugh>、<sigh>) into the text to mark paralinguistic information. -
Adjust generation parameters: Set configurations such as the number of inference steps (4 steps or 8 steps), and click the generate button to wait for the model to process.
-
Preview and download: Play the result in the "Edited Audio" area on the right, and after confirming it is correct, download and save it locally.
ViiTorVoice's Core Advantages
-
Ranked first globally in benchmark results: Seed-TTS English word error rate 1.32, Chinese word error rate 0.99, with SIM-o and UTMOS both leading.
-
Original local editing capability: The only one in the industry to support segment-level targeted editing, solving the pain point that traditional TTS requires re-recording the entire segment to change words.
-
Text-free cloning: Enables cross-lingual timbre transfer without accurate transcription text, suitable for low-resource language scenarios.
-
Extremely fast inference: First frame latency within 60ms, far better than the industry level of 150-200ms.
ViiTorVoice's Project Address
- GitHub repository:https://github.com/viitor-ai/viitor-voice-nar
- HuggingFace model library:https://huggingface.co/ZzWater/ViiTorVoice-NAR
Comparison of ViiTorVoice with Similar Competitors
| Comparison dimension | ViiTorVoice | Qwen3-TTS |
|---|---|---|
| Developer | Yunshang Qulü | Alibaba Tongyi Lab |
| Core Architecture | NAR Non-Autoregressive(fill-in-the-blank style) | AR Autoregressive(frame-by-frame chained generation) |
| Local Editing | ✅ Supports segment-level targeted modification, change the word without changing the whole segment | ❌ Not supported, changing one word requires regenerating the entire segment |
| Seed-TTS English WER | 1.32(lower = more accurate) | 1.54 |
| Seed-TTS Chinese WER | 0.99(industry's first <1.0) | 1.15 |
| First-frame Latency | <60ms | ~150-200ms |
| Text-free Cloning | ✅ Only pure audio is needed for cross-lingual cloning | ❌ Requires providing audio + accurate transcription text |
| Emotion Control | Word-level Token precise control (laughter/sighing, etc.) | Basic natural language description control |
Application Scenarios of ViiTorVoice
- Film and Television Post-Production: Dialogue adjustments no longer require gathering actors to re-enter the recording studio; directors can replace lines in real time on the nonlinear timeline, with timbre and breathing rhythm remaining seamlessly consistent.
- Audiobooks and Podcasts: When slips of the tongue or proper noun errors occur during recording, only one or two seconds of audio need targeted modification, without re-recording the entire chapter, compressing post-production audio repair time from several days to a few dozen minutes.
- Short Drama Overseas Localization: Without re-gathering voice actors, specific words can be replaced directly on the original recording to produce multilingual versions, each sounding like an original performance.
- Advertising and Marketing: When copy is temporarily adjusted for a product name or slogan, audio segments can be directly replaced locally, preserving the original brand timbre and emotional appeal.
- Game Voiceover: Rapid cloning of cross-lingual character voices; simply upload the character's original voice audio to generate voiceovers in multiple languages such as Chinese, English, Japanese, and Korean.