
What is Vidu S1
Vidu S1 is a globally leading real-time interactive video foundation model launched by Shengshu Technology, marking the entry of AI video from offline generation into the era of real-time bidirectional interaction. Based on an autoregressive diffusion architecture, it supports real-time video generation at 540P resolution and 25FPS (up to 42FPS), and can run on consumer-grade GPUs. Users only need to upload a single image to create a digital character with zero training, and drive the character's expressions, lip movements, gestures, and full-body actions in real time through voice commands, achieving stable interaction of unlimited duration. Vidu S1 has scene understanding capabilities, can perceive camera footage and respond in real time, and is widely used in scenarios such as AI companionship, virtual idols, interactive livestreaming, and game NPCs, redefining the evolution path of digital humans from static content assets to continuously online intelligent interaction portals.
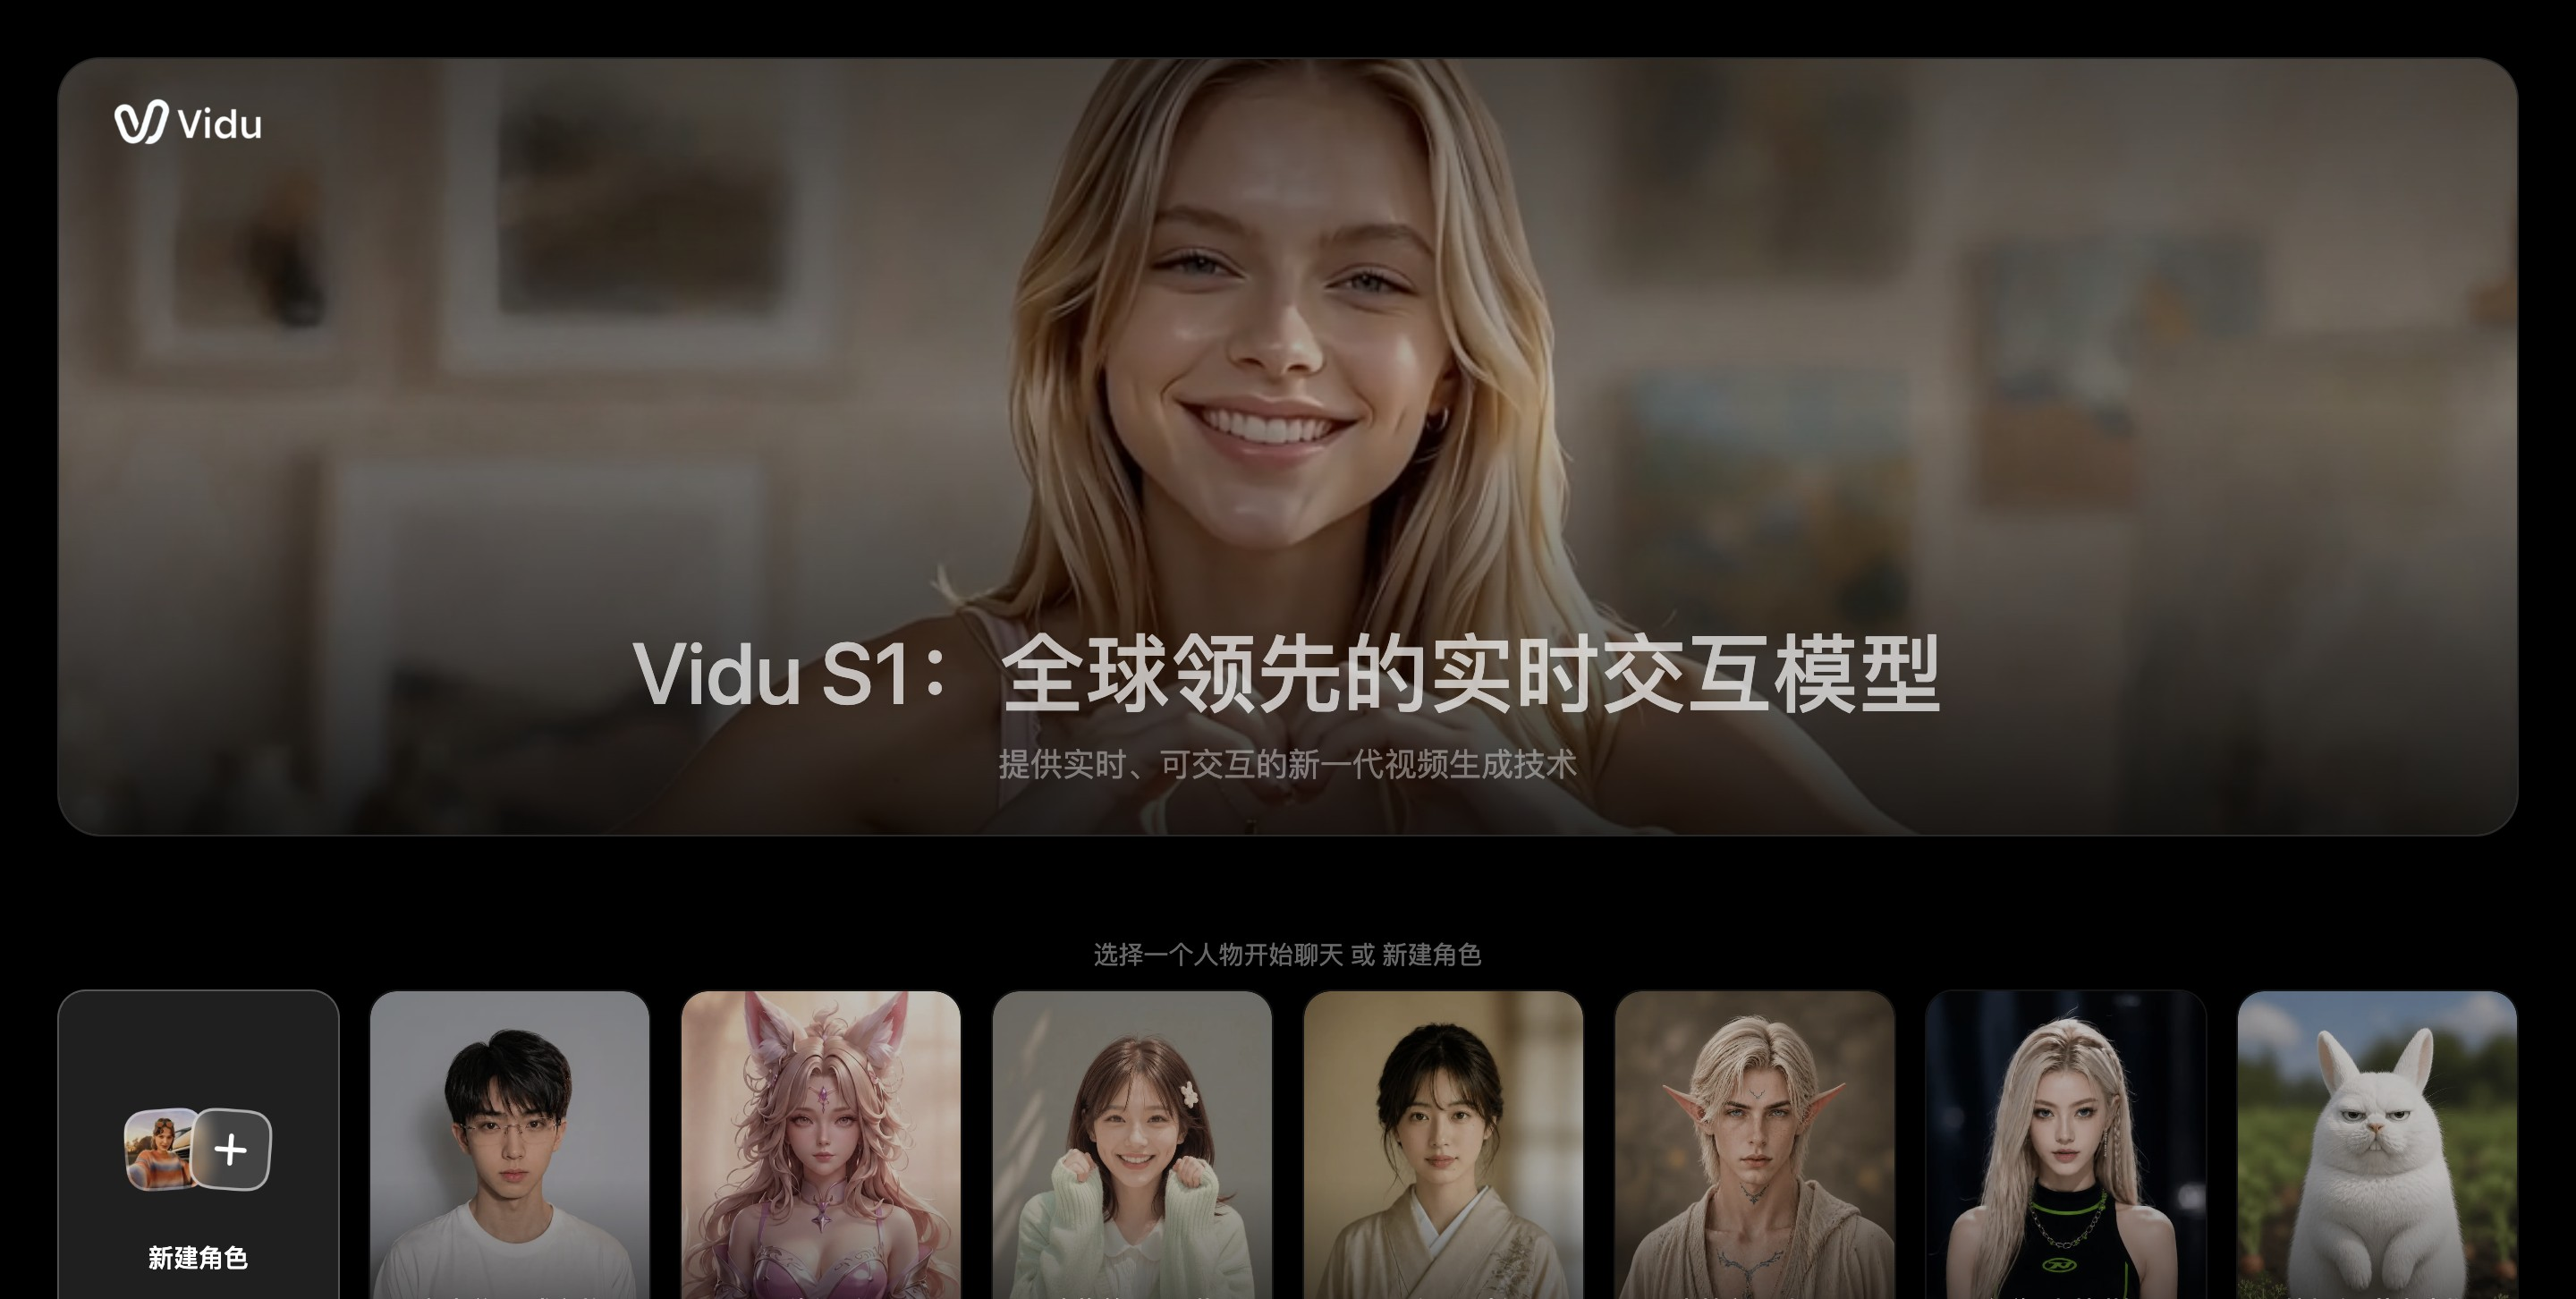
Main features of Vidu S1
-
Real-time bidirectional video interaction: Supports real-time conversation with AI characters like a video call, understanding, generating, and outputting simultaneously, and users can interrupt at any time and change instructions, with the model adjusting the picture content immediately.
-
Voice-driven full-dimensional behavior: Voice not only drives lip movements, but also understands semantics, intent, and emotion, generating matching expressions, eye contact, gestures, and complete body movements in real time.
-
Unlimited-duration real-time generation: Based on an autoregressive diffusion (AR + Diffusion) architecture, it can generate continuously for hours, while character identity and actions remain consistent, without drift or collapse.
-
540P HD real-time image quality: Supports 540P (960×540) resolution and 25 FPS real-time generation, up to 42 FPS, and can run smoothly on consumer-grade GPUs.
-
Single-image zero-training character creation: No 3D modeling or specialized training is required. Upload one image (real person, anime, cute pet, etc.), and the model automatically understands the character's appearance and style and immediately enters interaction.
-
Custom voice timbre: Supports choosing system preset voice timbres or recording your own voice, achieving unified personalized visual appearance and sound.
-
Scene perception and understanding: After turning on the camera, the model can recognize environmental information such as the number of people and action states in the picture, and provide real-time feedback accordingly.
-
Streaming real-time response: Uses the TurboServe inference engine to achieve efficient streaming scheduling, ensuring a low-latency, highly stable continuous online interaction experience.
How to use Vidu S1
-
Access the experience entry point: Open the Vidu AI official website https://www.vidu.cn/vidu-stream,或下载「Vidu AI Pro」APP, or access development through the API platform.
-
Create a new character: Click 「New Character」, upload a first-frame image (supporting any image such as real people, anime, cute pets, game characters, etc.), and enter the character name and description.
-
Configure voice timbre: Choose a system preset voice timbre, or click 「Record Voice」 to record your own voice, achieving personalized unity of appearance and sound, then click submit when finished.
-
Start conversation: Choose a created character or preset character, grant microphone and camera permissions, and click 「Allow」 to enter the real-time interaction interface.
-
Real-time voice interaction: Issue voice commands directly through the microphone, and the character will understand the semantics in real time and synchronously generate corresponding lip movements, expressions, gestures, and full-body action feedback.
-
Adjust instructions at any time: Instructions can be changed at any time during the conversation (such as "make a heart shape", "push up glasses", "get angry", etc.), and the model will respond instantly and adjust the subsequent visuals accordingly.
-
Enable camera-enhanced interaction: After the camera is turned on, the model can recognize the number of people and their action states in the frame, and combine environmental perception to provide richer real-time feedback.
Vidu S1 official website address
-
Official website address:https://www.vidu.cn/vidu-stream
-
API platform:https://platform.vidu.cn/live/landing
-
Technical report:https://jt-zhang.github.io/files/Vidu_S1.pdf
Vidu S1's core advantages
-
Real-time bidirectional interaction: Upgraded from traditional offline finished video to video-call-level real-time conversation, users can interrupt and change instructions at any time, and the model responds instantly.
-
Voice-driven full-dimensional behavior: Breaks through the limitation of audio-driven lip sync, with voice directly controlling facial expressions, eye gaze, gestures, and full-body posture, achieving true "understands what is heard and moves accurately".
-
Unlimited duration stable generation: Based on an autoregressive diffusion architecture, it can sustain interaction for hours, with character identity and actions always remaining consistent, without drift or collapse.
-
High-image-quality, high-frame-rate real-time output: Supports 540P + 25FPS real-time generation, up to 42FPS, placing it at the industry forefront among similar real-time interaction solutions.
-
Runs on consumer-grade hardware: Powered by the collaborative optimization of TurboDiffusion and TurboServe, it can achieve smooth real-time interaction on consumer-grade GPUs, with a low deployment threshold.
-
Create a character from a single image with zero training: No 3D modeling or specialized training is required; upload any image (real person, anime, cute pet, etc.) to create an interactive digital human in seconds.
-
Long-term character consistency: Maintains unified character appearance, style, and voice during long-duration real-time generation, solving the pain points of traditional video generation being prone to collapse and distortion.
-
Scene awareness capability: Supports camera input, can recognize environmental information such as the number of people and action states in the frame, achieving physical environment perception beyond voice instructions.
-
Leading quantitative metrics: Outperforms mainstream solutions such as OmniAvatar and HeyGen on core audio-driven digital human evaluation metrics such as CSIM (0.9192) and Sync-D (7.8470).
Comparison of Vidu S1 with similar competitors
| Comparison dimension | Vidu S1 | HeyGen | D-ID |
|---|---|---|---|
| Core positioning | Real-time interactive video foundation model | AI real-time digital human and video generation platform | AI digital human and real-time conversational agent platform |
| Interaction mode | Video-call-level real-time bidirectional interaction, can interrupt and change instructions at any time | Real-time conversational digital human (Streaming Avatar) | Real-time conversational agent (D-ID Agents) |
| Instruction response depth | Voice semantics + emotion drive full-body behavior (facial expressions, eye gaze, gestures, posture) | Mainly responds to dialogue text, with actions mostly preset/lip sync | Mainly responds to dialogue content, with limited action range, mainly head and lip sync |
| Real-time image quality | 540P / 25FPS (up to 42FPS) | High-definition output, but real-time interaction frame rates are usually lower | Prioritizes smoothness, with real-time resolution usually below 720P |
| Character creation | Single image, zero training, instant startup, supports real people/anime/cute pets | Requires uploading video material for training or selecting a platform template character | Just upload a single photo, no training required |
| Continuous interaction capability | Unlimited duration, continuous generation for hours, long-term character identity consistency | Single real-time session duration is limited, requires reinitialization | Single real-time session duration is limited |
| Deployment threshold | Can run locally on consumer-grade GPU | Pure cloud SaaS, no local computing power required | Pure cloud SaaS, no local computing power required |
| Scenario focus | AI companionship, game NPCs, interactive livestreaming, virtual idols, XR | Enterprise training, marketing videos, cross-border e-commerce customer service | Intelligent customer service, brand marketing, online education |
| Technical approach | Autoregressive diffusion (AR+Diffusion) frame-by-frame real-time generation | Real-time rendering based on a trained digital human model | Based on face reconstruction and speech-driven synthesis |
Application scenarios of Vidu S1
-
AI emotional companionship: Transform real-person photos, anime characters, or pet images into virtual companion characters capable of real-time conversation and emotional feedback, providing 24-hour online emotional interaction.
-
AI virtual idols and interactive livestreaming: Virtual streamers can respond in real time to bullet comments and donation instructions, and adjust performance movements and expressions in real time according to audience voice, creating a truly real-time interactive livestreaming experience.
-
Game NPCs and role-playing: Game characters no longer rely on preset scripts; they can understand players' voice instructions in real time and generate corresponding actions and dialogue, greatly enhancing immersion and freedom.
-
Brand digital humans and virtual customer service: Enterprises can quickly transform brand IP into real-time online digital employees for reception and consultation, product presentations, intelligent customer service, and other scenarios, reducing labor costs.
-
Online education and intelligent practice partners: Images such as historical figures and subject tutors can be "awakened" for real-time Q&A and interactive teaching; in language learning, real-time conversation practice partner characters can be created.
-
XR / metaverse experience: Provides low-latency, high-frame-rate real-time digital human rendering capabilities for VR/AR devices, supporting real-time social interaction and virtual meetings in the metaverse.